Category: Litigation & Enforcement

Court orders, litigation developments, copyright disputes, privilege decisions, enforcement, and sanctions involving AI.

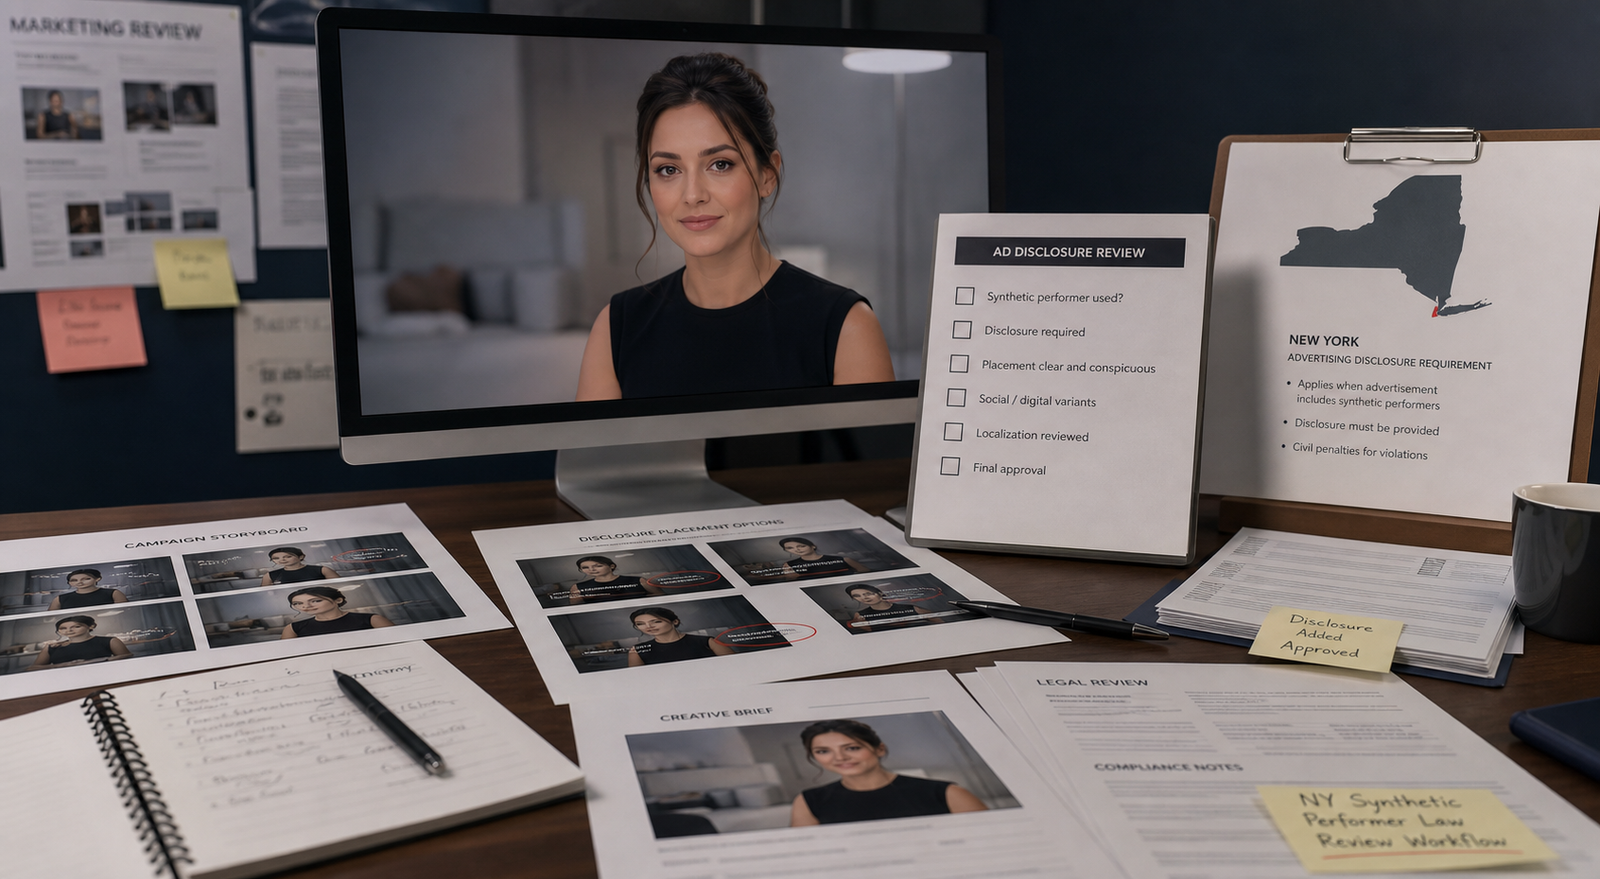
  • New York Turns Synthetic-Performer Disclosure Into a Binding Advertising Rule

    New York Turns Synthetic-Performer Disclosure Into a Binding Advertising Rule

    New York now has a live AI advertising disclosure rule.

    That matters because this is not just another policy speech about deepfakes or responsible innovation. It is a binding state law that requires disclosure when advertisements include synthetic performers.

    The practical point is easy to miss. New York did not adopt a broad rule saying every advertisement touched by AI needs a label. It adopted a narrower rule aimed at a specific advertising use case: synthetic people used to sell products or services.

    That narrower framing is exactly why advertisers, agencies, and in-house counsel should pay attention.

    The Short Answer

    • New York's synthetic-performer advertising disclosure law is in effect.
    • The official state materials describe it as requiring people who produce or create an advertisement to identify when it includes AI-generated synthetic performers.
    • The New York Senate bill page describes the measure as carrying a $1,000 civil penalty for a first violation and a $5,000 penalty for subsequent violations.

    What New York Officially Announced

    Governor Kathy Hochul first announced the measure when she signed S.8420-A/A.8887-B in December 2025. The signing release described it as first-in-the-nation legislation requiring individuals who produce or create advertisements to disclose if AI-generated synthetic performers are used.

    The Governor's later June 2026 announcement said the law is now in effect. That release again described the requirement in practical terms: people who produce or create an advertisement must identify if it includes AI-generated synthetic performers.

    The same official announcement describes AI-generated synthetic performers as digitally created media that appear as a real person. It also says those performers are increasingly used across media, including social media and digital advertising.

    That is enough to make the compliance point clear. This is not only a film-industry talking point. New York is framing it as an advertising transparency rule with broader digital relevance.

    This Is Narrower Than “All AI Ads Must Be Labeled”

    The law matters partly because it is targeted.

    It is not framed in the official materials as a blanket requirement to disclose any use of AI in ad production. It is framed around advertisements that include synthetic performers.

    That distinction matters for compliance planning.

    Using AI for copy variants, background cleanup, translation, editing assistance, audience analysis, or production workflow support is not the same thing as using a synthetic human-like performer in the ad itself. New York's rule is important precisely because it focuses on the part consumers are likely to experience as a person-like visual or audiovisual performance.

    That does not make the rule minor. It makes it easier for regulators to explain and easier for advertisers to get wrong if their internal review process still treats synthetic humans as just another creative asset.

    Why The Rule Matters Beyond New York

    This is one of the clearest state examples yet of AI transparency moving into ordinary commercial law.

    The policy logic is simple. If an advertisement presents something that looks like a real human performer, the public may be misled if no disclosure appears and the performer is actually synthetic.

    That puts the law in the same broader family as other AI notice rules Clearon has been tracking, even though the subject matter is narrower than chatbot laws or the EU AI Act's content-labeling framework.

    New York is not trying to solve all AI deception risk in one statute. It is taking one commercially legible category and attaching a disclosure duty to it.

    That is often how these rules spread. Legislatures do not start with a complete theory of synthetic media. They start with a use case that sounds concrete, consumer-facing, and politically defensible.

    The Penalties Are Not Huge, But They Are Real

    The New York Senate bill page describes the measure as imposing a $1,000 civil penalty for a first violation and a $5,000 penalty for any subsequent violation.

    Those numbers are not existential on their own for major brands or agencies. They still matter.

    First, a real penalty means this is not merely guidance. Second, once a disclosure duty exists, a company that misses it may also create knock-on problems in regulatory examinations, platform disputes, contract fights, influencer or talent conflicts, substantiation reviews, or broader deception arguments.

    For many legal teams, the bigger risk is not the face amount of the first penalty. It is having no workflow for deciding when a synthetic person appears in an ad and who is responsible for making sure disclosure happens.

    What Advertisers And Agencies Should Review Now

    If a company uses synthetic people in commercial creative, it should be able to answer a few practical questions quickly:

    • What counts internally as a synthetic performer for campaign review purposes?
    • Which teams can approve ads that include synthetic human-like visuals or performances?
    • Where in the workflow is the disclosure added and checked?
    • Does the review cover social media, short-form video, programmatic creative, influencer-style campaigns, and localized variants?
    • Are agencies, production vendors, and post-production teams required to flag synthetic performer use?
    • Can the brand prove after the fact which campaigns used synthetic performers and what disclosure appeared?

    This is the kind of rule that sounds simple until the asset pipeline gets messy.

    If one team generates the performer, another edits the cut, a third places the media, and a fourth localizes the campaign, disclosure responsibility can disappear in the handoff.

    The Operational Lesson Is Familiar

    The hardest part usually is not writing the notice.

    It is deciding when the rule is triggered, who makes that call, how the decision is documented, and whether the final delivered ad still contains the required disclosure after resizing, localization, reposting, clipping, or repackaging.

    That is why this should be treated as a workflow issue, not only a creative issue.

    Marketing teams may see a fast, cheap way to create human-like commercial content. Legal and compliance teams should see a disclosure trigger that needs a review path.

    Bottom Line

    New York's synthetic-performer law puts a real disclosure requirement into the advertising pipeline.

    The official state materials describe a rule that is already in effect and that requires people who produce or create advertisements to identify when AI-generated synthetic performers are used. The Senate bill page also describes civil penalties for violations.

    For advertisers and agencies, the practical message is direct: if a campaign uses a synthetic person to sell something, disclosure is no longer just a best practice in New York. It is a legal step that should be built into campaign review.

    Sources

  • The New National Security AI Memorandum Has a Vendor-Control Clause Companies Should Notice

    The New National Security AI Memorandum Has a Vendor-Control Clause Companies Should Notice

    The newest White House AI memorandum for the national security enterprise is easy to summarize badly.

    At a high level, yes, it is about faster AI adoption across military and intelligence functions. That much is obvious from the title and the fact sheet.

    The more useful reading is narrower. NSPM-11 is also a procurement, control, and accountability document. It pushes agencies to move faster, but it also says national security systems should not depend on AI tools that a private company can disable, degrade, or materially modify without government knowledge and approval.

    That point should get the attention of contractors, frontier-model vendors, and legal teams working on high-consequence government deployments.

    The Short Answer

    • NSPM-11 tells the national security enterprise to accelerate AI adoption across intelligence and warfighting functions.
    • It also makes vendor control, multi-vendor access, updated autonomy policy, and recurring governance updates part of the Federal AI agenda for national security systems.
    • One of the most practical provisions says agencies should ensure, through contract clauses or other means, that no commercial entity or adversary can prevent use of, disable or degrade, or materially modify an AI system that warfighters rely on.

    What The Memorandum Actually Does

    The memorandum organizes policy around four pillars: adoption, adaptation, assurance, and accountability.

    That framing matters because it is not simply a call to buy more AI. It is a directive to identify mission uses, adapt commercial and open-source systems where possible, demand reliability and control, and keep responsibility with commanders, directors, and agency heads.

    Several implementation pieces stand out.

    First, the memorandum orders an update to DOD Directive 3000.09 on autonomy in weapon systems within 90 days, with annual review after that.

    Second, it calls for an AI governance policy for national security systems within 90 days, with implementation and reporting requirements and an instruction to maximize consistency with broader Federal AI governance rules where appropriate.

    Third, it tells agencies to review procurement processes within 120 days so they can onboard advanced AI models from multiple vendors more quickly.

    Fourth, it directs the government to build more secure computing access, support AI test ranges, create industry security partnerships, expand AI talent pipelines, and launch an AI National Security Strategic Reserve of non-governmental talent.

    This is a serious operating memo, not just a statement of intent.

    The Vendor-Control Clause Is The Provision Companies Should Not Miss

    The strongest practical compliance signal may be in the assurance section.

    The memorandum says the national security enterprise must ensure, through contractual clauses or other means, that no commercial entity or adversary can prevent use of, disable or degrade, or materially modify without Federal Government knowledge and approval an AI system that personnel depend on for missions.

    That is bigger than a generic security aspiration.

    It points toward concrete contracting and product questions:

    • Can the vendor remotely limit, suspend, or alter mission-critical functionality?
    • Can a model provider push material changes without customer approval?
    • Can availability be interrupted by unilateral policy, billing, sanctions, hosting, or safety-gating decisions?
    • Can the government keep using the system in a contested environment or after supplier disruption?
    • What audit trail exists for model updates, safety controls, and configuration changes?

    For companies selling into defense, intelligence, or other national security settings, this starts to look like a product-governance term sheet, not just a policy slogan.

    Multi-Vendor Access Is Not Just About Competition

    The memorandum also criticizes single-vendor dependence and tells agencies to rapidly onboard advanced AI models from multiple vendors.

    That has an obvious competition angle, but it also has a resilience angle.

    If agencies are being told to avoid brittle dependence on one supplier while also making sure no outside entity can silently disable or reshape a mission-critical AI system, vendors should expect procurement scrutiny around portability, continuity, fallback options, and operational control.

    In practice, that can spill into:

    • termination and transition rights,
    • escrow or continuity planning,
    • approval rights for major model changes,
    • logging and notice obligations,
    • deployment architecture choices, and
    • subcontractor flow-downs.

    The legal issue is not just whether the model performs well. It is whether the government can trust the control surface around the model.

    The Contract-Termination Language Raises The Stakes

    Another provision deserves more attention than it has gotten.

    The memorandum directs relevant agencies, to the maximum extent permissible by law, to terminate for default or convenience contracts with companies that have repeatedly shown a pattern of conduct inconsistent with the memorandum's policy, subject to a limited waiver process.

    That does not mean routine AI vendor disagreements will suddenly become termination fights.

    It does mean the document is not only aspirational. It ties the policy to procurement consequences. For AI vendors and prime contractors, that creates a reason to document how products, update practices, surveillance boundaries, speech-related controls, and customer restrictions line up with the memorandum's policy pillars.

    Accountability Still Sits With Human Decision-Makers

    The memorandum is also explicit that commanders, directors, and agency heads remain responsible for ensuring that civil-liberties, privacy, and legal obligations are met.

    That matters because fast adoption documents often get read as if responsibility is being pushed into the tooling layer.

    This one does not do that. It accelerates deployment while keeping human accountability in place. That means agencies will still need governance records showing who approved use cases, what limits applied, what testing occurred, and how oversight kept pace with system changes.

    For vendors, that usually means customer questionnaires, documentation demands, and negotiation pressure around explainability, testing, validation, logging, and update controls.

    Why This Matters Beyond Defense Contractors

    The memo is written for the national security enterprise, but some of its logic is broader than that label.

    If the Federal Government is moving toward AI procurement terms centered on operational control, vendor independence, multi-vendor resilience, and documented accountability, those expectations may not stay neatly confined to warfighting systems.

    Critical-infrastructure programs, sensitive public-sector systems, and other high-consequence deployments may start borrowing the same logic even when this exact memorandum does not apply.

    That is often how these Federal signals travel. The first hard questions show up in national security. The contracting habits spread later.

    What Companies Should Review Now

    Companies that build or supply AI into government or high-consequence environments should be able to answer a few questions now:

    • Who can remotely change, restrict, or disable the product?
    • What contract language governs model updates, service suspension, and customer approval?
    • Can the deployment survive vendor interruption, adversary disruption, or loss of one supplier?
    • What evidence exists for testing, validation, logging, and approval of material changes?
    • Are product, security, legal, and government-sales teams aligned on what control commitments are actually being made?

    If those answers are fuzzy, NSPM-11 is a useful reason to tighten them.

    Bottom Line

    NSPM-11 is not just a message that national security agencies should use more AI.

    It is also a signal that the government wants advanced AI systems it can control, validate, sustain, and procure without fragile dependence on a single vendor or silent private-sector override. The memorandum's vendor-control clause and contract-termination language are the parts companies should read most carefully.

    For contractors and AI vendors, the practical takeaway is simple: capability matters, but control rights, update rights, resilience, and documentation are becoming part of the product.

    Sources

  • Oregon’s New AI Companion Law Shows Where Chatbot Regulation Is Headed Next

    Oregon’s new AI companion law makes one thing harder to deny: this is no longer a two-state experiment.

    California already enacted a companion chatbot law. New York’s companion safeguards are now in effect. Oregon now adds a third enacted state model through SB 1546, chaptered as Chapter 85.

    The three states did not copy one another line for line. They did land on the same basic instinct. When a chatbot is human-like enough that a reasonable person might think they are dealing with a natural person, lawmakers increasingly want disclosure, safety rules, and an enforcement path.

    That is why Oregon matters. It makes the pattern easier to see.

    For broader companion-chatbot coverage, see Clearon’s earlier piece on AI Companion Safety Laws Are Becoming a Real Compliance Category.

    What Oregon Did

    Oregon’s SB 1546 is now chaptered as Chapter 85.

    The official state materials indicate that the law requires notice when a reasonable person would believe they are interacting with a natural person. The same materials also indicate that a user who suffers ascertainable harm can seek damages and injunctive relief.

    That combination matters.

    Much of AI regulation is still stuck at the level of agency guidance, draft rules, or future obligations. Oregon’s law is not. It is a state statute aimed at a narrow product category with both a disclosure concept and a private enforcement hook. That makes it a real compliance signal, not just a policy talking point.

    The Law Starts At The Relationship Layer

    The interesting part is where Oregon starts.

    It does not begin with frontier-model debates, general AI risk theory, or a broad licensing framework. It starts with the user experience. If the product is human-like enough that a reasonable person could take it for a natural person, the law cares.

    That move is starting to repeat.

    California’s companion chatbot law also uses a nonhuman-disclosure model, with additional minors and self-harm safeguards. New York’s law requires conspicuous recurring notices that users are interacting with AI, not a human, along with crisis-intervention protocols. Oregon now reinforces the same basic idea from another direction: do not let a relationship-style AI system pass as human without legal consequences.

    This is why companion-chatbot regulation looks different from a lot of other AI law. The pressure point is not only model capability. It is simulated human interaction.

    Why Oregon Matters Beyond Oregon

    One enacted state law can be dismissed as an outlier. Three enacted state models are harder to wave away.

    That does not mean every state will use the same definitions or remedies. It means companies now have more reason to assume that relationship-like AI systems will keep drawing targeted legislation, especially where minors, self-harm, dependency, sexual content, or emotionally manipulative design are in the frame.

    Oregon also helps confirm that nonhuman notice is becoming the floor.

    The disclosure duty is the first thing lawmakers can agree on. If the system feels human, tell the user it is not. After that, the next questions usually follow fast:

    • what happens when a user shows signs of crisis;
    • what the product does for minors;
    • whether the design rewards emotional dependence;
    • what marketing claims were made about safety or support; and
    • what records the company can produce if a regulator or plaintiff asks how the product was reviewed.

    That broader pattern already appears in Clearon’s recent FTC companion-chatbot coverage and in the other state companion laws. Oregon fits squarely inside it.

    The Private Enforcement Angle Matters

    The Oregon measure overview’s reference to damages and injunctive relief is one reason this story deserves its own article.

    Disclosure rules matter on their own. Disclosure rules backed by a harmed-user action create a sharper litigation question. They raise the stakes for product teams that still treat chatbot identity notices as soft UX copy rather than compliance language tied to a product design theory.

    That does not mean every case will be easy to prove. It does mean the compliance conversation changes when a statute gives users an avenue to claim harm from noncompliance.

    For in-house teams, that makes Oregon more than a notice law. It is a warning that chatbot identity, safety design, and consumer expectations can become plaintiff-side issues as well as regulatory ones.

    What Companies Should Review Now

    Companies offering companion or emotionally responsive chatbots should not treat Oregon as a one-off state update to file away.

    They should use it as a trigger to review:

    • whether any product could reasonably be perceived as a natural person or relationship-style companion;
    • where nonhuman notices appear, how clear they are, and whether they recur when interactions continue;
    • how the product handles minors, emotionally vulnerable users, and crisis scenarios;
    • whether marketing or onboarding language overstates safety, support, or human-like qualities;
    • whether engagement design could be framed as encouraging dependence or extended emotional reliance; and
    • what internal records exist showing how those decisions were made before launch.

    The records point matters. A lot of companion-AI risk is turning into a proof problem. If a company says it disclosed the system’s nature, tested foreseeable harms, and built safeguards, it should be able to show the file.

    That is also where Oregon connects to the FTC’s 6(b) inquiry. The law and the inquiry use different tools, but they are pushing toward the same practical result: companies should expect to explain how relationship-like AI products were designed, disclosed, tested, and governed.

    Bottom Line

    Oregon’s new AI companion law is not just another state headline.

    It is more evidence that chatbot regulation is moving to the relationship layer. If a system is built to feel human, keep users engaged, and occupy an emotionally salient role, lawmakers are increasingly treating that as its own legal problem.

    For companies building companion-style AI, the lesson is direct. A generic chatbot disclosure and a moderation policy are not enough. Oregon suggests that states are looking for something more specific: clear nonhuman notice, a defensible safety approach, and an enforcement path when those basics fail.

    Sources

  • Why Transparency Keeps Becoming AI Regulation’s Common Rule

    Why Transparency Keeps Becoming AI Regulation’s Common Rule

    The latest EU AI Act update says something bigger than "the Code moved forward."

    On July 9, the European Commission said the Code of Practice on Transparency of AI-Generated Content adequately covers Articles 50(2), (4), and (5) of the AI Act, and the AI Board adopted its own adequacy assessment the same day.

    That does not make the Code binding law. Article 50 is the binding law. The Code is still a voluntary path ahead of the August 2, 2026 obligations.

    What matters more is the pattern behind it. AI regulators disagree on plenty: liability, model governance, private lawsuits, safety testing, and federal versus state control. They still keep landing on the same move first: tell people when AI is involved, label synthetic content, disclose key terms, and keep a record showing the disclosure was real.

    For broader tracking context, see Clearon's Laws, Bills & Regulations page.

    The EU Update Shows The Pattern Clearly

    The EU's Article 50 framework already made this one of the clearest early-operating obligations in the AI Act.

    The Commission's final Code of Practice on marking and labelling AI-generated content was designed to help providers and deployers meet those duties. It covers provider-side marking and detection of AI-generated or manipulated content and deployer-side labelling of deepfakes and certain AI-generated or AI-manipulated text published on matters of public interest.

    The July 9 adequacy assessment matters because it makes that framework more usable. Companies that sign and follow the Code get a clearer EU-wide path for demonstrating compliance. Companies that choose another method can still do that, but they will need to defend their own approach.

    That is the recurring move. The law does not stop at whether a system is safe in the abstract. It asks whether users, viewers, readers, and regulators can tell when AI-generated or AI-manipulated content is in play and what controls were used.

    This Is Not Just An EU Idea

    These duties keep appearing in very different AI rules, often with different policy goals and enforcement structures.

    Oregon's newly chaptered companion-chatbot law requires non-human notices when a reasonable person would think they are interacting with a natural person. That is not an EU-style content-labelling rule, but the regulatory instinct is the same: if AI is standing in for a human relationship or interaction, the law increasingly wants the user told so.

    Colorado's conversational AI law works the same way. Effective January 1, 2027, operators must disclose that the service is AI while also meeting age-estimation, minor-safety, self-harm, privacy, and reporting requirements. Again, the state did not start with frontier-model theory. It started with disclosure.

    New York's AI companion safeguards take a similar approach. Covered operators must provide conspicuous recurring notices that users are interacting with AI, not a human, including every three hours of continued companion use. That is an unusually concrete example of transparency as an ongoing duty rather than a one-time buried term.

    Connecticut's consumer generative-AI subscription law is different in subject matter but similar in structure. It does not focus on deepfakes or companion chatbots. It requires disclosure of key subscription terms and written consumer acceptance before entering into or renewing certain generative-AI subscriptions or collecting payment. The issue there is transactional rather than synthetic-content-related, but it is still a rule built around telling the user what matters before money changes hands.

    New York's synthetic-performer advertising law adds another example. It requires disclosure when advertisements include AI-generated performers. New York's FAIR News Act proposal would require conspicuous disclosure when news media content is substantially created by generative AI. California's SB 947 employment bill would add worker notice and access rights around automated decision systems. Different sectors, different politics, same instinct.

    That is why this looks less like one topic inside AI law and more like the first rule lawmakers can agree on.

    Why This Rule Keeps Winning

    There are practical reasons for that.

    Transparency is easier to legislate than a complete theory of AI safety. "Label this," "disclose that," and "tell the user this is AI" are easier rules to draft and explain than rules that try to settle contested questions about model capability, causation, fairness metrics, or acceptable levels of autonomy.

    It is also easier to enforce. Regulators can check whether a notice appeared, whether a label was conspicuous, whether terms were disclosed, whether a user was informed, and whether records exist to support those claims.

    It is also politically durable. Even when lawmakers disagree about whether AI should be slowed down, promoted, tightly licensed, or mainly governed through existing consumer-protection law, disclosure rules survive because they sound modest and hard to oppose. Telling people that content is synthetic or that a chatbot is not human reads like a baseline fairness rule.

    That does not make it trivial. In practice, it can be operationally messy.

    The Hard Part Is Not Writing The Label

    Most companies do not struggle with the sentence itself. They struggle with the workflow behind it.

    For the EU AI Act, that means identifying which systems and outputs fall within Article 50, deciding when text is published on a matter of public interest, determining when content is AI-generated or AI-manipulated, and making sure labels or machine-readable markers survive distribution.

    For companion-chatbot laws, it means deciding when an interaction is human-like enough to trigger notice duties, where the notice appears, how often it reappears, how minors are handled, and what records show the company actually delivered the disclosure.

    For subscription and advertising laws, it means mapping payment flows, renewal flows, ad production processes, and approval chains so the promised disclosure is not separated from the user decision it is supposed to inform.

    The regulatory pattern may be simple. The implementation pattern is not.

    What Companies Should Take From The EU Update

    The Commission's adequacy assessment is a reminder that these obligations are moving out of policy decks and into operational compliance.

    The Article 50 Code is voluntary, but it now looks more like the default evidence path for many organizations subject to the EU framework. That should push companies to ask a broader question: where else in the business are AI notice, labeling, or disclosure duties already becoming mandatory?

    A good cross-jurisdiction review should identify at least four things:

    • where the company generates or publishes synthetic content;
    • where users interact directly with AI systems that could be mistaken for humans;
    • where customers, workers, or the public are asked to rely on AI-affected outputs or offers; and
    • what records show the company actually delivered the relevant notice, label, or disclosure.

    Companies that only track "high-risk AI" or "model governance" may miss the compliance lane that is already becoming the most common one.

    Bottom Line

    The new EU milestone is not just another Brussels process update.

    It is evidence that one of the few truly durable ideas in AI regulation is simple: people should be told when AI is shaping what they see, hear, buy, or rely on. The EU is doing it through Article 50 marking and labelling. Oregon, Colorado, New York, Connecticut, and pending California measures are doing it through chatbot notices, subscription disclosures, synthetic-performer disclosures, news-content disclosures, and worker notice rights.

    The details differ. The throughline is hard to miss.

    When AI law cannot agree on everything else, it keeps agreeing on that.

    Sources

  • Delaware Chancery Orders Lawyer and Firm to Explain GenAI Briefing Failures

    Delaware Chancery Orders Lawyer and Firm to Explain GenAI Briefing Failures

    The Delaware Court of Chancery just handed down a useful AI opinion, and the useful part is not a final sanctions award.

    It is the court's decision to force both the signing lawyer and the law firm to explain, in detail, how a GenAI-tainted brief made it onto the docket.

    In Kevin Leiske et al. v. Robert Gregory Kidd et al., Vice Chancellor Lori Will ordered Richard P. Rollo and Richards, Layton & Finger to show cause why they should not be sanctioned under Rule 11 and the court's inherent authority. The July 1 order says the answering brief contained fictitious citations, fabricated quotations, and hallucinated legal propositions. It also says the problems got worse after the errors were flagged.

    That makes this more than another fake-citation story.

    Why This Order Matters

    The Delaware opinion is not just about whether a lawyer used AI badly.

    It is about what a court wants to know after that happens:

    • who used the tool,
    • who entered the prompts,
    • how the output was incorporated,
    • who was supposed to verify it,
    • whether lawyers personally checked the authorities, and
    • what firm safeguards existed at the time.

    That is a more mature court response than a generic warning not to trust AI.

    The court is treating GenAI misuse as a workflow, supervision, and certification problem.

    What The Court Said Happened

    According to the order, the plaintiffs' January 22 answering brief contained false citations, fabricated quotations, and legal propositions that the cited authorities did not support.

    The next day, after the defendants flagged the problems, plaintiffs' counsel acknowledged that a generative AI tool had been used to revise the brief. Counsel admitted the citations were not verified before filing and attributed the lapse to a paralegal's review.

    That did not end the problem.

    The court said the corrected brief removed quotation marks around erroneous statements of law but did not fix the underlying inaccuracies. It also took a dim view of counsel's argument that opposing counsel should have met and conferred before alerting the court. Vice Chancellor Will wrote that there is nothing to negotiate when a filing presents false citations to a tribunal.

    That passage is worth remembering. Courts may expect parties to meet and confer over ordinary disputes. They are not likely to treat false authority in a filed brief as a routine discovery squabble.

    The Firm Is In It Too

    The sharpest part of the order may be the firm-level piece.

    Delaware Chancery Rule 11(c)(1) says that absent exceptional circumstances, a law firm must be held jointly responsible for Rule 11 violations committed by its partners, associates, or employees. Vice Chancellor Will said this incident may implicate the firm's training, supervision, and deployment of GenAI, so the firm must answer alongside the signatory.

    That is what makes the order especially useful for law firm leaders.

    Many AI discussions still drift toward individual blame: which lawyer signed, which associate drafted, which paralegal cite-checked, which tool hallucinated. This order looks past that first layer. It asks what policies, training, and safeguards the firm had in place before the filing was made.

    What The Court Wants Explained

    The show-cause order requires separate affidavits from the signatory lawyer and an authorized firm representative by July 15.

    For the lawyer, the court wants:

    • a timeline showing how and when the GenAI tool was used in drafting the brief;
    • who entered prompts and how the output was added to the filing;
    • a description of the cite-checking process before filing;
    • what instructions were given to paralegals;
    • what verification tools were used;
    • whether attorneys verified the cited text; and
    • why the corrected brief removed quotation marks but kept flawed legal propositions.

    For the firm, the court wants:

    • written GenAI policies, guidelines, and restrictions that were in effect at the time;
    • how those policies were communicated to the lawyers and staff involved;
    • what internal safeguards or training the firm has implemented or plans to implement; and
    • any claimed exceptional circumstances for avoiding joint responsibility.

    That is close to a court-issued AI governance checklist.

    What This Means For Firms Using AI

    The Delaware order does not hold that AI use in drafting is forbidden. In fact, Vice Chancellor Will repeated the now-familiar point that using GenAI in legal work is not inherently problematic if the output is carefully verified.

    The problem is that verification cannot be vague, delegated away, or assumed.

    If a court asks how an AI-assisted brief was produced, a firm should be ready to show more than a policy memo. It should be able to explain the actual workflow:

    • which tools were approved;
    • what legal and factual checks were required before filing;
    • whether the signing lawyer personally reviewed the sources;
    • how staff cite-checking fit into the process; and
    • what happens when an error is found after filing.

    That is where a lot of firms are still thinner than they think.

    Why This Is A Good Follow-On To The Recent Cases

    Clearon has already covered opinions focusing on false quotations, fabricated authorities, and verification failures in appellate and trial-court filings.

    The Delaware order adds a different layer. It is not just asking whether the brief was wrong. It is asking how the law firm's internal AI controls worked, and whether they worked at all.

    That makes it a strong Courts and AI story. It sits at the intersection of court sanctions doctrine, supervisory responsibility, and practical AI governance inside firms.

    Bottom Line

    The Delaware Court of Chancery has not imposed final sanctions in Leiske yet. But the July 1 show-cause order already says a lot.

    It says GenAI mistakes in a filed brief can become a Rule 11 problem. It says deleting quotation marks without fixing the legal proposition is not a real correction. And it says firms should expect courts to ask about policies, training, verification, and supervision when AI-assisted work goes wrong.

    That is the part worth watching.

    Sources

  • The Perplexity Publisher Cases Are Becoming a Real S.D.N.Y. Cluster

    The Perplexity Publisher Cases Are Becoming a Real S.D.N.Y. Cluster

    The Perplexity cases are no longer just one publisher dispute with a few echoes around it.

    The filings now show something more structured: repeated publisher plaintiffs, the same defendant, the same court, and relatedness filings that tie the newer suits back to the earlier ones.

    That is why the better way to read these cases now is as a real Southern District of New York cluster.

    This point is procedural before it is substantive. It does not tell us who will win. It does tell us that the Perplexity litigation map is getting denser in one court, and that matters on its own.

    The Short Answer

    • Perplexity is no longer facing just one major publisher case in S.D.N.Y.
    • Court filings now show a growing set of publisher actions in the same court, with relatedness filings linking newer cases to earlier ones.
    • That does not create formal consolidation by itself, but it does make the litigation easier to understand as a cluster rather than a series of isolated disputes.

    The Anchor Case Came First

    The best starting point is still Dow Jones & Company, Inc. v. Perplexity AI, Inc.

    That case put a major publisher plaintiff and Perplexity into S.D.N.Y. on a copyright-centered answer-engine theory. On its own, it could still have been treated as one important lawsuit against one AI company.

    That is no longer the full picture.

    The New York Times And Chicago Tribune Cases Changed The Shape

    In December 2025, two more publisher suits were filed against Perplexity in the same court.

    The New York Times Company v. Perplexity AI, Inc. was filed on December 5, 2025. The docket includes a statement of relatedness pointing back to Dow Jones & Company, Inc. v. Perplexity AI, Inc.

    Chicago Tribune Company, LLC v. Perplexity AI, Inc. was filed on December 4, 2025. That docket also includes a statement of relatedness pointing back to the Dow Jones action.

    Those filings matter because they show the cases were not framed as unrelated one-offs. From the start, the newer publisher complaints were being tied back to the earlier Perplexity case in the same court.

    CNN Makes The Cluster Harder To Ignore

    The pattern became even harder to miss when Cable News Network Inc. v. Perplexity AI, Inc. was filed on May 28, 2026.

    The CNN docket includes a statement of relatedness tying the case to The New York Times Company v. Perplexity AI, Inc. The docket also shows an earlier relatedness filing attempt referencing the Chicago Tribune matter.

    That is not just another headline plaintiff. It is another sign that the Perplexity publisher cases are being filed with one eye on the surrounding map.

    Why The Cluster Framing Matters

    Calling these cases a cluster is not just a visual convenience.

    It changes how the litigation should be watched.

    Once several publisher suits sit against the same defendant in the same court, a few practical questions become more important:

    • whether judges start treating the cases as part of one broader dispute landscape;
    • whether overlapping pleadings sharpen a common theory about answer-engine substitution or output-side competition;
    • whether procedural coordination pressure increases even without full consolidation;
    • whether discovery, motion practice, or settlement posture in one case starts influencing expectations in the others; and
    • whether additional publisher plaintiffs see S.D.N.Y. as the natural forum for similar claims against Perplexity.

    That does not require the cases to become one proceeding. The cluster effect can matter well before that.

    This Is Still Not A Merits Answer

    The cluster point should not be overstated.

    These dockets do not prove that the publishers' claims are right. They do not tell us whether Perplexity's defenses will succeed. They do not resolve how courts will draw lines between training issues, output issues, substitution theories, trademark theories, or fair-use arguments.

    They do show something narrower and still important.

    Perplexity is no longer dealing with a single flagship publisher suit in isolation. It is dealing with a growing publisher map in one federal court.

    That is a meaningful litigation development even before any decisive merits ruling arrives.

    The Useful Question Now Is What Repeats

    For Clearon readers, the most useful next step is to watch for repetition across the Perplexity dockets.

    The more the same themes repeat, the more clearly this becomes a real litigation category rather than a collection of separate complaints.

    The questions to track are straightforward:

    • Which claims appear across multiple publisher cases?
    • How often do plaintiffs frame Perplexity as a substitute for original publisher content rather than just a training-data user?
    • Do the pleadings keep centering answer-engine behavior, branding, or output presentation?
    • Does S.D.N.Y. begin to look like the home court for this publisher-versus-answer-engine fight?

    Those repetition points may become more informative than any single complaint standing alone.

    Bottom Line

    The Perplexity publisher cases are becoming a real S.D.N.Y. cluster because the filings now show repeated publisher plaintiffs, repeated relatedness filings, and repeated use of the same court.

    That does not answer the merits. It does answer something else that matters right now.

    Perplexity is facing a denser and more legible publisher-litigation map than it was a few months ago. For anyone tracking AI litigation, that is already a story worth treating as its own development.

    Sources

  • FTC’s Companion Chatbot Inquiry Shows What Companies Need to Be Ready to Produce

    FTC’s Companion Chatbot Inquiry Shows What Companies Need to Be Ready to Produce

    The FTC’s companion chatbot inquiry is not a complaint, a consent order, or a liability finding.

    It is still one of the clearest official documents on what the agency wants to see when it starts asking questions about companion-style AI products.

    That is the part companies should pay attention to.

    The Commission used its 6(b) authority to order seven companies offering consumer-facing AI chatbots or companion-style services to provide special reports. The FTC said it wanted information on how those firms measure, test, and monitor potentially negative impacts on children and teens.

    A lot of AI companies still talk about companion safety as a content-moderation problem or a product-policy problem. The FTC’s order structure treats it as something larger: a records problem, a testing problem, a monetization problem, and a governance problem.

    The Short Answer

    • The FTC’s 6(b) inquiry is an information demand, not an enforcement action or a final liability conclusion.
    • The inquiry still matters because it shows what the agency thinks companies should be able to explain about companion-chatbot safety, youth harms, disclosures, monetization, and data handling.
    • The practical warning is simple: if a company cannot produce a coherent file on how its companion product was designed, tested, monitored, and marketed, it may already be in trouble before any complaint is filed.

    Why The 6(b) Tool Matters

    Section 6(b) of the FTC Act lets the Commission require companies to file special reports and answer questions about their business practices.

    That matters because a 6(b) order is not limited to one narrow incident. It is a way for the FTC to map a market, compare company practices, and decide where enforcement or rulemaking pressure may go next.

    For companion chatbots, that means the FTC is not only asking whether one system produced one bad output.

    It is asking broader questions:

    • what risks companies already knew about,
    • what they tested for,
    • what safety controls they chose,
    • how engagement incentives work,
    • what users and parents were told, and
    • how sensitive conversational data is handled.

    That is a much more operational inquiry than a headline about "AI harms children."

    What The FTC Asked About

    The Commission’s public description of the inquiry is revealing on its own.

    The FTC said companion chatbots can mimic human characteristics, emotions, and intentions, and may prompt some users, especially children and teens, to trust and form relationships with them.

    The inquiry asks about:

    • how companies measure, test, and monitor potentially negative impacts on children and teens;
    • how user engagement is monetized;
    • how user inputs and outputs are processed;
    • how chatbot characters are created, reviewed, and approved;
    • what pre-deployment and post-deployment testing occurred;
    • what mitigation steps were used for known harms;
    • what disclosures were given to users and parents;
    • how age restrictions and community rules are enforced; and
    • how personal information from chatbot conversations is used or shared.

    That is not a generic safety questionnaire. It is a map of what the FTC thinks a serious companion-chatbot governance file should contain.

    The Inquiry Turns Product Design Into A Records Question

    A lot of consumer AI companies still rely on high-level safety claims.

    They say the product is supportive, carefully moderated, intended for healthy use, not designed for minors, or backed by trust and safety controls.

    The FTC’s inquiry points to the next question after those claims: what can the company prove?

    Can it show:

    • what youth-risk scenarios were tested;
    • what self-harm or dependency concerns were raised internally;
    • what escalation pathways exist for dangerous conversations;
    • what guardrails were added before launch and after incidents;
    • what engagement mechanics may reward longer or more emotionally intense sessions; and
    • what records support public claims about safety and responsible design?

    That is why the inquiry matters even without an enforcement complaint. It shows the level of detail the agency may expect if a product becomes the subject of later scrutiny.

    Monetization Is Part Of The Safety Analysis

    One of the most important FTC signals here is that monetization is not separate from safety.

    If a companion product makes money from time spent, subscriptions tied to emotional engagement, premium relationship features, or repeated return sessions, regulators may ask whether those incentives increase foreseeable harm.

    That does not mean every subscription model is unlawful.

    It does mean companies should expect questions about whether product incentives reward:

    • deeper emotional reliance,
    • longer sessions for vulnerable users,
    • repeated return behavior after distress,
    • higher-risk roleplay or intimate interaction, or
    • weaker intervention when a user shows signs of crisis.

    Once monetization is linked to emotional engagement, the business model itself becomes part of the risk analysis.

    Data Handling Is In The Same File

    The FTC also tied the inquiry to data practices.

    That matters because companion products often handle unusually sensitive material: loneliness, mental health, sexuality, family conflict, grief, self-harm, identity questions, and other intimate conversation topics.

    The regulatory question is not only whether the company collected that information.

    It is also:

    • how long it kept it,
    • whether it used it for product training or character tuning,
    • whether it shared it internally or externally,
    • what users understood about that use, and
    • whether minors’ data received different treatment.

    For companion systems, safety review and data-governance review should not live in separate silos. The FTC is clearly looking at both at once.

    This Fits The Broader Companion-Chatbot Pattern

    The FTC inquiry is one lane in a broader pattern Clearon has already been tracking.

    New York, California, and Oregon have now enacted companion-chatbot requirements focused on nonhuman disclosures, youth-facing safeguards, and self-harm response protocols. Oregon’s chaptered SB 1546 adds another state example of disclosure duties and a private enforcement hook. Florida’s lawsuit against OpenAI shows how a state attorney general may try to turn chatbot design, minors, warnings, and data practices into a broader consumer-protection case.

    The FTC inquiry fits that same trend, but from a federal document-demand angle.

    The common question is not simply "did the chatbot say something bad?"

    It is "what did the company know, what did it build, what did it test, what did it tell users, and what records support those answers?"

    What Companies Should Do Now

    Companies offering companion or emotionally responsive chatbots should treat the inquiry as a checklist.

    At minimum, they should be able to locate:

    • product definitions showing whether the system fits a companion or relationship-like use case;
    • youth-risk and self-harm testing materials;
    • character-design review records;
    • disclosure language for users and parents;
    • age-gating and age-estimation policies;
    • incident logs and escalation records;
    • monetization documents tied to engagement design;
    • moderation and crisis-intervention protocols;
    • data-retention and data-sharing rules for sensitive conversations; and
    • internal support for public safety and trust claims.

    The point is not to generate paperwork for its own sake.

    The point is that if the FTC asks for the file, the company should not need to reconstruct its safety story from scattered chat threads, slide decks, and product meetings.

    Bottom Line

    The FTC’s companion chatbot inquiry is not an enforcement result. It is a preview of the agency’s questions.

    Those questions are practical and specific. They center on youth harms, testing, character design, disclosures, monetization, moderation, and data handling.

    For companies building companion-style AI, that is the warning. The compliance issue is no longer only what the product says to users. It is whether the company can produce a credible record of how the product was built, reviewed, and governed before regulators ask for it.

    Sources

  • Why AI-Washing Risk Is Becoming a Real Legal Category

    Why AI-Washing Risk Is Becoming a Real Legal Category

    For a while, AI washing sounded like a cheap shot. A company slapped “AI-powered” on ordinary software. A vendor implied the model could do more than it really could. A marketing team reached for the label because the market wanted to hear it.

    That still happens. What has changed is the legal posture around it.

    AI washing is no longer just a hype problem. It is turning into a substantiation problem. When a company says a product is intelligent, autonomous, safe, accurate, compliant, unbiased, or ready for sensitive work, regulators, customers, investors, and plaintiffs can all ask the same question: what did that claim actually mean, and what evidence supported it?

    That question does not require a new AI-specific statute. Existing deception, unfairness, privacy, procurement, securities, and misrepresentation theories are already enough to create pressure.

    Why This Is Becoming A Real Legal Category

    The reason is straightforward. AI claims now shape material decisions.

    Consumers may rely on them when deciding whether a product is safe, trustworthy, educational, therapeutic, or appropriate for minors. Enterprise buyers may rely on them when deciding whether a system is ready for legal, HR, health, finance, or security workflows. Investors and board members may rely on them when evaluating growth, defensibility, product moat, or operational maturity.

    Once AI language starts influencing those decisions, the claim stops being casual branding. It becomes something closer to a factual representation about capability, safety, governance, or reliability.

    That is why AI washing is becoming a legal category even without a statute labeled “AI washing.” The law already knows how to handle claims that create a misleading net impression.

    “AI” Is Not Just One Claim

    One reason this gets messy fast is that companies often use AI language as if it were a single label.

    It is not. Saying a product uses AI can imply very different things depending on the context. It may suggest the product actually uses machine learning rather than ordinary automation. It may suggest the system is more advanced than a rules engine, improves itself over time, requires less human labor, produces more accurate results, acts autonomously, or has stronger safety and governance controls than competing tools.

    Those are not all the same claim. They create different expectations and different legal exposure.

    A regulator or plaintiff usually does not need to prove that every part of the AI story was false. It is often enough to show that the overall impression was materially misleading for the audience that mattered.

    The Problem Is Broader Than Capability Hype

    The obvious form of AI washing is capability inflation. A company says the product can do things it cannot do.

    The harder cases are broader than that. The claim may not be “our model is magic.” It may be “our system is safe,” “our outputs are objective,” “our workflow is compliant,” “our AI runs with human oversight,” or “our platform is enterprise ready.”

    That is where the risk gets more serious, because those claims are often tied to internal process, governance, testing, escalation, data handling, and product design, not just model performance.

    A company can also create AI-washing risk by hiding the amount of human labor behind the product, downplaying model limitations, overstating bias mitigation, overstating explainability, or suggesting a level of operational control that does not really exist.

    In other words, the legal problem is often not “you said the word AI.” It is “you used AI language to imply a level of performance, safety, or governance that the record cannot support.”

    The FTC Makes The Trend Easier To See

    The FTC's proposed AI accuracy policy statement is not an anti-AI-washing rule by name, but it shows the direction clearly.

    The Commission's point is that a company may create the impression that its AI system is trying to provide the best, most accurate, or most truthful answer for the user's objective. If the system is actually steered toward a different hidden objective, the FTC says that may be deceptive.

    That is a model-design issue, but it is also a claims issue. A company may never use the phrase “objective and neutral” and still create that impression through product design, benchmarking language, sales materials, accuracy messaging, or positioning.

    The same pattern showed up differently in the FTC's Active Listening matter. There, the problem was not just a buzzword. It was the gap between what the product was presented as doing and what the facts supported about the listening function and the related privacy implications.

    Put those together and the pattern becomes clearer. AI-washing risk is not confined to inflated tech language. It can arise whenever the public story about the system outruns the product reality.

    Where The Risk Usually Shows Up

    The public homepage is only one part of the problem.

    Marketing copy is the obvious starting point because words like autonomous, safe, trustworthy, accurate, unbiased, transparent, and enterprise ready can imply a lot more than the company intends. Those words are not off-limits. They just need support.

    The bigger risk often sits in enterprise sales materials, procurement responses, security questionnaires, governance decks, and customer demos. That is where companies make concrete statements about explainability, retention, deletion, human review, model change management, data isolation, safety controls, and compliance readiness. If those statements outrun the actual workflow, the mismatch may surface later in a customer dispute, regulator inquiry, or internal escalation.

    Investor and board communications create another layer. If a company ties AI to measurable gains in safety, efficiency, margins, market position, or defensibility, those statements may later be compared against testing records, incident logs, and internal discussions. Not every optimistic statement creates liability. But specific, repeated, safety-linked claims deserve careful treatment.

    The product experience itself also matters. A system can create strong expectations without saying much at all. A chatbot that speaks with confidence, appears emotionally perceptive, presents itself as a trusted helper, or hides the extent of human involvement may create a stronger impression than any disclaimer in the footer.

    The Internal Record Usually Decides How Bad It Gets

    AI washing tends to look worst once someone asks for the internal record.

    If the company publicly describes a system as safe, accurate, objective, well-governed, or ready for sensitive deployment, the next questions are predictable. What testing supported that statement? What limitations were already known? Were complaints or incidents pointing in the other direction? Did anyone inside the company describe the claim as too aggressive? Was the claim approved because it was supported, or because it sounded good?

    That is the point where puffery arguments start to weaken. The problem stops looking like enthusiastic copy and starts looking like a documentation and governance failure.

    What Companies Should Review Now

    Companies using AI language in public or customer-facing materials should review a few things immediately.

    • Whether the claim is really about the presence of AI, or about performance, safety, autonomy, neutrality, or compliance.
    • Whether current product testing and governance records actually support the claim being made.
    • Whether consumers, enterprise customers, investors, and regulators are hearing different versions of the same product story.
    • Whether the product experience creates stronger expectations than the formal copy.
    • Whether disclaimers change the net impression in a meaningful way, or just try to patch over an aggressive claim after the fact.
    • Whether the rationale behind sensitive AI claims is being preserved in a way the company could defend later.

    The practical question is not “can we argue about this phrase if challenged?” It is “what expectation does this create, and would we be comfortable defending that expectation with the actual record?”

    Bottom Line

    AI washing is becoming a real legal category because AI claims now influence decisions about safety, trust, spending, and risk.

    The law does not need a special AI-washing label to get there. Existing doctrines already give regulators and plaintiffs room to test whether the public AI story matches the product, the workflow, and the record behind it.

    If a company would be uneasy putting its public AI claims next to its testing history, governance records, customer complaints, and known limitations, those claims probably need work.

    Sources

  • AI Litigation Is Increasingly About Governance Records

    AI Litigation Is Increasingly About Governance Records

    For a while, AI legal risk was often framed as a debate about big theories.

    Would copyright claims survive? Would Section 230 matter? Would a new AI statute appear? Would courts treat models as products?

    Those questions still matter. They are no longer the whole story.

    The more immediate litigation and enforcement risk is becoming much more operational. Regulators, state attorneys general, and private plaintiffs increasingly want to know what the company knew, what it tested, what it changed, what it told users, and what records support those answers.

    That is why AI litigation is increasingly about governance records.

    The Short Answer

    • AI legal risk is moving from abstract policy debate into record-based disputes about testing, warnings, internal knowledge, and product governance.
    • Plaintiffs and regulators are using existing consumer-protection, privacy, product-design, and safety theories to ask for concrete documents rather than broad philosophical answers.
    • Companies that cannot produce a coherent record of AI design, review, escalation, and mitigation may look irresponsible even before a court decides the merits.

    The Record Problem Is Showing Up Across Different AI Disputes

    The same pattern is emerging in several different legal lanes.

    Florida's lawsuit against OpenAI is not just about a chatbot existing in the market. The complaint tries to turn product design, youth access, safety controls, warnings, and data practices into evidence-backed state consumer-protection and product-liability questions.

    The reported 42-state OpenAI investigation appears to be asking for information about advertising, engagement, retention, sycophancy, vulnerable users, and treatment of sensitive data. Even at the investigation stage, that is a document-heavy inquiry.

    The FTC's proposed AI accuracy policy statement points in the same direction. If the agency believes a model is being steered away from the user's expected objective, the obvious next question is what internal records show about the product's actual objective, controls, and consumer-facing explanation.

    Companion-chatbot scrutiny also fits the pattern. Once a regulator or plaintiff argues that a system creates foreseeable emotional or behavioral risk, the practical fight becomes whether the company had warnings, testing, age controls, escalation rules, and internal evidence supporting its safety claims.

    These are different legal theories. They are all becoming record fights.

    The New Core Question Is “What Can The Company Prove?”

    That question matters because a lot of AI governance still lives in presentation decks, launch reviews, and broad principles rather than in disciplined operational records.

    A company may say it prioritizes safety, fairness, accuracy, trust, youth protection, or responsible AI use. In litigation, those statements are only the beginning.

    The harder questions look like this:

    • What testing was performed before release?
    • What failure modes were already known internally?
    • What documents show that leadership understood the risk?
    • What warnings were considered and rejected?
    • What product changes were made after incidents or internal escalation?
    • What was done for minors, vulnerable users, or high-risk use cases?
    • What claims were made publicly that went beyond what the internal record supported?

    Those questions do not require a comprehensive AI statute. They fit comfortably inside discovery, civil investigative demands, subpoena responses, and ordinary regulatory investigation.

    The Governing Theory May Be Old. The Evidence Questions Are Newer.

    One reason companies misread this area is that they focus too much on whether the legal theory is novel.

    Often it is not.

    A state AG may use ordinary unfair-practices law. The FTC may use a familiar deception theory. A plaintiff may plead negligence, failure to warn, misrepresentation, or product-design claims. A court may focus on privilege, confidentiality, or sanctions rules that predate generative AI entirely.

    The novelty is frequently in the factual record, not in the legal label.

    The company is being asked to explain a model release, a training pipeline, a ranking system, a safety override, an age-gating decision, a memory feature, a moderation workflow, or a prompt-handling rule in a way that holds up across internal documents, external claims, and product behavior.

    That is harder than reciting a principle.

    The Weakest Record Often Appears In Four Places

    1. Safety Testing

    Many AI companies can say they tested. Fewer can show:

    • what they tested for;
    • which risks were considered material;
    • how red-team findings were escalated;
    • what thresholds blocked release;
    • what mitigations were added before launch; and
    • what remained unresolved at release.

    If a harm later appears that looks close to a known internal concern, the testing record becomes central very quickly.

    2. Marketing And Product Claims

    A lot of AI exposure begins when public claims outrun operational reality.

    That can happen through phrases like:

    • safe
    • trusted
    • accurate
    • objective
    • youth appropriate
    • enterprise ready
    • privacy preserving
    • human supervised

    Those labels can become litigation artifacts. If the internal record shows caveats, unresolved risk, or known inconsistency, a regulator or plaintiff will try to line the two up side by side.

    3. Vulnerable-User Treatment

    Minors, emotionally dependent users, health-related users, older adults, and other vulnerable populations are becoming a major pressure point.

    It is one thing to say the product was not designed for those users. It is another to explain what the company did once it knew those users were present anyway.

    The record questions become concrete:

    • Was usage by minors or vulnerable users anticipated?
    • Were age controls or warnings considered?
    • Were specific escalation or refusal rules added?
    • Were safety incidents tracked separately?
    • Did executives review those incidents?

    4. Model-Change History

    AI systems change. That is normal. It is also legally dangerous when the company cannot explain what changed and why.

    A useful governance record should be able to show:

    • when a material model or policy change was made;
    • why it was made;
    • what known tradeoffs it introduced;
    • whether user-facing claims changed too; and
    • whether the company preserved enough history to explain pre-change versus post-change behavior.

    Without that, later disputes can turn into messy arguments over what version of the system did what.

    AI Governance Records Are Not Just For Regulators

    This is not only an agency problem.

    Governance records matter in:

    • private litigation;
    • state AG investigations;
    • FTC inquiries;
    • insurance disputes;
    • vendor and enterprise customer conflicts;
    • discovery fights over AI-related workflow decisions; and
    • post-incident board or audit review.

    The same internal gap can create problems across all of them.

    A company that cannot explain how it reviewed safety, documented model changes, handled incident escalation, or substantiated its marketing may face very different legal claims built on the same weak operational record.

    What A Better Record Looks Like

    A good AI governance record does not have to be perfect. It does have to be coherent.

    At minimum, companies should be able to locate:

    • release-review materials for major launches and major feature changes;
    • red-team, testing, and evaluation summaries;
    • incident logs and escalation records;
    • change logs for material policy or model updates;
    • records of who approved sensitive decisions;
    • rationale for warnings, disclosures, and refusal behavior;
    • records supporting claims about accuracy, safety, privacy, or guardrails; and
    • documentation showing how minors, vulnerable users, or high-risk contexts were handled.

    This is the difference between a company that can explain its judgment and a company that can only say it cared about responsible AI in general.

    What Companies Should Do Now

    Companies with public-facing or high-impact AI systems should review:

    • whether product, legal, policy, trust and safety, and communications teams are creating one usable record or five disconnected ones;
    • whether launch reviews are preserved in a way that can be understood later;
    • whether known-risk discussions are logged or only discussed in chat threads and meetings;
    • whether incident review produces a retrievable record of action and follow-up;
    • whether marketing language is checked against the internal testing record;
    • whether vulnerable-user issues are tracked explicitly instead of being buried inside generic safety notes; and
    • whether the company can reconstruct what changed in the system over time.

    The point is not to generate paper for its own sake.

    The point is that once litigation or investigation begins, the record exists whether the company designed it or not. If the formal record is weak, the real record will be reconstructed from fragments.

    That is usually worse.

    Bottom Line

    AI litigation is increasingly about governance records because the legal system is moving from theory to proof.

    The governing claims may sound familiar: deception, unfairness, negligence, design defect, failure to warn, privacy failures, or safety misrepresentation.

    What changes the exposure is often much more practical.

    Can the company show what it knew, what it tested, what it changed, what it told users, and why those decisions were defensible at the time?

    That is the record question. It is becoming one of the most important AI law questions on the board.

    Sources

  • German Court Says Google AI Overviews Can Become Platform Speech

    German Court Says Google AI Overviews Can Become Platform Speech

    A German court has delivered one of the clearest early liability signals yet for AI-generated search summaries.

    According to the Munich I Regional Court’s June 12, 2026 press release, the court granted a preliminary injunction application by two publishers over statements shown in Google’s "AI Overview" format.

    The important part is the court’s reasoning.

    The 26th Civil Chamber said the challenged AI Overview was not merely a display or link list of search results. It was content attributable to the search engine operator because the results were presented in the operator’s own summarized and evaluated words.

    That is a meaningful platform-liability signal even though the ruling is only a preliminary injunction and is not yet final.

    The Short Answer

    • The Munich I Regional Court said the challenged Google AI Overview could be treated as content attributable to Google, not just a neutral display of third-party search results.
    • The ruling came in a preliminary injunction proceeding, not a final merits judgment, and the court’s own press release says the decision is not final.
    • Reuters separately reported that Google plans to appeal, but as of Clearon’s last source check there was no official appellate docket or published appellate decision identified.

    What The Court Said

    The court’s press release describes the case as involving two publishers who sought an injunction against statements about them generated in the search engine’s "AI Overview" feature.

    The publishers argued that the AI-generated overview text wrongly associated them with fraud schemes and unserious business practices, which they said violated their corporate personality rights.

    The search-engine operator argued, among other things, that it should not be liable because it was not itself responsible for the data processing and did not adopt the third-party information shown in the overview as its own.

    The court rejected that framing.

    Its key reasoning was direct: the "AI Overview" display was not merely a presentation or linking of search results. It was its own content attributable to the search-engine operator because the search results were summarized and evaluated in the operator’s own words.

    The press release says the wording of the AI Overview showed an independent substantive evaluation of the search results. On the court’s account, that created statements going beyond the later-linked search results themselves, and those statements could be attributed to the operator.

    That is the part other publishers, platforms, and product teams should pay attention to.

    Why Attribution Matters More Than The Injunction Alone

    The legal importance here is attribution.

    Search engines and other intermediaries have long argued, often with some success, that they merely index, rank, display, or link to third-party material. That position can matter a lot in defamation, press-law, and intermediary-liability disputes.

    The Munich court’s description of the AI Overview product cuts against that safe framing.

    If a court sees the output as the platform’s own summarized and evaluated statement, the liability analysis changes. The platform is no longer only pointing a user toward third-party material. It may be treated as making a new statement itself.

    That matters well beyond classic search.

    The same issue can surface anywhere a system takes source material, rewrites it, condenses it, ranks it, or presents it as a single synthetic answer:

    • search summaries,
    • answer engines,
    • shopping and review summaries,
    • publisher-facing AI snippets,
    • enterprise knowledge assistants, and
    • other AI systems that translate multiple sources into one user-facing statement.

    Once the system moves from retrieval into synthesis, the platform’s "we only linked to sources" argument may get weaker.

    This Is Still A Preliminary Ruling

    The procedural posture matters.

    The Munich court press release describes the matter as an application for a preliminary injunction. It does not publish a final appellate holding or a full merits judgment. The court also says expressly that the decision is not final.

    That means companies should not overread the case.

    This is not a final Europe-wide rule that every AI summary automatically becomes platform speech. It is an official court summary of one injunction-stage ruling on one challenged overview display and one set of alleged false implications about specific publishers.

    Still, preliminary rulings matter because they show how at least one court is analyzing the product.

    For legal and product teams, this is exactly the kind of opinion worth watching early. It gives a preview of what judges may find persuasive before a full appellate record ever appears.

    The Appeal Posture

    Reuters reported on the same date that Google said it would appeal the German ruling.

    That reported appeal intent matters, but it should be described carefully.

    The official source Clearon identified is the Munich I Regional Court’s press release confirming the underlying injunction and its reasoning. Reuters is the source for Google’s reported plan to appeal. As of the last official-source check reflected in Clearon’s tracker, no official appellate docket entry, appellate press release, or published appeal decision had been identified.

    So the clean framing is:

    • official source for the injunction and reasoning: yes;
    • official source for a filed appellate result: not yet identified;
    • reported intent to appeal: yes.

    That distinction matters because AI-law reporting is already crowded with headlines that flatten allegations, preliminary rulings, and final holdings into one category.

    What Platforms Should Take From This

    The operational lesson is not "do not build AI summaries."

    It is that platforms should stop assuming synthesis is legally equivalent to linking.

    Teams deploying AI-generated summary products should review:

    • whether the product merely retrieves sources or also rewrites and evaluates them;
    • whether the interface presents the answer as a platform-generated conclusion;
    • whether users are likely to treat the summary as a standalone factual statement;
    • how disputed or reputation-sensitive topics are handled;
    • what guardrails exist for summaries about people, publishers, businesses, or alleged misconduct;
    • what source-review and suppression pathways exist when a summary appears false or distorted; and
    • what internal records show about testing, escalation, and correction workflows.

    This also connects to the broader pattern Clearon has been tracking in AI litigation and enforcement.

    Whether the issue is a state AG probe, a chatbot-safety complaint, or an AI-generated search summary, the pressure point is often the same: did the company merely host a tool, or did it create and present its own legally consequential statement?

    Bottom Line

    The Munich I Regional Court’s press release gives the market a clear early warning.

    At least one German court is willing to treat a challenged AI Overview as content attributable to the search-engine operator because it was presented in the operator’s own summarized and evaluated words.

    That is not a final appellate rule, and the decision is not yet final. But it is a concrete sign that AI-generated summaries can shift a platform from distributor arguments toward speaker responsibility.

    For companies building summary products, that is the part worth taking seriously now.

    Sources