Category: Litigation & Enforcement

Court orders, litigation developments, copyright disputes, privilege decisions, enforcement, and sanctions involving AI.

  • AI Sanctions Are Moving Beyond Fake Cases

    AI Sanctions Are Moving Beyond Fake Cases

    The first wave of AI sanctions cases had an easy headline: fake cases.

    That problem has not gone away. But the next wave is broader and harder to catch. Courts are now calling out false quotations, inaccurate descriptions of real cases, unsupported legal propositions, fabricated record references, and correction filings that repeat the same verification failure they were supposed to fix.

    That shift matters because a fake case name is often easy to spot. A real case with a fake quotation is more dangerous. It can survive a quick citation check, especially if the lawyer confirms that the case exists but never reads what it actually says.

    Recent decisions from the Sixth Circuit and Michigan Court of Appeals, plus a new Oregon Court of Appeals notice, point in the same direction: legal teams need source-level verification, not just citation-level verification.

    Farris: Real Cases, False Quotations

    In United States v. Farris, the Sixth Circuit did not decide the merits of the criminal appeal. It stopped to address the conduct of appointed appellate counsel.

    The court said counsel admitted using Westlaw CoCounsel to draft the briefs and then filing them without properly verifying the legal authorities. The problem was not simply that the briefs cited nonexistent law. The briefs cited genuine authorities but attributed quotations and propositions to them that did not appear in the sources.

    One example involved the Sentencing Guidelines commentary. Other examples involved Sixth Circuit cases that were described as reversing role enhancements when they did not support the propositions asserted. The court said the briefs misrepresented the holdings of United States v. Washington and United States v. Anthony.

    The Sixth Circuit drew a line that every litigation team should build into its review process: citing a real case does not make an AI-assisted brief safe if the quotation is fabricated or the holding is misdescribed.

    The consequences were serious. The court ordered that counsel not be compensated under the Criminal Justice Act for the appeal, forwarded the opinion for possible disciplinary proceedings, served the opinion on district court and Kentucky Bar authorities, and separately removed counsel from further representation. Replacement counsel would be appointed and the briefing schedule reset.

    The court also made an important vendor-neutral point. Lawyers cannot assume that a legal AI product is reliable merely because it comes from an established legal technology provider.

    Barber: The Correction Filing Was Also Wrong

    The Michigan Court of Appeals reached a similar point in Barber v. Morawa, a published medical-malpractice appeal.

    The merits issue was straightforward: the court affirmed denial of a motion for a new trial or evidentiary hearing. The sanctions issue was not. Plaintiff's counsel had cited nonexistent cases in the trial court, relied on criminal authorities in a civil case, and then filed an appellate brief that cited another nonexistent case and used real authorities for propositions they did not support.

    After the defendant identified the defects, counsel eventually filed a "Notice of Correction." But that notice, which counsel acknowledged was also prepared with AI assistance, repeated the problem by attributing quotations and legal propositions to cases that did not contain them.

    The Michigan court held that counsel's repeated submission of fabricated and unsupported authority violated MCR 7.216(C)(1) and MCR 1.109(E)(5). It remanded for a determination of actual damages and reasonable attorney fees incurred because of the appeal, payable personally by counsel, and directed the clerk to forward the opinion to the Attorney Grievance Commission.

    That is the deeper lesson of Barber: a correction cannot be just another AI-assisted filing. Once a court or opposing party flags possible fabricated authority, the next filing should be treated as a high-risk verification event.

    Oregon Turns The Warning Into A Court Notice

    The Oregon Court of Appeals has now posted a notice specifically warning about fabricated authority produced by AI.

    The notice says the court has received an increasing number of filings containing fabricated authorities, including citations that do not exist, quotations that do not appear in the cited authority, propositions of law not reasonably related to the citation, and factual support with no basis in the record.

    The listed consequences include striking the filing, monetary sanctions payable to the court, attorney-fee awards payable to the opposing party, and dismissal of the appeal.

    The notice also gives a practical verification rule. Anyone using generative AI to prepare court-filing content must verify that all cited cases exist, that all quotations actually appear in the cited cases, and that all paraphrased propositions of law are objectively reasonable in light of what the case actually says.

    That is a useful checklist because it is not limited to fake case names. It reaches the subtler errors that are becoming common in appellate sanctions orders.

    The Pattern Is Broader Than One Tool Or One Court

    These developments fit the recent sanctions record.

    In Lnu v. Blanche, the Ninth Circuit sanctioned lawyers for briefs containing nonexistent cases, misattributed quotations, and gross misrepresentations of real authority. The court emphasized that the discipline became more serious because of the lawyers' responses after the errors came to light.

    In Withers v. City of Aberdeen, a Mississippi federal court sanctioned and removed all counsel after filings from both sides contained AI-generated fabricated authority. The order is a sharp warning for local counsel and sponsoring counsel: signing and sponsoring are not administrative formalities.

    In State v. Coleman, an Ohio appellate court sanctioned counsel after a filing contained ChatGPT-generated fabricated transcript quotations prepared by a paralegal. The AI problem there was not fake caselaw. It was a fake record.

    Together, the cases show the sanctions framework maturing. Courts are no longer asking only whether a case exists. They are asking whether the filing honestly represents law and fact.

    What Litigation Teams Should Change

    The review process should be built around propositions, not just citations.

    Before filing AI-assisted work, litigation teams should verify:

    • every cited case, statute, rule, and record reference exists;
    • every direct quotation appears in the cited source;
    • every parenthetical accurately describes the source;
    • every paraphrased proposition is fairly supported by the authority;
    • every record quotation or factual assertion matches the underlying record;
    • the lawyer signing the filing has personally satisfied the required level of review; and
    • any correction filing receives independent source review before submission.

    It is not enough to ask whether the tool hallucinated a case. A real case can be turned into a false authority if the quotation, holding, or procedural posture is wrong.

    Bottom Line

    The AI sanctions story is moving from fake cases to false authority.

    That is a harder problem and a more practical one. Lawyers have always had to verify the law and the record before filing. AI makes that duty more visible, not less binding.

    The practical rule is simple: if a filing relies on a source, someone must read the source.
    Sources

  • FTC’s Active Listening Settlement Turns AI-Washing Into a Privacy Problem

    FTC’s Active Listening Settlement Turns AI-Washing Into a Privacy Problem

    The Federal Trade Commission's proposed "Active Listening" settlements connect three risks that often travel together: AI-washing, adtech targeting claims, and weak consent theories.

    The FTC says Cox Media Group and two marketing firms falsely claimed to offer an AI-powered service that could target localized ads based on conversations captured from consumers' smart devices. According to the FTC, the service did not use voice data at all. It allegedly resold data-broker email lists at a markup and did not accurately place ads in customers' desired locations.

    That would be a straightforward deception case on its own. But the FTC went further. It also said the companies misled customers by claiming consumers had opted into the alleged listening service. And the agency added a point that should get the attention of every company making privacy-sensitive AI claims: if the service had actually worked as advertised, collecting and using consumers' voice data from inside their homes without adequate consent would itself violate Section 5 of the FTC Act.

    In other words, the problem was not only that the AI claim was false. The claimed AI capability was itself a privacy-risk representation.

    What The FTC Alleged

    The FTC announced proposed settlements with CMG Media Corporation, doing business as Cox Media Group, plus MindSift LLC and 1010 Digital Works LLC. The alleged customers were businesses buying advertising and marketing services, not the consumers whose supposed smart-device conversations were described in the pitch.

    The companies allegedly marketed an "Active Listening" advertising service that could listen in on consumer conversations overheard by smart devices, detect relevant conversations in real time, and use that information to target ads to consumers in specific geographic areas.

    The FTC says that was not true. According to the agency, the service was not based on voice data, did not listen to consumer conversations, and did not accurately place ads in the customers' desired locations. Instead, the service allegedly consisted of reselling email lists obtained from data brokers.

    The agency also says the companies told customers that consumers had opted into the service. But the FTC says the companies did not seek or obtain consumer consent. The agency specifically rejected the idea that consumers "opted in" by clicking through mandatory app terms of service.

    That consent point is the heart of the case for AI governance teams. Many AI products rely on layered data flows, third-party data, contractual assurances, or generalized platform terms. The FTC's framing says those shortcuts may not support privacy-sensitive claims, especially where the asserted capability involves intimate in-home voice data.

    The Settlement Terms

    The proposed orders require a total of $930,000 in payments: $880,000 from CMG and $25,000 each from MindSift and 1010 Digital Works. The money is intended to provide redress to CMG customers affected by the alleged practices.

    The proposed orders would also prohibit each defendant from making misrepresentations about:

    • the qualities or features of advertising or marketing services;
    • the collection and use of voice data, including whether consumers consented to collection, use, or disclosure; and
    • the geographic targeting capabilities of advertising or marketing services.

    The FTC issued the proposed administrative complaints and accepted the consent agreements by a 2-0 vote. The agreements remain subject to a 30-day public-comment period after publication in the Federal Register. If the orders become final, each violation may lead to a civil penalty of up to $53,088.

    As usual, the settlements resolve allegations. They are not admissions of liability or litigated findings.

    Why The Money Is Procedurally Important

    The $930,000 payment should not be read as the FTC simply using Section 13(b) to disgorge money from the companies.

    That route is no longer available after the Supreme Court's 2021 decision in AMG Capital Management, LLC v. FTC. In AMG, the Court held that Section 13(b) of the FTC Act authorizes the FTC to seek prospective injunctive relief, but does not authorize courts to award equitable monetary relief such as restitution or disgorgement for past conduct.

    That matters here because the FTC is resolving the Active Listening allegations through proposed administrative consent orders, not by relying on Section 13(b) alone to obtain monetary relief in federal court.

    If the parties agree, the FTC can include monetary terms in a settlement package. If they do not agree and the FTC wants monetary relief for an ordinary unfair or deceptive act or practice, the post-AMG route is more cumbersome. The FTC generally must proceed administratively under Section 5, obtain a final cease-and-desist order, and then seek consumer redress under Section 19 if the statutory standard is met, including that a reasonable person would have known under the circumstances that the conduct was dishonest or fraudulent.

    Civil penalties are different again. A first-time Section 5 deception allegation does not automatically produce civil penalties simply because the FTC believes the conduct was deceptive. Penalties typically require an independent penalty hook, such as violation of a final FTC order, violation of certain rules, or another statutory basis. That is why the FTC's release says that if these proposed orders become final, future violations of the orders may carry civil penalties of up to $53,088 per violation.

    So the practical sequence is:

    • settlement now, if the parties agree to money and conduct restrictions;
    • prospective injunctive relief under Section 13(b), but not standalone disgorgement or restitution after AMG;
    • administrative Section 5 proceedings followed by Section 19 redress for qualifying deceptive or unfair practices if there is no settlement; and
    • civil penalties later if a final order, rule, or other penalty-triggering authority is violated.

    What About AT&T?

    There are two AT&T references that can get confused.

    The Supreme Court's FCC v. AT&T Inc. decision does not do much work here. That case addressed whether corporations have "personal privacy" interests under FOIA Exemption 7(C). It is not an FTC Act remedies case and does not change the AMG limit on Section 13(b), the Section 5 administrative route, or the Section 19 redress path.

    The more relevant AT&T case for FTC authority is FTC v. AT&T Mobility LLC, the Ninth Circuit's 2018 en banc decision about the FTC Act's common-carrier exemption. The Ninth Circuit held that the exemption is activity-based, not status-based: a company is outside FTC Section 5 authority only to the extent it is engaged in common-carrier activity.

    That issue is not central to the Active Listening settlements because CMG, MindSift, and 1010 Digital Works are being treated as marketing and advertising-service defendants, not common carriers. But the case would matter if a telecom, broadband, or smart-device company raised a common-carrier defense to an FTC challenge involving AI-powered targeting, voice data, or marketing claims. In that setting, the question would be whether the challenged conduct is common-carrier activity or a non-common-carrier advertising, data, or marketing practice.

    Why This Is More Than an AI-Washing Case

    AI-washing cases usually focus on whether a product actually uses AI, whether the claimed performance is substantiated, or whether the term "AI-powered" is being used as a sales shortcut.

    This case adds a different lesson: the advertised AI function may create its own legal problem.

    If a company claims it can listen to private conversations through smart devices, the claim is not just a product-capability statement. It is a statement about data collection, surveillance, consent, security, and consumer expectations inside the home.

    The FTC's line is unusually direct. It says mandatory app terms do not equal opt-in consent for an invasive service or for the use of consumers' voice data from inside their homes.

    That matters even for companies that are not doing audio targeting. The same logic can apply to AI claims involving:

    • biometric inference;
    • location-based targeting;
    • health or mental-health signals;
    • children's or teens' behavior;
    • financial vulnerability;
    • workplace monitoring;
    • emotion detection;
    • private-message analysis; or
    • household-device data.

    When the marketed AI feature depends on sensitive data, the claim must be true, substantiated, and backed by a consent theory that fits the sensitivity of the data.

    The "Means and Instrumentalities" Piece

    The FTC also charged MindSift and 1010 Digital Works with providing CMG the "means and instrumentalities" to deceive customers through marketing materials, sales pitches, and responses to customer questions.

    That is an important vendor and partner lesson. A company does not necessarily avoid risk because another company owns the customer relationship. If it supplies misleading AI claims, sales materials, or talking points that others use with customers, it can become part of the deception theory.

    Adtech and AI vendors should treat this as a documentation and channel-control problem. Marketing claims should be reviewed not only on the vendor's website, but also in partner decks, reseller scripts, pitch emails, FAQs, demos, and objection-handling materials.

    What Companies Should Do Now

    The FTC's case points to several practical controls.

    First, inventory AI capability claims. Identify every place the company says an advertising, analytics, targeting, personalization, monitoring, or customer-intelligence product is "AI-powered," "real time," "listening," "detecting," "predicting," or "consent based."

    Second, match each claim to evidence. The proof should show not only that the technology can do what the company says, but that the deployed product actually does it in the advertised context.

    Third, separate data-source claims from model claims. Saying a system uses AI does not prove what data it uses. Saying a system uses a data source does not prove that consumers consented to that use.

    Fourth, review consent language with sensitivity in mind. Broad mandatory terms may not support claims about invasive data collection. If the advertised feature involves voice, biometrics, location, children, health, finances, or household data, the consent record needs to be much stronger.

    Fifth, audit partner materials. Vendors and agencies should not assume that downstream sales claims are someone else's problem. Resellers should not repeat vendor claims without understanding what the product actually does and what evidence supports the claim.

    Finally, avoid "it would be worse if true" marketing. A privacy-invasive capability can create legal risk even when it is imaginary. If a company would need strong consent, privacy notices, security controls, and compliance review to lawfully operate the feature, it should not casually advertise that capability as a sales hook.

    Bottom Line

    The FTC's Active Listening settlements show how quickly AI marketing can become a privacy and consumer-protection case.

    The alleged service did not listen to consumers' conversations. But the FTC still treated the claim as serious because customers were told the service used AI to target ads from smart-device conversations and that consumers had opted in.

    That is the lesson for AI products generally: do not sell a capability the product does not have, and do not claim sensitive-data consent that the company cannot prove. When the AI story depends on surveillance-like data, the marketing review is also a privacy review.

    Sources

    Sources

  • AI Court Rules Are Becoming Verification Rules

    AI Court Rules Are Becoming Verification Rules

    The next phase of legal AI regulation looks less like a blanket ban and more like a verification record.

    Florida now requires filers to stand behind the existence and accuracy of cited legal authorities. New York now allows AI-assisted court papers without a statewide disclosure requirement, but requires independent verification. The Ninth Circuit just sanctioned lawyers for AI hallucinations and lack of candor. A Mississippi federal judge just removed all four lawyers from a case after both sides filed AI-tainted briefs.

    Different courts. Same message: the tool is not the issue. The filing is.

    The New Rule: Verify First

    Florida's amended Rule 2.515(d)(2), effective June 15, 2026, says that by filing a document, the signer represents that "the legal authorities identified exist and are accurately cited." If that representation is false, sanctions can include reprimand, contempt, striking the filing, dismissal, costs, attorneys' fees, or other relief.

    That is deliberately broader than AI. A lawyer cannot escape the rule by saying a fake case came from a chatbot, a legal research product, an associate, local counsel, a vendor, or a recycled brief.

    New York's Part 161, effective June 1, takes a different route but lands in the same place. It permits AI use in court submissions and does not impose a statewide disclosure mandate. But users must understand the technology's limits and independently ensure that filings do not contain fabricated or fictitious cases, statutes, or other material.

    So the emerging split is not "AI allowed" versus "AI banned." It is disclosure versus no disclosure, with verification underneath both.

    The Sanctions Cases Are Getting Less Patient

    In Lnu v. Blanche, the Ninth Circuit sanctioned two lawyers after filings contained nonexistent cases, misattributed quotations, and serious misreadings of real cases. The court stressed that it was not punishing AI use by itself. It was punishing false filings and the lawyers' later lack of candor.

    That distinction matters. A bad citation is a serious problem. A bad explanation can become the larger one.

    The Mississippi sanctions order in Withers v. City of Aberdeen is even more vivid. The case started as a fee dispute brought by Louisiana lawyer Tom Withers III against Aberdeen, Mississippi. After transfer to the Northern District of Mississippi, the court found hallucinated authorities in filings from both sides.

    The plaintiff side included Louisiana pro hac vice counsel Kathleen M. Wilson and Mississippi local counsel Shauncey Hunter Ridgeway. The defense side included Texas pro hac vice counsel Kathryn Y. Williams and Mississippi local counsel Mark C. McClinton. The court removed all four lawyers from the case, revoked both pro hac vice admissions, barred the two out-of-state lawyers from appearing in the district for two years, imposed monetary sanctions, and referred the order to disciplinary authorities.

    The local-counsel lesson is hard to miss: signing is not clerical. Sponsoring is not ceremonial. If your name is on the filing, the verification problem is yours too.

    California May Be Next

    California is also moving from guidance toward rules. The State Bar has opened public comment on proposed amendments to the Rules of Professional Conduct related to AI, after the California Supreme Court asked it to consider incorporating generative-AI guidance and addressing agentic AI tools.

    That is not a court-filing rule like Florida's or New York's. But it shows the same maturation curve. Soft guidance is starting to harden.

    What To Do Before The Next Filing

    Litigation teams should assume courts will ask a simple question: who checked this?

    • Check the courtwide rule, local rule, judge's standing order, and part rules before filing.
    • Identify whether AI touched research, drafting, editing, factual summaries, record citations, or proposed orders.
    • Verify every cited authority in an authoritative source.
    • Read the authority, not just the citation.
    • Confirm quotations, parentheticals, holdings, procedural posture, and subsequent history.
    • Trace facts and record cites back to the record.
    • Make signing, local, and sponsoring counsel confirm the verification process.
    • If an error is found, correct it quickly and candidly.

    The hardest AI errors are not always fake case names. Sometimes they are real cases used for propositions they do not support. A citation check is not enough; the proposition has to survive too.

    Bottom Line

    Courts are not focused on whether AI helped with the first draft. They want to know whether a lawyer verified the final filing.

    The practical rule is now simple: use the tool if the forum, client, confidentiality obligations, and governing orders allow it. But before anything is filed, someone qualified must verify the authorities, quotations, facts, and record references. And someone with a signature block must be ready to say so.

    For a broader inventory of court rules, sanctions orders, privilege decisions, protective-order restrictions, and tribunal guidance, see Clearon's AI Litigation Practice Tracker.

    Sources

    Sources

  • AI-Assisted Legal Filing Verification Checklist

    AI-Assisted Legal Filing Verification Checklist

    Generative AI can accelerate legal work, but it does not change who is responsible for a court filing. Use this checklist before filing any paper that may contain AI-assisted research, drafting, revision, or analysis.

    It is a practical starting point, not a substitute for the requirements applicable to a particular matter.

    Quick Rule

    Do not file an AI-assisted document until a qualified human has independently verified every legal authority, quotation, factual assertion, record citation, and representation about the proceeding against an authoritative source.

    If any item cannot be checked, stop and resolve it before filing.

    1. Confirm Permitted Use

    • [ ] Identify the AI tools used and the portions of the filing they may have affected.
    • [ ] Confirm the use complies with client instructions, protective orders, confidentiality duties, firm policy, and applicable law.
    • [ ] Check local rules, standing orders, judge-specific practices, and filing instructions for AI restrictions or disclosure requirements.
    • [ ] Confirm no protected information was entered into an unapproved system.

    2. Verify Authorities and Quotations

    • [ ] Open and read every cited authority in an authoritative source.
    • [ ] Confirm each citation identifies the correct authority and current version.
    • [ ] Confirm that each authority supports the precise proposition for which it is cited.
    • [ ] Check precedential status, subsequent history, negative treatment, and applicable citation limits.
    • [ ] Compare every quotation and pinpoint citation against the original source and surrounding context.
    • [ ] Confirm parentheticals, paraphrases, and descriptions accurately characterize the source.

    3. Verify Facts and the Record

    • [ ] Trace every material factual assertion to the record or another permissible source.
    • [ ] Open and verify every record citation, exhibit reference, transcript page, docket entry, and date.
    • [ ] Check names, entities, amounts, calculations, timelines, tables, and summaries.
    • [ ] Distinguish allegations, evidence, findings, holdings, inferences, and argument.

    4. Review and Approve the Final Filing

    • [ ] Have a qualified human independently review the final version.
    • [ ] Check the requested relief, legal standard, jurisdiction, deadlines, service representations, and procedural history.
    • [ ] Check for placeholders, invented citations, inconsistent names, unsupported cross-references, and omitted controlling authority.
    • [ ] Verify appendices, exhibits, certificates, signature blocks, and proposed orders.
    • [ ] Complete any required AI-use disclosures or certifications.
    • [ ] Obtain informed approval from the signing lawyer and responsible supervising, local, or sponsoring counsel.

    Ready to File

    • [ ] Every authority, quotation, fact, and record citation has been independently verified.
    • [ ] The final version has not changed since verification.
    • [ ] Applicable AI rules, client restrictions, and disclosure duties have been satisfied.
    • [ ] The signing lawyer can accurately explain how the filing was prepared and checked.
    • [ ] The team preserved a concise record of who reviewed what and when.

    If an Error Is Discovered After Filing

    • [ ] Stop using the affected material and notify responsible lawyers immediately.
    • [ ] Independently determine the error's full scope and preserve relevant records.
    • [ ] Assess duties to the client, court, opposing counsel, insurer, firm, and disciplinary authorities.
    • [ ] Correct material errors promptly and candidly using the required procedure.
    • [ ] Review other filings or matters that may have used the same workflow.

    Candor after discovery can materially affect the court's response. Recent sanctions orders show that concealment, blame shifting, and repeated inaccuracies can be more damaging than the original mistake.

    Bottom Line

    AI assistance does not reduce the duty of inquiry attached to a court filing. Independent verification, meaningful supervision, signer approval, and prompt candor are still the core requirements.

    For examples of how courts are applying those principles, see Oregon Supreme Court's First AI Hallucination Sanctions Show What Courts Punish Most and Clearon's AI Litigation Practice Tracker.

    Sources

    Sources

  • Oregon Supreme Court’s First AI Hallucination Sanctions Show What Courts Punish Most

    Oregon Supreme Court’s First AI Hallucination Sanctions Show What Courts Punish Most

    The Oregon Supreme Court has issued its first sanctions orders involving court filings attributed to generative artificial intelligence. The significance is not a new AI-specific rule. It is that the court applied familiar duties of accuracy, reasonable inquiry, supervision, and candor to filings containing AI-generated errors.

    They also show that the response after an error is discovered can matter almost as much as the original filing.

    In one case, a self-represented litigant accepted responsibility, fully responded to the court, and received a $500 sanction with permission to submit a corrected filing. In the other, self-represented litigants acknowledged fabricated authorities but submitted more nonexistent cases less than 12 hours after the court's show-cause order. The court struck their filings and dismissed the proceeding.

    The lesson extends well beyond Oregon and beyond self-represented litigants. Courts across the country have imposed monetary sanctions, fee awards, dismissal, disqualification, practice suspensions, bar referrals, mandatory disclosures, and other remedies for filings containing fabricated or materially inaccurate authorities.

    Key Takeaways

    • *The Oregon Supreme Court sanctioned self-represented litigants, not lawyers.* The orders make clear that the obligation not to inject false authority into a proceeding applies to everyone who files.
    • *Courts are punishing the filing, not the mere use of AI.* The recurring issue is whether the signer verified that authorities exist, quotations are accurate, and cases support the propositions asserted.
    • *Candor changes the sanction analysis.* Prompt disclosure, correction, and acceptance of responsibility can mitigate sanctions. Repetition, concealment, blame shifting, and misleading explanations can sharply increase them.
    • *The signature and supervision duties are nondelegable.* Lawyers cannot avoid responsibility by pointing to an associate, contract lawyer, local counsel, vendor, internal AI tool, or firm policy.
    • *Financial penalties are only part of the risk.* Dismissal, disqualification, suspension, bar referral, and mandatory notice to clients and other courts can be more consequential than a fine.

    Oregon's Two New Orders

    The Oregon Supreme Court issued both orders on June 4, 2026, and announced them publicly the next day.

    Aldridge v. Tussing: Repeating the Error Led to Dismissal

    In Aldridge v. Tussing, the relators filed a petition for a writ of mandamus supported by nonexistent cases and fabricated quotations. The court ordered them to verify every citation under penalty of perjury, explain the errors, and show cause why sanctions should not be imposed.

    The relators acknowledged that fabricated authorities had been included and attributed the errors to a service called LegalAI. But less than 12 hours after receiving the show-cause order, they submitted another declaration containing at least four nonexistent cases.

    The court struck the petition and the show-cause response and dismissed the proceeding. Its explanation was direct: injecting false precedent undermines the integrity of a proceeding, and repeating the conduct in response to a show-cause order warrants a meaningful sanction.

    Witkin v. McGreevy: Acceptance of Responsibility Mitigated the Result

    In Witkin v. McGreevy, a self-represented respondent filed a response containing fictitious authorities and inaccurate legal arguments generated with AI. After receiving a show-cause order, the respondent addressed each fabricated authority, explained the AI use, and accepted responsibility.

    The court still struck the filing and imposed a stipulated $500 sanction. But it allowed the respondent to file a corrected response, provided that any revised filing certified that every cited, quoted, or paraphrased source of law had been verified to exist.

    The contrast is the point. Both filings contained false authority. The litigant who responded candidly and corrected course received a limited financial sanction and another opportunity to file. The litigants who repeated the misconduct after a direct warning lost the proceeding.

    Oregon Already Had a Six-Figure Warning for Lawyers

    The state-court orders arrived only months after a separate federal case from Oregon demonstrated how large the financial exposure can become.

    In Couvrette v. Wisnovsky, the U.S. District Court for the District of Oregon addressed summary-judgment briefing containing nonexistent cases and fabricated quotations. The court struck the briefing, dismissed the plaintiffs' claims with prejudice, imposed monetary sanctions, and awarded the opposing parties $94,704.38 in fees and costs directly resulting from the briefing.

    The March 2026 fee order allocated the award between lead counsel and local counsel. The local lawyer was ordered to pay 15% after the court found that he had failed to meaningfully participate despite serving as required local counsel for a lawyer admitted pro hac vice. The lead lawyer was ordered to pay the remaining 85%. The court also required local counsel to attach the sanctions order to future motions in which he sought to sponsor pro hac vice counsel in the district.

    Together with the court's earlier monetary sanctions, the financial consequences exceeded $110,000. More important, the case shows that local counsel and supervising lawyers cannot treat their role as providing a name, bar number, or signature while leaving the substance unchecked.

    The Sanctions Menu Is Expanding

    The early headline case was Mata v. Avianca. In 2023, the Southern District of New York imposed a $5,000 penalty after lawyers submitted fabricated cases and fake opinions generated by ChatGPT and continued to defend the material after its authenticity was questioned. The court also required notice to the client and to judges falsely identified as authors of the fabricated opinions.

    Since then, courts have used a much broader range of remedies:

    • *Sanctions for every signer:* In Wadsworth v. Walmart, the District of Wyoming imposed $5,000 in combined sanctions and revoked one lawyer's pro hac vice admission after a filing cited eight nonexistent cases. The court treated the duty to ensure a filing is supported by existing law as nondelegable.
    • *A $10,000 appellate sanction:* In Noland v. Land of the Free, L.P., the California Court of Appeal imposed $10,000 in sanctions after an appellate brief contained fabricated quotations and other inaccurate authority. The published opinion warned that lawyers must personally read and verify the authorities they cite.
    • *Disqualification and bar referrals instead of a fine:* In Johnson v. Dunn, the Northern District of Alabama publicly reprimanded and disqualified three lawyers, required broad distribution of the sanctions order, and referred the matter to licensing authorities. The court concluded that a fine and public embarrassment were insufficient deterrents.
    • *Suspension from appellate practice:* In Lnu v. Blanche, the Ninth Circuit imposed $2,500 sanctions on each of two lawyers, suspended both from practice before the circuit for six months, required notice to clients, opposing counsel, judges, and the lawyers' firm, and imposed a two-year AI-use disclosure and verification requirement. The court emphasized that the more serious discipline resulted from repeated failures of candor after the errors came to light.
    • *Both sides sanctioned:* In Withers v. City of Aberdeen, the Northern District of Mississippi sanctioned and removed all four lawyers after filings from both sides contained hallucinated authorities. The two out-of-state lawyers were also barred from appearing in the district for two years.

    These cases do not establish a uniform sanctions schedule. They show that courts are calibrating remedies to the conduct, the harm, the lawyer's role, prior warnings, remediation, and candor.

    What Courts Appear to Punish Most

    The orders point to several aggravating factors.

    Filing Without Reading the Authorities

    Checking whether a case name exists is not enough. Courts expect lawyers to read the authority and confirm that quotations are accurate, procedural posture is correctly described, and the case actually supports the proposition asserted.

    The Ninth Circuit drew a useful distinction between fabricated authorities and subtler inaccuracies. A fake case may be easy to detect. A real case mischaracterized by an AI tool may be more dangerous because it can survive a superficial citation check.

    Treating Signatures as Administrative

    Courts repeatedly reject the idea that a lawyer can lend a signature without assuming responsibility for the filing. That principle reaches supervising lawyers, local counsel, partners, and lawyers whose names appear in signature blocks even when they did not personally use AI.

    Repeating or Concealing the Problem

    An inaccurate filing creates a serious problem. Misleading the court about how it happened, replacing fake citations without disclosing the original problem, or submitting additional fabrications after a warning creates a larger one.

    The Oregon Supreme Court's two orders make the distinction unusually clear. So does the Ninth Circuit's order in Lnu, where the court said lesser sanctions might have been warranted if the lawyers had promptly disclosed the AI use and accepted responsibility.

    Relying on a Policy Without Enforcing It

    Having a written AI policy is not a defense when actual workflows allow unverified material to reach the court. Policies must identify who checks citations, quotations, propositions, facts, and record references before filing. They also need a clear escalation process when an error is discovered.

    What Litigation Teams Should Do Now

    For a practical pre-filing workflow, use Clearon's AI-Assisted Legal Filing Verification Checklist.

    • Require verification of every citation, quotation, factual assertion, and record reference against the original source before filing.
    • Make the signing lawyer responsible for confirming that verification occurred.
    • Apply the same controls to work prepared by associates, contract lawyers, local counsel, clients, vendors, and AI tools.
    • Preserve enough information about the drafting and verification process to explain it accurately if questioned.
    • When an error is discovered, notify the court and opposing counsel promptly, identify the nature and source of the error, and propose a concrete correction.
    • Do not describe a fabricated authority as a typographical error or silently swap in a different citation.
    • Train lawyers to detect mischaracterizations of real cases, not only nonexistent citations.
    • Treat show-cause orders as urgent risk events requiring independent review and senior oversight.

    Bottom Line

    The Oregon Supreme Court's first AI-related sanctions orders do not ban AI. They show how courts protect the integrity of filings when AI-assisted work reaches the docket without real verification.

    The technology may explain how a false citation appeared, but it does not change who is responsible for filing it. Courts are increasingly focused on three questions: Was the filing verified? Who accepted responsibility for it? What happened after the error was discovered?

    The emerging sanctions record suggests that the last question can determine whether the result is a correctable mistake, a monetary penalty, a lost case, or a career-level disciplinary problem.

    For the broader court-rule landscape, see Federal Court AI Orders Are Splitting Into Clear Patterns and Clearon's AI Litigation Practice Tracker.

    Sources

    Sources

  • The OpenAI Copyright MDL Has Become a Data-Governance Case

    The OpenAI Copyright MDL Has Become a Data-Governance Case

    Current through June 9, 2026.

    The OpenAI copyright multidistrict litigation matters because it has already produced claim-specific rulings and unusually consequential discovery disputes involving model-development records, privilege, and large sets of ChatGPT conversation logs.

    No court has entered a final judgment on whether OpenAI's model training is fair use. The litigation still gives companies a practical warning: ordinary decisions about retention, deletion, vendor terms, and internal records can become central evidence in a major lawsuit.

    Where the MDL stands

    The Judicial Panel on Multidistrict Litigation created MDL No. 3143 on April 3, 2025, transferring four actions to the Southern District of New York for coordinated or consolidated pretrial proceedings. Additional actions have since been transferred.

    The consolidated cases are not identical. They include claims by authors, newspapers, publishers, and other rights holders involving model training, allegedly infringing outputs, contributory infringement, and provisions of the Digital Millennium Copyright Act concerning copyright-management information.

    An MDL coordinates overlapping pretrial work, but it does not turn every plaintiff’s theory into one claim or decide that any claim will succeed.

    The case has moved beyond consolidation

    In a December 15, 2025 ruling involving Ziff Davis, the court allowed several claims to proceed past a motion to dismiss, including contributory-infringement and certain DMCA copyright-management-information claims. It dismissed other theories, including the claim that disregarding robots.txt instructions constituted circumvention of an effective technological measure. The ruling did not decide liability, but it showed that the litigation will turn on specific claims, facts, and model behavior rather than one sweeping answer about AI and copyright.

    Discovery has become just as important as the pleading rulings:

    • In January 2026, Judge Stein upheld orders requiring production of a sample of 20 million de-identified ChatGPT conversation logs.
    • In March 2026, Magistrate Judge Wang granted in part a request involving additional reservoirs of 78 million and 10 million logs, subject to a protocol addressing de-identification and user privacy.
    • In May 2026, the court ordered OpenAI to produce deposition testimony from separate litigation involving Sam Altman, Greg Brockman, Satya Nadella, and an OpenAI corporate designee after finding the narrowed request relevant and proportional.
    • In February 2026, Judge Stein set aside a magistrate judge’s ruling that OpenAI had waived attorney-client privilege over certain 2022 communications concerning the Books1 and Books2 datasets and Library Genesis.

    Those developments do not establish infringement. They do show what an AI copyright case can demand once it reaches coordinated discovery.

    The clearest governance lesson is about data

    The MDL has made retention and discovery policy part of the copyright-risk discussion.

    For enterprise users, the immediate lesson is not that their prompts will necessarily become evidence in this case. It is that vendor data practices, contractual promises, litigation holds, and court-ordered discovery can interact in ways that are easy to overlook during procurement.

    Legal, privacy, security, and procurement teams should ask:

    • What prompts, outputs, metadata, and logs does the vendor retain?
    • Which retention settings are defaults, and which require an enterprise plan or approval?
    • Can ordinary deletion schedules be suspended by a legal hold, court order, or regulatory obligation?
    • What data may be used to improve models, and what requires an affirmative opt-in?
    • Which internal repositories or systems can the tool access?
    • Can the company preserve its own audit trail without collecting more sensitive content than it needs?

    OpenAI states that business-product and API data are not used to train its models by default. It also states that API inputs and outputs are generally removed after 30 days unless legal requirements require retention, and that eligible customers may request zero-data-retention controls for qualifying endpoints. Those are meaningful controls, but buyers still need to understand exceptions, product-specific settings, and what happens when litigation or another legal obligation changes the ordinary retention rules.

    Procurement terms need operational follow-through

    Contract review remains important, but contract language alone is not a governance program.

    Buyers should evaluate vendor representations about training data, output restrictions, indemnity, retention, confidentiality, security, and cooperation during disputes. They should also make sure internal settings and workflows match the negotiated terms.

    A contract may promise strong business-data protections while employees continue using consumer accounts. A zero-retention option does little if it was never enabled for the relevant endpoint. A restriction on confidential data will not help if the organization has no practical rule for deciding which repositories or matters an AI coding or research tool may access.

    Code-generation controls remain useful, but they are a separate issue

    AI-generated code presents a related but distinct set of copyright and open-source-license risks. Companies should not treat the OpenAI MDL as proof that generated code infringes or that any particular compliance control is legally required.

    Still, software companies have practical reasons to treat AI-generated code like third-party code until it is reviewed:

    • use approved enterprise coding tools and accounts;
    • enable public-code matching or reference features where available;
    • require human review for long or unusually specific generated snippets;
    • scan generated code for open-source and snippet-level risks before release;
    • document remediation of flagged code; and
    • restrict sensitive repository and file access.

    GitHub documents a policy that can block Copilot suggestions matching publicly available code or allow them with code references. Cursor states that Privacy Mode enables zero data retention for model providers, while also explaining that some code data may still be stored to provide additional features and that codebase indexing involves uploads for embedding. These controls address different risks. Public-code matching is not a confidentiality control, and privacy settings are not license-clearance tools.

    What legal teams should do now

    1. Map which AI products are in use, including consumer accounts and tools embedded in other software.
    2. Record the actual retention, training, access, and deletion settings for each approved product.
    3. Reconcile vendor contracts with technical configuration and employee practice.
    4. Decide what AI-use records are genuinely needed for audit, compliance, or litigation readiness.
    5. Apply separate controls for confidential data, generated code, external-facing content, and high-risk decisions.
    6. Revisit the program when vendor terms, product settings, or major court rulings change.

    What to watch next

    The most consequential developments will be rulings that clarify training-copy theories, output-based claims, fair use, DMCA liability, and the permissible scope of discovery. Additional transfer orders also matter because they determine which disputes enter the coordinated proceeding.

    For enterprise users, the discovery fights may be as instructive as the eventual merits rulings. They show that AI governance is not limited to deciding whether employees may use a tool. It includes knowing what the tool retains, what the company can control, and what may have to be preserved or produced when litigation begins.

    Sources

  • Federal Court AI Orders Are Splitting Into Clear Patterns

    Federal Court AI Orders Are Splitting Into Clear Patterns

    Current snapshot: June 4, 2026.

    Federal courts are not moving toward one uniform AI rule. They are moving toward a patchwork. Some judges prohibit AI use in filings. Some require disclosure or certification. Others simply remind lawyers that Rule 11, candor, confidentiality, and sanctions rules still apply.

    That makes the practical rule simple: check the forum before filing, check the judge before drafting, and verify every AI-assisted citation, quotation, factual assertion, and legal proposition before it goes to court.

    1. No-use or near no-use orders

    The strictest orders do not merely require disclosure. They prohibit AI use for filings or memoranda.

    Judge Christopher A. Boyko of the Northern District of Ohio has a standing order stating that no attorney or pro se party may use AI in preparing any filing submitted to the court. Judge Sharon Johnson Coleman of the Northern District of Illinois similarly states in her standing requirements that parties may not use AI to draft memoranda or as authority to support motions.

    These orders are still the minority approach, but they matter because they show that some courts view AI-assisted drafting itself as the risk, not just unverified AI output.

    2. Disclose if AI was used

    The more common approach is disclosure. These rules do not necessarily forbid AI. They require the filer to say when AI was used and sometimes to identify the tool or the AI-generated portions.

    The Northern District of Texas now requires a brief prepared using generative AI to disclose that fact on the first page under the heading “Use of Generative Artificial Intelligence.” If the required disclosure is absent, the filing operates as a certification that no part of the brief was prepared using generative AI.

    Judge Michael M. Baylson of the Eastern District of Pennsylvania requires a clear factual statement disclosing AI use in papers filed in cases assigned to him and a certification that all citations to law or the record have been verified. The Southern District of California Bankruptcy Court uses a disclosure and certification form for generative AI use in pleadings, motions, and papers.

    3. Certify or verify the work

    Some courts focus less on whether AI was used and more on whether a human verified the final filing.

    The District of Nebraska’s local rule requires a certificate stating either that no generative AI was used or that a human verified all generated text, including citations and legal authority. The District of Kansas reminds lawyers and pro se litigants that AI-assisted filings remain subject to existing duties of candor and accuracy and warns that the court may strike filings, impose sanctions, or require sworn AI-use statements.

    This bucket is likely to grow because it fits comfortably with the existing professional-responsibility framework: AI can assist, but it cannot be the final authority.

    4. Treat AI output as an unverified source

    Some orders frame the problem as source reliability. The District of Hawaii’s General Order 23-1 treats AI-generated material as an unverified source and requires a declaration when counsel or a pro se party submits material generated by an unverified source.

    That framing is useful. It avoids treating AI as uniquely mysterious and instead places it beside other unverified material: useful as a lead, not good enough as filed authority unless checked.

    But Hawaii’s approach also creates a line-drawing problem. The order defines unverified sources to include AI-generated briefs and memoranda, along with online briefs or memoranda drafted by paid writers that are not tailored to a specific case. The risk is that lawyers may now have to decide not only whether they used AI, but whether a particular research output, template, summary, or purchased work product counts as an “unverified source.”

    The last paragraph of the order matters because it carves out ordinary legal research. The court says the order does not affect basic research tools such as Westlaw, Lexis, or Bloomberg, and that no declaration is required when the sources can be found on those tools. That is a sensible safe harbor for conventional citation checking, but it also raises practical questions as legal research platforms add generative AI features. If a lawyer uses a research platform’s AI summary, answer, or drafting aid, is the source the underlying case law, the research database, or the AI-generated synthesis?

    For lawyers, the safest reading is narrow: a source is not verified merely because it appeared inside a trusted platform. The underlying authority still has to be located, read, and checked. Hawaii’s final paragraph reduces friction for traditional legal research, but it should not be read as a blanket blessing for every AI-assisted feature embedded inside a legal research product.

    5. Protect confidential and proprietary information

    Other orders focus on confidentiality. Judge Stephen Vaden of the Court of International Trade requires disclosure when a filing contains text drafted with generative AI and a certification that the AI use did not disclose confidential or business proprietary information to an unauthorized party.

    This is the piece many lawyers miss. AI orders are not just about fake cases. They are also about what happens when privileged, confidential, sealed, trade secret, business proprietary, health, financial, or export-controlled information is entered into a tool that may store, train on, or transmit user input.

    6. Proposed Federal Rule of Evidence 707

    The most important federal rulemaking item is not a filing-disclosure rule. It is proposed Federal Rule of Evidence 707, which would address machine-generated evidence. The pending rules materials place proposed new Evidence Rule 707 on the December 1, 2027 track.

    That issue is different from AI-assisted drafting. Filing orders ask whether lawyers verified what they submitted. Evidence rules ask whether machine-generated evidence is reliable enough to be admitted.

    What lawyers should do now

    • Check district-wide local rules and judge-specific standing orders before drafting or filing.
    • Do not assume a general Rule 11 review is enough if the judge requires a separate disclosure or certificate.
    • Keep enough internal record of AI use to answer a court question without waiving privilege or exposing mental impressions unnecessarily.
    • Do not enter confidential, privileged, sealed, business proprietary, trade secret, protected health, financial, or export-controlled information into public AI tools.
    • Verify every citation, quotation, factual assertion, record reference, and legal proposition outside the AI tool.

    Help us keep the tracker current

    Clearon AI is tracking federal and state court AI orders, standing orders, local rules, protective-order language, and sanctions decisions. If you have found a court order on AI that is not reflected here, please send it through the Contact page.

    The most helpful submissions include the court, judge, date, docket number or rule number, a link to the order or PDF, and a short note on what the order requires. We will verify submissions against primary court sources before adding them to the tracker.

    Primary sources checked

  • Disney v. Midjourney and the Broader Copyright Question for AI Users

    Disney v. Midjourney and the Broader Copyright Question for AI Users

    Disney v. Midjourney makes the AI copyright fight more concrete.

    The case is about training data, but it is also about outputs that allegedly look too much like famous protected characters and franchise imagery.

    What the case is actually about

    Disney, Universal, and affiliated rights holders sued Midjourney in federal court in Los Angeles on June 11, 2025.

    The case is:

    • Case: Disney Enterprises Inc. v. Midjourney Inc.
    • Court: C.D. Cal.
    • Docket: 2:25-cv-05275
    • Status: pending

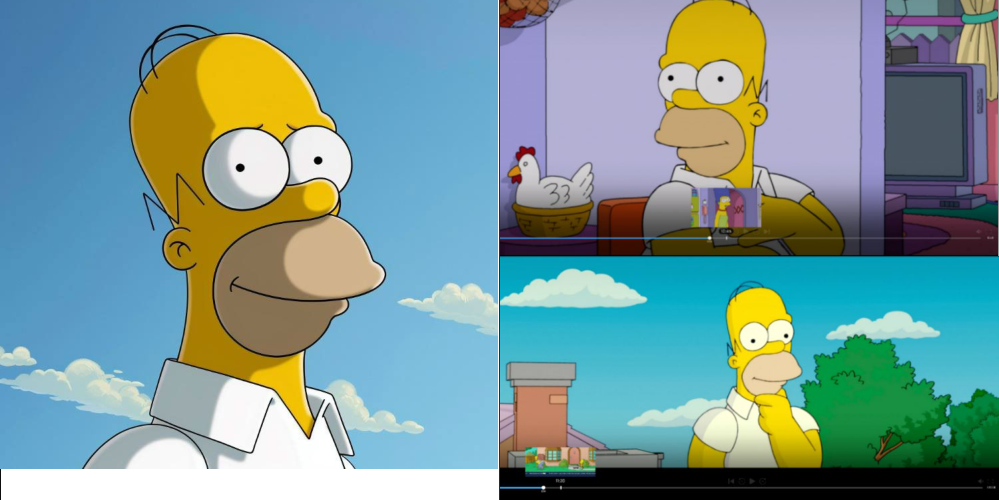
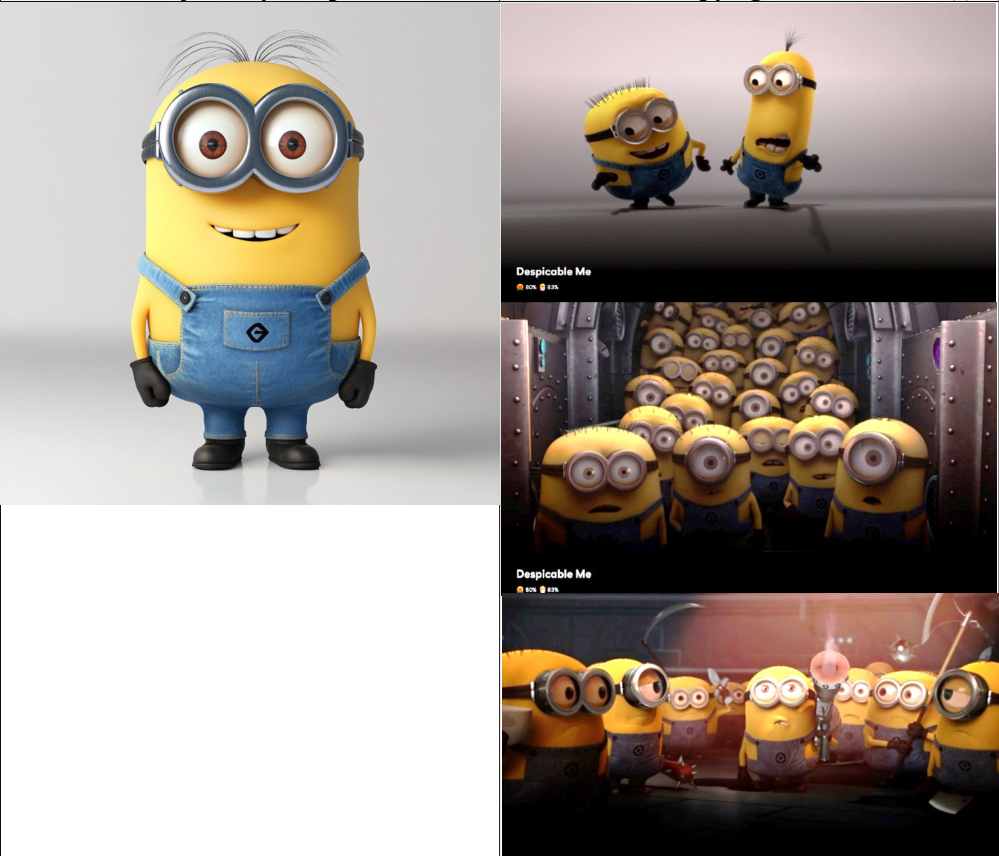
    The studios' position is straightforward. They say Midjourney was built using copyrighted works and that the service can generate outputs that are too close to protected characters and expressive elements. The complaint reportedly includes example prompts and output images involving well-known properties, which is part of why the case landed so clearly in public discussion.

    Two examples from the complaint show why the output issue is getting so much attention:

    Cropped complaint comparison image showing an alleged Midjourney Homer Simpson output beside Disney reference images.
    Cropped complaint comparison image showing an alleged Midjourney Homer Simpson output beside Disney reference images. Source: Complaint, Disney Enterprises Inc. v. Midjourney Inc., No. 2:25-cv-05275 (C.D. Cal.), page 32.
    Cropped complaint comparison image showing an alleged Midjourney Minions output beside Universal reference images.
    Cropped complaint comparison image showing an alleged Midjourney Minions output beside Universal reference images. Source: Complaint, Disney Enterprises Inc. v. Midjourney Inc., No. 2:25-cv-05275 (C.D. Cal.), page 51.

    Midjourney’s likely response is also familiar. Training is not the same as republishing a work. Not every prompted image is substantially similar enough to infringe. And not every reference to a known character, franchise, or visual style cleanly collapses into liability for the platform.

    That is why this case matters. Both sides are arguing about where the legal line sits when a model produces commercially useful images that unmistakably evoke existing protected expression.

    Can businesses use Midjourney images commercially?

    Midjourney’s published guidance says customers generally own the images and videos they create and may use them commercially, subject to its terms and plan requirements. For businesses with more than $1 million in annual gross revenue, Midjourney says a Pro or Mega Plan is required for commercial use.

    That contractual permission is only one part of the analysis. It does not guarantee that a particular output is noninfringing, that the user owns every element in the output, or that the output qualifies for copyright protection. Midjourney’s terms provide the service and assets on an “as is” basis, disclaim a warranty of noninfringement, and place responsibility for using or redistributing assets on the customer.

    For business use, the practical controls should include:

    • confirming that the account and subscription plan permit the intended commercial use;
    • screening prompts and outputs for recognizable characters, logos, protected expression, and other third-party rights;
    • retaining records of prompts, source materials, edits, and human review;
    • requiring additional clearance before using AI-generated images in prominent campaigns, products, or customer deliverables; and
    • reviewing vendor terms regularly because platform rules and protections can change.

    Commercial-use permission from the platform answers whether Midjourney permits the use. It does not answer whether a rights holder may challenge it.

    Related Clearon AI analysis: OpenAI copyright MDL and data governance and AI-generated code and copyleft risk.

    The bigger issue

    For companies, the issue is not just whether Midjourney wins or loses.

    It is whether the business has decided what level of copyright and brand-adjacent risk it is actually willing to accept when employees use generative AI in public-facing work.

    Many legal teams are comfortable saying obvious character replication is out of bounds. The harder question is the gray zone. Is the company willing to rely on a fair use argument if a marketing image is styled to evoke Disney, South Park, or another highly recognizable visual world? Is it comfortable arguing that a prompt drew on a style, not a protected work? Is it willing to defend that position after publication, in a customer campaign, or in court?

    That is the governance issue this case sharpens. Companies need a view on where they are comfortable being aggressive, where they want to be conservative, and which arguments they are actually prepared to stand behind if challenged.

    They also need to account for contract risk, not just copyright doctrine. Most, if not all, major AI image providers put the user on the hook for at least some infringement risk tied to prompts, inputs, or outputs. Even when a vendor offers limited indemnity, it is often narrow and conditional. So a company deciding to operate in the gray zone may also be deciding that it, not the service provider, will carry much of the downstream claim risk.

    The Clearon AI takeaway

    Disney v. Midjourney turns AI copyright risk into a risk-allocation question for users, not just model developers.

    The practical lesson is less “never touch this” and more “decide, in advance, which copyright arguments your company is truly willing to own.”

    Sources

  • The Copilot Litigation Keeps the Copyleft Risk in AI-Generated Code in Play

    The Copilot Litigation Keeps the Copyleft Risk in AI-Generated Code in Play

    Companies are reporting meaningful efficiency gains from AI, and that kind of advantage is quickly making AI tools essential to staying competitive. In software development, tools like GitHub Copilot can speed routine work, shorten timelines, and help teams do more with less.

    But essential does not mean risk-free. From a legal perspective, AI-generated code can create licensing, attribution, and compliance problems if companies are not paying attention. The GitHub Copilot litigation is a useful example because it helps show how those risks can move from the tool provider into the user’s own codebase.

    This article explains the risk and offers practical guidance on both the front end and the back end to help companies reduce it.

    The Copilot case is a warning sign, not a final doctrinal answer

    The district court’s January 22, 2024 order dismissed a number of claims at the pleading stage and narrowed the case substantially, which is an important reminder that the litigation does not establish broad liability simply because the technology is controversial. But the dispute has continued through appeal-related proceedings, including the appellate activity described in this Courthouse News report on the Ninth Circuit argument. For companies watching from the sidelines, that matters. No business needs to wait for a final appellate roadmap before addressing an obvious governance issue.

    It would be a mistake to view the Copilot litigation as a problem limited to GitHub, Microsoft, OpenAI, or the named plaintiffs. The more important corporate question is what happens when a developer accepts AI-generated code and merges it into a proprietary codebase. If the generated output is substantially similar to open-source code, the company may inherit a provenance problem. If the code at issue is associated with a copyleft license, the consequences may be more disruptive than a missed notice or attribution defect. The company may face the argument that its own use, distribution, or incorporation of the code triggers obligations it never intended to accept.

    What makes copyleft risk different

    Many companies already know how to manage conventional open-source software under permissive licenses such as MIT, BSD, or Apache 2.0. Those licenses impose real conditions, but they are usually manageable through familiar inventory, notice, and compliance processes. Copyleft licenses create a different category of concern because they can impose reciprocal obligations that become much more uncomfortable for companies trying to protect proprietary and confidential code. The GNU Project’s explanation of what copyleft means is a useful starting point, even for non-specialists. And courts have long recognized that open-source license conditions can carry real legal force, as the Federal Circuit explained in Jacobsen v. Katzer and as the Northern District of California reinforced in Artifex Software, Inc. v. Hancom, Inc..

    From a practical corporate perspective, the fear is easy to understand: a company may face the argument that code it believed it exclusively owned is subject to broader disclosure, source-availability, or licensing obligations.

    That is the nightmare scenario.

    It is also important not to overstate it. Copyleft consequences are not automatic. Whether any particular use of generated code would trigger meaningful license obligations depends on a fact-intensive analysis and, in a litigated case, on how a court evaluates both the code and the remedy sought. But uncertainty is not a comfort. In many settings, legal ambiguity increases risk because it increases the cost of getting to an answer. Even if a company ultimately prevails, a dispute over provenance, licensing, and code inheritance can produce delay, remediation expense, customer friction, diligence problems in M&A or financing, and significant litigation leverage.

    This is not just a lawyer problem

    AI-generated code often arrives in a form that feels operationally harmless: a helpful function, a well-structured block, a clean suggestion that appears to solve the task at hand. That experience makes it easy to treat the output as legally equivalent to code written from scratch. But provenance is often opaque, and that opacity is the problem. One recurring legal theory in the Copilot case has involved alleged failures to preserve copyright-related information, an issue tied to 17 U.S.C. § 1202.

    A developer may not know whether a snippet is generic, independently generated, loosely informed by training data, or very close to code published in a repository under specific licensing terms. Once that code is accepted, revised, and blended into a broader codebase, tracing the issue later becomes much more expensive.

    So the legal risk begins as a workflow issue. It starts with one prompt, one suggestion, and one merge. It becomes a company problem later, when the code is shipped, reviewed in diligence, examined in discovery, or challenged in a dispute. By then, the cheap fix may be gone.

    The harshest risk should be described carefully — but not ignored

    The worst-case scenario is easy to understand: a claimant argues that the company’s use of AI-generated code has triggered copyleft obligations requiring disclosure or broader licensing of code the company considers confidential and proprietary. That result is not automatic, and it would be careless to say otherwise. Whether such a remedy is plausible in any given case depends on the license, the facts, the nature of the alleged copying, the role of the generated code in the larger work, whether distribution occurred, and the court’s view of appropriate relief. The GNU Project’s GPL FAQ gives a sense of why these questions quickly become complex, even before a court gets involved.

    But companies should not take comfort from the fact that a remedy would be contested. The wiser position is not to become the test case.

    What companies should do now

    The answer is not to ban AI coding tools. The answer is to govern them like they matter.

    That starts with front-end controls:

    • decide which AI coding tools are approved
    • define where they can and cannot be used
    • restrict use in especially sensitive or high-value proprietary repositories
    • train developers not to accept generated code reflexively
    • treat prompts and outputs as compliance-relevant, not just productivity artifacts

    It also requires back-end controls:

    • human code review with a provenance lens
    • open-source scanning and similarity review where appropriate
    • escalation paths for suspicious snippets
    • documentation of AI-generated code use in development workflows
    • rewrite questionable code early instead of litigating over it later

    Governance frameworks can help here. The NIST AI Risk Management Framework is not specific to software licensing, but it provides a useful model for building governance-based controls around AI adoption. Tool selection matters as well. Enterprise-grade offerings with stronger logging, administrative controls, and contractual commitments are often easier to defend than ad hoc usage with little visibility. And for organizations that want a more structured compliance program around open-source use generally, the Linux Foundation’s open-source guidance resources are a practical place to start.

    Front-end controls, however, are not enough. Companies should assume that some risky code may still get through and build back-end review mechanisms designed to catch it before release. That means human review with a provenance lens. Code review should not stop at whether the code compiles, performs, or passes security checks. Where AI coding tools are in use, reviewers should also be alert to suspiciously polished, oddly specific, or poorly explained generated code, especially in contexts where open-source inheritance would create real business pain.

    Technical controls can reinforce that process. Open-source scanning tools, similarity review, provenance checks, and escalation procedures can help surface issues while they are still cheap to solve. If a snippet raises concern, rewriting it may be far less expensive than litigating later about whether the original output carried hidden obligations. Documentation also matters. If AI-generated code is used in development, the company should have some way to record where, when, and under what conditions. Those records can help with internal compliance, incident response, diligence, and eventual litigation posture.

    This is not bureaucracy for its own sake. It is part of building a defensible process.

    How precautions may matter in court

    Reasonable precautions do more than reduce the underlying compliance risk. They also affect how a company looks if a dispute arises. Courts pay attention to conduct. A company that rolled out AI coding tools with no restrictions, no training, no review, and no audit trail presents a very different picture from a company that adopted policies, trained developers, implemented controls, and addressed concerns when they surfaced. That difference may not eliminate liability. But it can matter when a court evaluates intent, proportionality, equitable relief, and remedy. The Supreme Court’s decisions in eBay Inc. v. MercExchange, L.L.C. and Winter v. Natural Resources Defense Council, Inc. are reminders that severe equitable relief is not automatic and depends on traditional equitable principles.

    That point is especially important where the feared remedy is severe. A company that can show genuine preventive and detective efforts is better positioned to argue that any relief should be tailored rather than effectively punitive. Put more plainly, a court may be less inclined to force the harshest result where the defendant can show it tried to prevent the problem on the front end and catch it on the back end.

    Bottom line

    The lesson from the Copilot litigation is not that companies must abandon AI coding tools. It is that they should stop treating those tools as legally neutral. Where generated code may carry hidden open-source obligations, especially copyleft risk, the cost of inattention can be far greater than a routine compliance problem. Companies that adopt sensible controls on the front end and disciplined review on the back end will be better positioned to reduce both the underlying risk and the chance that a court views severe remedies as justified.

  • Your AI Prompts May Not Be Privileged

    Your AI Prompts May Not Be Privileged

    Lawyers and business teams are increasingly using AI to think through legal and risk questions.

    That does not automatically make the prompt, output, or workflow privileged.

    The practical risk is simple: if people put sensitive legal analysis into the wrong AI environment, they may create a discoverable record instead of a protected one.

    This is a privilege, confidentiality, and workflow problem showing up in a new tool.

    The key practical point

    There is a major difference between:

    • a public or lightly controlled AI tool
    • and an enterprise environment with negotiated controls, restricted retention, and clear terms that do not permit your prompts or data to be used to train models for other users

    That distinction should be doing a lot of work in legal AI policy.

    If the tool is not enterprise-approved, if the data controls are unclear, or if the provider can use prompts to improve models for others, legal teams should assume the risk is much higher.

    What not to do

    • Do not paste live dispute facts, investigation details, board communications, draft legal theories, or regulator-response strategy into a casual AI tool.
    • Do not assume a prompt is protected just because it relates to legal advice.
    • Do not let employees use consumer AI tools for sensitive legal work without tool-specific approval.
    • Do not treat “internal” and “privileged” as if they mean the same thing.
    • Do not rely on vague vendor marketing about privacy or security. Check the actual enterprise terms, retention settings, training terms, and admin controls.

    What to do instead

    • Use an enterprise AI environment with contractual controls and settings that prevent your prompts and data from being used to train models for other customers or the public service.
    • Limit legal-use cases to approved tools and approved users.
    • Create a short list of off-limits prompt categories, including litigation strategy, privileged investigation facts, deal-sensitive issues, and regulator-response planning.
    • Require lawyer involvement when the purpose of the workflow is legal advice.
    • Know what records the tool keeps, where they are stored, who can export them, and how long they remain available.

    What recent cases make clear

    Recent attention to cases like United States v. Heppner has put a spotlight on a basic point many organizations still blur: a communication can feel private and still fail privilege requirements.

    In Heppner, Judge Rakoff held that AI-generated materials created through Claude were not protected by attorney-client privilege or the work-product doctrine because the defendant disclosed information to a third-party platform and the materials were not prepared by counsel or at counsel’s direction.

    Different cases can come out differently, and courts are not applying a one-line rule that all AI prompts are discoverable or all AI-assisted work loses protection.

    But that is not a reason for comfort. It is a reason to stop assuming the facts will break your way.

    A useful default rule

    If a prompt would be uncomfortable to hand to an opposing lawyer, regulator, or prosecutor later, it should not be casually entered into an unstructured AI workflow.

    That rule is not perfect, but it is much better than assuming “we were just using AI to think.”

    The takeaway for legal teams

    The real issue is not the model by itself. It is whether the workflow, tool, and contract structure are good enough to support sensitive legal use.

    Clearon AI’s recommendation is not to ban AI for legal work. It is to make sure legal AI use happens inside the right workflow.

    • approve an enterprise AI environment with terms and settings that protect sensitive prompts and do not allow them to train models for other users
    • block consumer or unapproved tools for privileged, litigation, investigation, and regulator-response work
    • limit sensitive legal prompting to approved users and defined use cases
    • give employees concrete do-and-don’t rules instead of vague policy language
    • treat prompt security, retention, and export controls as part of legal workflow design, not an afterthought

    In law, workflow mistakes have a nasty habit of becoming exhibits.