iManage's latest platform shift puts a spotlight on a layer that much legal AI coverage still underrates: governed context.
At ConnectLive 2026, iManage described a platform built around a context fabric, AI-specific controls, agent monitoring, and MCP-based access to institutional knowledge. Strip away the branding and the message is simpler: legal AI infrastructure is not only the model. It is also the system that controls what the model can safely reach.
Where this gets real
For law firms and in-house teams, a good demo is not enough. If AI cannot reach the right knowledge, respect permissions, preserve confidentiality boundaries, and leave a reviewable trail, the polish of the answer does not matter much.
Governed context deserves more attention than the phrase usually gets.
knowledge access
permissions
monitoring
auditability
workflow control
What buyers should watch
iManage is trying to own that layer. That is a sensible strategy, but buyers should still test the claims carefully.
The real diligence questions are whether the controls are granular, whether agent activity is actually visible, and whether firms can connect multiple AI tools without losing control of client and matter boundaries.
The bigger shift
The legal AI market is moving away from “AI as a feature” and toward “AI as a workflow and knowledge infrastructure problem.”
That may sound less exciting than model hype. It is also where the durable power probably sits.
OpenAI's partnership with Eudia offers a useful clue about where legal AI is heading next.
This is a workflow story more than a chatbot story. Eudia says the partnership is aimed at government legal and acquisition teams, combining OpenAI's models with Eudia's operating layer for regulated work.
What matters here is not simply which model sounds smartest. It is who gets inside the workflow and becomes hard to replace.
Government is where this gets real
Government legal and acquisition work is where AI stops feeling like a novelty and starts looking like infrastructure.
Once AI touches contracting, legal review, and mission-critical decisions, buyers need to ask harder questions about:
control
auditability
permissions
human review
vendor concentration risk
Those are not side issues. They are the real product.
What buyers should take from it
The public announcement is still high level, and it does not answer every diligence question. But it is a useful signal.
Frontier-model companies are not staying behind the curtain. They are moving into legal and acquisition workflows through specialized partners that already understand the operating environment.
For legal and procurement teams, that means the smarter evaluation lens is no longer just model quality. It is whether the workflow around the model is governable, reviewable, and defensible.
The bigger shift
This is one more sign that legal AI is moving beyond the demo layer.
The winners may not be the companies with the flashiest model. They may be the ones that control the workflow around it.
Disney v. Midjourney makes the AI copyright fight more concrete.
The case is about training data, but it is also about outputs that allegedly look too much like famous protected characters and franchise imagery.
What the case is actually about
Disney, Universal, and affiliated rights holders sued Midjourney in federal court in Los Angeles on June 11, 2025.
The case is:
Case:Disney Enterprises Inc. v. Midjourney Inc.
Court: C.D. Cal.
Docket: 2:25-cv-05275
Status: pending
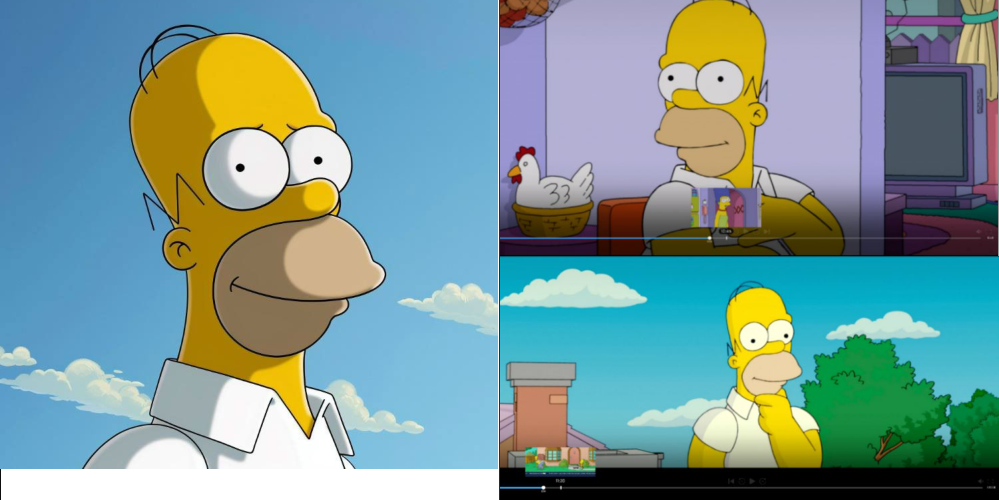
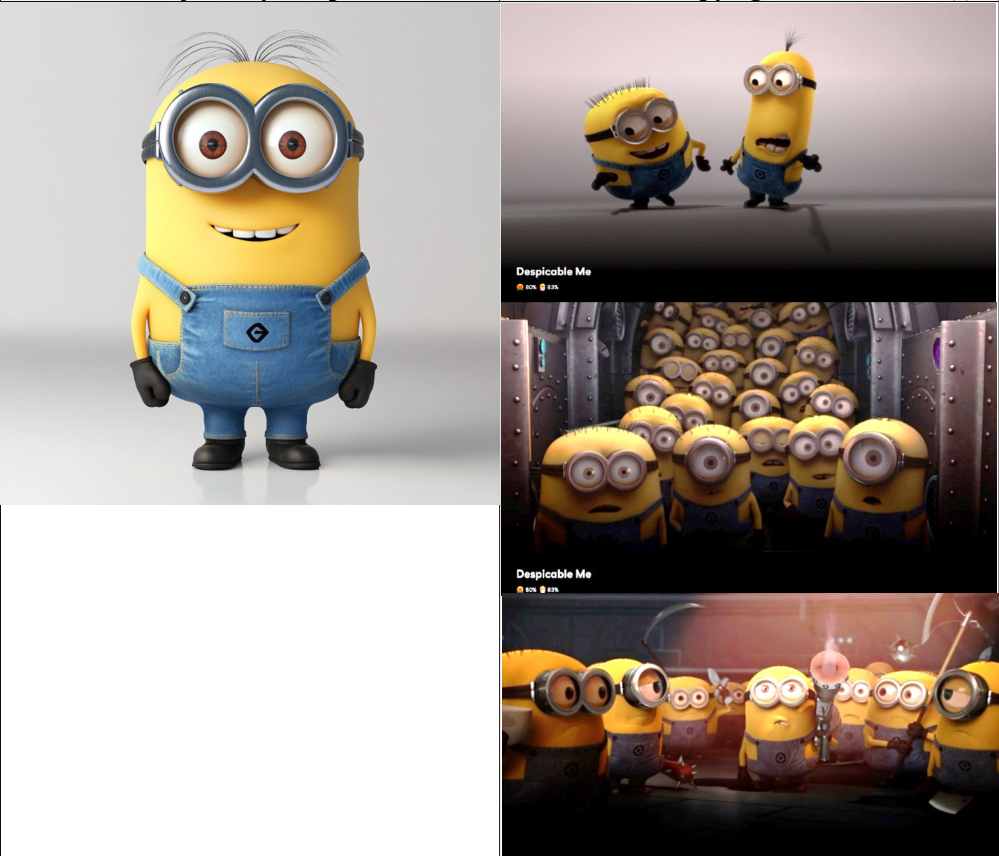
The studios' position is straightforward. They say Midjourney was built using copyrighted works and that the service can generate outputs that are too close to protected characters and expressive elements. The complaint reportedly includes example prompts and output images involving well-known properties, which is part of why the case landed so clearly in public discussion.
Two examples from the complaint show why the output issue is getting so much attention:
Cropped complaint comparison image showing an alleged Midjourney Homer Simpson output beside Disney reference images. Source: Complaint, Disney Enterprises Inc. v. Midjourney Inc., No. 2:25-cv-05275 (C.D. Cal.), page 32.Cropped complaint comparison image showing an alleged Midjourney Minions output beside Universal reference images. Source: Complaint, Disney Enterprises Inc. v. Midjourney Inc., No. 2:25-cv-05275 (C.D. Cal.), page 51.
Midjourney’s likely response is also familiar. Training is not the same as republishing a work. Not every prompted image is substantially similar enough to infringe. And not every reference to a known character, franchise, or visual style cleanly collapses into liability for the platform.
That is why this case matters. Both sides are arguing about where the legal line sits when a model produces commercially useful images that unmistakably evoke existing protected expression.
Can businesses use Midjourney images commercially?
Midjourney’s published guidance says customers generally own the images and videos they create and may use them commercially, subject to its terms and plan requirements. For businesses with more than $1 million in annual gross revenue, Midjourney says a Pro or Mega Plan is required for commercial use.
That contractual permission is only one part of the analysis. It does not guarantee that a particular output is noninfringing, that the user owns every element in the output, or that the output qualifies for copyright protection. Midjourney’s terms provide the service and assets on an “as is” basis, disclaim a warranty of noninfringement, and place responsibility for using or redistributing assets on the customer.
For business use, the practical controls should include:
confirming that the account and subscription plan permit the intended commercial use;
screening prompts and outputs for recognizable characters, logos, protected expression, and other third-party rights;
retaining records of prompts, source materials, edits, and human review;
requiring additional clearance before using AI-generated images in prominent campaigns, products, or customer deliverables; and
reviewing vendor terms regularly because platform rules and protections can change.
Commercial-use permission from the platform answers whether Midjourney permits the use. It does not answer whether a rights holder may challenge it.
For companies, the issue is not just whether Midjourney wins or loses.
It is whether the business has decided what level of copyright and brand-adjacent risk it is actually willing to accept when employees use generative AI in public-facing work.
Many legal teams are comfortable saying obvious character replication is out of bounds. The harder question is the gray zone. Is the company willing to rely on a fair use argument if a marketing image is styled to evoke Disney, South Park, or another highly recognizable visual world? Is it comfortable arguing that a prompt drew on a style, not a protected work? Is it willing to defend that position after publication, in a customer campaign, or in court?
That is the governance issue this case sharpens. Companies need a view on where they are comfortable being aggressive, where they want to be conservative, and which arguments they are actually prepared to stand behind if challenged.
They also need to account for contract risk, not just copyright doctrine. Most, if not all, major AI image providers put the user on the hook for at least some infringement risk tied to prompts, inputs, or outputs. Even when a vendor offers limited indemnity, it is often narrow and conditional. So a company deciding to operate in the gray zone may also be deciding that it, not the service provider, will carry much of the downstream claim risk.
The Clearon AI takeaway
Disney v. Midjourney turns AI copyright risk into a risk-allocation question for users, not just model developers.
The practical lesson is less “never touch this” and more “decide, in advance, which copyright arguments your company is truly willing to own.”
The legal AI signal over that weekend was not a new rule or a splashy lawsuit. It was a clearer market picture.
The biggest vendors were moving closer to legal-specific workflow ownership, clients were getting louder about expecting real AI adoption, and the risk conversation kept shifting from abstract ethics to privilege, supervision, and workflow design.
OpenAI is reportedly planning a legal-specific AI offering
Here are the items worth knowing before the week gets moving.
Artificial Lawyer reported on May 18 that OpenAI is planning a legal offering that could be branded as “Codex for Legal,” with legal-tech hiring and a vertical strategy similar to the company’s broader “Codex for almost everything” push.
What it means for lawyers:
If accurate, this is another sign that major model providers do not want to sit behind generic chat interfaces forever. They want to move into legal-specific workflow, tool integrations, and day-to-day lawyer environments. That raises practical buyer questions about lock-in, governance, and how much of the legal work surface gets controlled by a handful of platform vendors.
Practical takeaway Monday morning:
Legal teams should treat this as a market-structure development, not just another product rumor. If your organization is evaluating legal AI tools, ask where workflow control is heading, what data leaves your environment, and how easily you could switch tools later.
Source: Artificial Lawyer, May 18, 2026.
Anthropic’s legal play is getting harder to dismiss as a side experiment
What happened:
A May 16 Artificial Lawyer analysis of Anthropic’s latest Claude for Legal webinar described a platform that now has 12 legal plugins, customization options, MCP connectors, and a clear push to stay inside the lawyer’s working environment, especially around Microsoft Word and related tools.
What it means for lawyers:
The more interesting point is not plugin count. It is the strategic direction. Anthropic appears to be competing to become part of the lawyer’s primary workspace rather than a bolt-on drafting helper. That has consequences for procurement, document governance, supervision, and training because the tool starts to shape how legal work is actually done.
Practical takeaway Monday morning:
If you are buying or piloting legal AI this quarter, compare products on workflow fit and governance controls, not just answer quality. The winning tool may be the one that best controls document flow, user permissions, and auditability.
Source: Artificial Lawyer, May 16, 2026.
One Friday item that still matters Monday: clients are openly warning firms not to lag on AI
What happened:
In a May 15 Law.com Corporate Counsel Q&A, Salesforce chief legal officer Sabastian Niles said firms that fail to embrace AI risk losing efficiency, talent, and clients.
What it means for lawyers:
This is the client-pressure version of the legal AI story. The issue is no longer just whether firms can use AI safely. It is whether sophisticated buyers will start treating competent AI adoption as part of baseline service quality. That puts pressure on outside counsel to show not only that they use AI, but that they use it in a controlled, defensible way.
Practical takeaway Monday morning:
Law firms should be ready for more AI diligence from clients, especially around approved tools, data handling, supervision, and billing expectations. In-house teams should expect more firms to market AI capability and should separate real workflow maturity from demo-stage claims.
Source: Law.com Corporate Counsel, May 15, 2026.
The risk conversation is moving toward privilege architecture, not generic AI fear
What happened:
An ACC program scheduled for May 18 frames 2026 legal AI risk around privilege, discovery, professional responsibility, meeting notetakers, vendor diligence, and what it calls a defensible “privilege architecture.”
What it means for lawyers:
That framing is useful because it is more mature than blanket “don’t use AI” advice. The issue is no longer whether AI creates risk. Of course it does. The harder and more practical question is what legal workflow, vendor terms, access controls, and supervision rules let teams use AI without casually blowing confidentiality or evidentiary discipline.
Practical takeaway Monday morning:
This week is a good time to review whether your organization has an actual AI workflow policy for legal work, not just a general AI statement. Sensitive legal use should happen only in an approved enterprise environment with clear rules on prompts, retention, exports, and human review.
Source: Association of Corporate Counsel program page, May 18, 2026.
What to watch this week
Watch whether the legal AI story keeps consolidating around workflow ownership. OpenAI, Anthropic, contract platforms, and enterprise clients all seem to be pushing in the same direction: less interest in standalone AI novelty, more interest in who controls the place where legal work gets drafted, reviewed, approved, and handed off.
If that trend holds, the most important legal AI questions this week will not be which model is smartest. They will be who owns the workflow, what are the guardrails, and what happens to client trust when those answers are fuzzy.
Under section 80 of the Data (Use and Access) Act, the UK has replaced the old Article 22 framework with a more permissive structure: automated decision-making with safeguards, rather than a prohibition-first starting point.
This is a real shift
Under the classic Article 22 model, the analysis usually began with a restriction. The UK's newer approach is more operational and less categorical. The question becomes less "is this forbidden unless an exception applies?" and more "what safeguards, transparency, and review rights are required when this happens?"
That may sound subtle, but it matters. It gives companies more room to deploy automated systems, while also increasing pressure to justify how those systems are used.
What multinational teams should watch
A lot of organizations still hope they can run one clean global policy for AI-enabled decision-making. The UK’s move makes that harder. If the EU and UK keep drifting apart here, legal teams may need separate assessments for profiling, scoring, and model-driven recommendations that affect individuals.
That does not just affect flashy AI products. It can reach ordinary systems used in employment, insurance, financial services, fraud detection, customer eligibility, and prioritization workflows.
The takeaway
The UK is not abandoning regulation. It is choosing a different posture. A permission-with-safeguards model still requires governance, and in some ways it requires better governance because companies have more room to act.
Cross-border AI compliance is starting to look less like one policy problem and more like jurisdiction management. That is the part legal teams should plan around now.
Illinois is becoming one of the clearest examples of where employment AI regulation is heading: notice, documentation, and practical scrutiny of how tools influence decisions.
If you want the official bill history, Illinois’s law is here: HB 3773. The Illinois Department of Human Rights also has a direct summary page here: Artificial Intelligence in Employment.
Recent draft rules from the Illinois Department of Human Rights would implement the state's newer restrictions on AI discrimination in employment. The bigger point is the compliance model taking shape around them.
The trigger looks broad
The reported standard is not limited to futuristic hiring bots. The rules would apply when AI is used “to influence or facilitate” covered employment decisions, including recruiting, hiring, promotion, discipline, discharge, training selection, and terms or conditions of employment.
That deserves attention because the notice trigger may be broader than many employers expect. If AI is involved in screening resumes, targeting job ads, evaluating candidates, analyzing interviews, or helping shape employment outcomes, notice may be required even if the employer did not intend discrimination.
Employment AI is becoming an operations issue
The trend line is clear: employment AI law is moving away from “prove the tool caused unlawful bias first” and toward “tell people when the tool is in the process, document what it is doing, and be ready to defend the workflow.”
That is why legal teams need a real inventory of where AI shows up in the employment stack, not just in one recruiting product. AI can appear in sourcing, ranking, interview analytics, assessments, chatbots, promotion systems, and workforce-monitoring features.
The takeaway
The answer is not to ban every automated feature. It is to map the tools, define which ones influence covered decisions, and decide where notice, contract review, testing, and documentation are required.
Illinois is sending a simple message: if AI helps shape employment outcomes, silence is not a compliance strategy.
California's latest AI move did not come through a broad consumer AI statute. It came through procurement.
If you want the official source, California’s executive order is here: Executive Order N-5-26.
In March 2026, Governor Gavin Newsom issued Executive Order N-5-26, directing the state to build a new procurement framework for AI. That may sound narrower than a headline AI law, but it could matter just as much for companies that sell AI tools or services into large buyers.
Procurement is where AI governance gets real
The order points toward a system in which AI vendors may need to make structured representations about how their systems are built, governed, and monitored. That includes familiar pressure points like data handling, bias controls, civil-liberties protections, and related safeguards.
Procurement is where abstract AI principles often become contract obligations. It is easy to talk about responsible AI in marketing language. It is much harder to answer a buyer's concrete questions about training data, oversight, controls, auditability, and remediation.
What legal teams should take from it
Procurement is one of the fastest ways to force operational discipline. Buyers can demand certifications, representations, warranties, and disclosure commitments long before legislatures settle every policy fight.
That means legal departments are no longer just debating AI governance in theory. They are negotiating it in contracts.
The takeaway
For vendors, the lesson is simple: if governance documentation does not exist in a usable form, build it now. For buyers, California offers a practical model for imposing more discipline on higher-risk AI tools without waiting for a perfect statute.
California is not just regulating AI through lawmaking. It is shaping the market through purchasing power. That is often how governance becomes real.
Connecticut has moved from “state to watch” to a state companies may actually need to operationalize against.
If you want the official bill text, Connecticut’s latest substitute text is here: SB 5.
On May 1, 2026, the legislature passed SB 5, a broad AI bill that would place Connecticut among the more aggressive state players in AI governance. The point is not just that another state acted. It is that Connecticut appears to be building a framework that spans multiple AI risk areas at once.
What makes this state move worth watching
A lot of state AI proposals focus on one slice of the problem, usually hiring tools, consumer protection, or deepfakes. Connecticut's approach is broader. It treats AI governance as a cross-functional legal problem rather than a niche product issue.
That matters because it better reflects how organizations actually use AI. AI now touches hiring, customer communications, vendor tools, automated decisions, synthetic media, and internal workflows.
The patchwork problem is getting harder
SB 5 is also another reminder that federal law is not about to simplify the map. States are continuing to legislate, and they are doing it with different definitions, priorities, and enforcement models.
That creates two practical tasks for legal teams. First, they need a real inventory of where AI shows up in the business. Second, they need a governance structure that can absorb state variation without rewriting the whole policy stack every time a legislature moves.
The takeaway
Connecticut’s bill may not become the national template by itself. But it does point toward the future: AI governance that looks more like privacy or employment compliance, meaning state-specific, operationally demanding, and hard to solve with one policy memo.
Connecticut is not the whole story. But it is increasingly part of the real one.
Colorado's AI law is moving again before many companies have even finished mapping the original version.
If you want the official text, the Colorado bill is here: SB26-189.
In May 2026, lawmakers passed SB 26-189, a major rewrite of the state's earlier AI framework. The main shift is from regulating broadly defined “high-risk AI systems” to regulating automated decision-making technology, or ADMT, when it materially influences consequential decisions.
What stands out is how directly the law targets decision environments legal teams already care about: employment, housing, lending, insurance, health care, education, and essential government services. The practical question is less about what a tool is called and more about how it is used when it affects a person in a meaningful way.
The new focus is operational accountability
The revised bill is set to take effect on January 1, 2027. That buys time, but it also makes the compliance direction clearer.
Developers would need to give deployers technical documentation on intended uses, training data categories, limitations, and human-review instructions. Deployers would need to provide consumer notices and, after an adverse outcome, a plain-language explanation of the role the system played. Consumers would also have rights to seek correction of inaccurate data and meaningful human review.
What legal teams should focus on
This is especially important for employment and other high-impact workflows. Recruiting tools, ranking systems, interview-analysis products, and recommendation engines can all end up inside the regulatory frame if they materially influence decisions.
That means the compliance question becomes more concrete: what is the system doing, who is relying on it, what notice is required, and what happens when someone challenges the outcome?
The bigger lesson
Colorado’s rewrite is a useful reminder that state AI compliance is still moving in real time. Static AI policies are going to age badly. Legal and compliance teams need a more flexible operating model that can absorb changing definitions, disclosure duties, and review rights across states.
The takeaway is not that Colorado is backing away from AI regulation. It is that Colorado is trying to make its law more targeted and more workable. For companies using AI in consequential decisions, the safer question is not “do we use AI?” but “can we explain and defend how this system influenced the decision?”
Companies are reporting meaningful efficiency gains from AI, and that kind of advantage is quickly making AI tools essential to staying competitive. In software development, tools like GitHub Copilot can speed routine work, shorten timelines, and help teams do more with less.
But essential does not mean risk-free. From a legal perspective, AI-generated code can create licensing, attribution, and compliance problems if companies are not paying attention. The GitHub Copilot litigation is a useful example because it helps show how those risks can move from the tool provider into the user’s own codebase.
This article explains the risk and offers practical guidance on both the front end and the back end to help companies reduce it.
The Copilot case is a warning sign, not a final doctrinal answer
The district court’s January 22, 2024 order dismissed a number of claims at the pleading stage and narrowed the case substantially, which is an important reminder that the litigation does not establish broad liability simply because the technology is controversial. But the dispute has continued through appeal-related proceedings, including the appellate activity described in this Courthouse News report on the Ninth Circuit argument. For companies watching from the sidelines, that matters. No business needs to wait for a final appellate roadmap before addressing an obvious governance issue.
It would be a mistake to view the Copilot litigation as a problem limited to GitHub, Microsoft, OpenAI, or the named plaintiffs. The more important corporate question is what happens when a developer accepts AI-generated code and merges it into a proprietary codebase. If the generated output is substantially similar to open-source code, the company may inherit a provenance problem. If the code at issue is associated with a copyleft license, the consequences may be more disruptive than a missed notice or attribution defect. The company may face the argument that its own use, distribution, or incorporation of the code triggers obligations it never intended to accept.
What makes copyleft risk different
Many companies already know how to manage conventional open-source software under permissive licenses such as MIT, BSD, or Apache 2.0. Those licenses impose real conditions, but they are usually manageable through familiar inventory, notice, and compliance processes. Copyleft licenses create a different category of concern because they can impose reciprocal obligations that become much more uncomfortable for companies trying to protect proprietary and confidential code. The GNU Project’s explanation of what copyleft means is a useful starting point, even for non-specialists. And courts have long recognized that open-source license conditions can carry real legal force, as the Federal Circuit explained in Jacobsen v. Katzer and as the Northern District of California reinforced in Artifex Software, Inc. v. Hancom, Inc..
From a practical corporate perspective, the fear is easy to understand: a company may face the argument that code it believed it exclusively owned is subject to broader disclosure, source-availability, or licensing obligations.
That is the nightmare scenario.
It is also important not to overstate it. Copyleft consequences are not automatic. Whether any particular use of generated code would trigger meaningful license obligations depends on a fact-intensive analysis and, in a litigated case, on how a court evaluates both the code and the remedy sought. But uncertainty is not a comfort. In many settings, legal ambiguity increases risk because it increases the cost of getting to an answer. Even if a company ultimately prevails, a dispute over provenance, licensing, and code inheritance can produce delay, remediation expense, customer friction, diligence problems in M&A or financing, and significant litigation leverage.
This is not just a lawyer problem
AI-generated code often arrives in a form that feels operationally harmless: a helpful function, a well-structured block, a clean suggestion that appears to solve the task at hand. That experience makes it easy to treat the output as legally equivalent to code written from scratch. But provenance is often opaque, and that opacity is the problem. One recurring legal theory in the Copilot case has involved alleged failures to preserve copyright-related information, an issue tied to 17 U.S.C. § 1202.
A developer may not know whether a snippet is generic, independently generated, loosely informed by training data, or very close to code published in a repository under specific licensing terms. Once that code is accepted, revised, and blended into a broader codebase, tracing the issue later becomes much more expensive.
So the legal risk begins as a workflow issue. It starts with one prompt, one suggestion, and one merge. It becomes a company problem later, when the code is shipped, reviewed in diligence, examined in discovery, or challenged in a dispute. By then, the cheap fix may be gone.
The harshest risk should be described carefully — but not ignored
The worst-case scenario is easy to understand: a claimant argues that the company’s use of AI-generated code has triggered copyleft obligations requiring disclosure or broader licensing of code the company considers confidential and proprietary. That result is not automatic, and it would be careless to say otherwise. Whether such a remedy is plausible in any given case depends on the license, the facts, the nature of the alleged copying, the role of the generated code in the larger work, whether distribution occurred, and the court’s view of appropriate relief. The GNU Project’s GPL FAQ gives a sense of why these questions quickly become complex, even before a court gets involved.
But companies should not take comfort from the fact that a remedy would be contested. The wiser position is not to become the test case.
What companies should do now
The answer is not to ban AI coding tools. The answer is to govern them like they matter.
That starts with front-end controls:
decide which AI coding tools are approved
define where they can and cannot be used
restrict use in especially sensitive or high-value proprietary repositories
train developers not to accept generated code reflexively
treat prompts and outputs as compliance-relevant, not just productivity artifacts
It also requires back-end controls:
human code review with a provenance lens
open-source scanning and similarity review where appropriate
escalation paths for suspicious snippets
documentation of AI-generated code use in development workflows
rewrite questionable code early instead of litigating over it later
Governance frameworks can help here. The NIST AI Risk Management Framework is not specific to software licensing, but it provides a useful model for building governance-based controls around AI adoption. Tool selection matters as well. Enterprise-grade offerings with stronger logging, administrative controls, and contractual commitments are often easier to defend than ad hoc usage with little visibility. And for organizations that want a more structured compliance program around open-source use generally, the Linux Foundation’s open-source guidance resources are a practical place to start.
Front-end controls, however, are not enough. Companies should assume that some risky code may still get through and build back-end review mechanisms designed to catch it before release. That means human review with a provenance lens. Code review should not stop at whether the code compiles, performs, or passes security checks. Where AI coding tools are in use, reviewers should also be alert to suspiciously polished, oddly specific, or poorly explained generated code, especially in contexts where open-source inheritance would create real business pain.
Technical controls can reinforce that process. Open-source scanning tools, similarity review, provenance checks, and escalation procedures can help surface issues while they are still cheap to solve. If a snippet raises concern, rewriting it may be far less expensive than litigating later about whether the original output carried hidden obligations. Documentation also matters. If AI-generated code is used in development, the company should have some way to record where, when, and under what conditions. Those records can help with internal compliance, incident response, diligence, and eventual litigation posture.
This is not bureaucracy for its own sake. It is part of building a defensible process.
How precautions may matter in court
Reasonable precautions do more than reduce the underlying compliance risk. They also affect how a company looks if a dispute arises. Courts pay attention to conduct. A company that rolled out AI coding tools with no restrictions, no training, no review, and no audit trail presents a very different picture from a company that adopted policies, trained developers, implemented controls, and addressed concerns when they surfaced. That difference may not eliminate liability. But it can matter when a court evaluates intent, proportionality, equitable relief, and remedy. The Supreme Court’s decisions in eBay Inc. v. MercExchange, L.L.C. and Winter v. Natural Resources Defense Council, Inc. are reminders that severe equitable relief is not automatic and depends on traditional equitable principles.
That point is especially important where the feared remedy is severe. A company that can show genuine preventive and detective efforts is better positioned to argue that any relief should be tailored rather than effectively punitive. Put more plainly, a court may be less inclined to force the harshest result where the defendant can show it tried to prevent the problem on the front end and catch it on the back end.
Bottom line
The lesson from the Copilot litigation is not that companies must abandon AI coding tools. It is that they should stop treating those tools as legally neutral. Where generated code may carry hidden open-source obligations, especially copyleft risk, the cost of inattention can be far greater than a routine compliance problem. Companies that adopt sensible controls on the front end and disciplined review on the back end will be better positioned to reduce both the underlying risk and the chance that a court views severe remedies as justified.