Author: Clearon AI

  • The FRONTIER Act Narrows the Federal AI Preemption Fight

    The FRONTIER Act Narrows the Federal AI Preemption Fight

    The FRONTIER Act Narrows the Federal AI Preemption Fight

    The Great American AI Act draft was a warning shot.

    The FRONTIER Act is the narrower bill.

    On July 23, 2026, Representative Jay Obernolte introduced H.R. 9925, the Frontier Risk Oversight, National Transparency, Independent Evaluation, and Reporting Act, or FRONTIER Act, with Representative Lori Trahan and other bipartisan cosponsors. GovInfo lists the bill as introduced in the House and referred to the House Committee on Energy and Commerce and the House Committee on Science, Space, and Technology.

    That matters because the earlier Great American AI Act materials were still a discussion draft. Clearon's earlier coverage treated them that way. H.R. 9925 is different: it is introduced bill text, though still only a pending bill, and it shows where the sponsors moved after the first round of criticism.

    The short version is this: the bill still tries to create a federal rulebook for frontier AI risk. But the state-law preemption clause is more targeted than the broad discussion-draft fight suggested.

    What The Bill Would Cover

    The FRONTIER Act is not a general AI law for every company using automated tools.

    It is aimed at frontier models and frontier developers. The bill defines a frontier model as a foundation model trained using more than 10^26 integer or floating-point operations, including the original training run and later fine-tuning, reinforcement learning, or other substantial modification.

    It then builds tiered duties around developers that meet revenue and AI-development-spending thresholds. Some duties apply to frontier developers generally, while the public-framework, audit, registration, and independent-verification layers turn on the larger statutory tiers.

    A "large frontier developer" would have to have gross revenues in excess of $50 million and incur at least $1 billion in AI-related development expenditures, measured together with affiliates during the preceding 36-month period and determined as of the first day of each calendar month. A "very large frontier developer" would have to have gross revenues in excess of $5 billion and incur at least $10 billion in AI-related development expenditures under the same affiliate-inclusive, monthly measurement structure.

    Those thresholds are doing important work. The bill is not trying to regulate ordinary business AI deployments, routine SaaS use, or most smaller model builders in the same way. It is aimed at the companies training and operating the most capable frontier systems.

    The Public Framework Requirement

    For large frontier developers, the main operational duty starts with a public frontier AI framework.

    By the later of one year after enactment or 90 days after first qualifying as a large frontier developer, the developer would have to write, implement, comply with, and clearly publish a frontier AI framework on a public website.

    That framework would have to address how the developer identifies catastrophic-risk thresholds, assesses whether a model could cross those thresholds, reviews the results of risk assessment and mitigation before deployment or internal use, uses third parties to assess risk, updates the framework, secures nonpublic model weights, responds to critical safety incidents, and implements internal governance.

    This is more concrete than a voluntary responsible-AI pledge. It would turn frontier risk governance into a public compliance artifact.

    That does not mean every detail becomes public. The bill allows redactions to protect trade secrets, risk-prevention mechanisms, cybersecurity, public safety, national security, or compliance with federal or state law. But the structure still points toward a world where the largest developers need a publishable governance file, not just internal assurances.

    Audits, Reports, And Incident Duties

    By the later of one year after enactment or 90 days after first qualifying as a large frontier developer, and annually thereafter, the bill would require a large frontier developer to retain a third party to audit compliance with the developer's own frontier AI framework.

    The audit structure matters because it would not merely ask whether the developer has a framework. It would ask whether the developer is following it. The auditor would need demonstrated competence, including access to technical expertise in frontier-model safety, and the bill bars either side from holding a financial interest in the other.

    H.R. 9925 also would require model-level transparency reports before or concurrent with deployment of a new frontier model or a substantial modification. Those reports would include release date, supported languages, output modalities, intended uses, restrictions or conditions, catastrophic-risk assessments, assessment results, third-party involvement, and other steps taken under the framework. The summaries would have to be provided in machine-readable format to facilitate verification of model claims.

    Critical safety incidents get a separate clock. The bill would require the Under Secretary of Commerce for AI Security to create a confidential reporting mechanism within 180 days after enactment. A frontier developer would have to report a critical safety incident within 72 hours after learning facts sufficient to establish a reasonable belief that one occurred. If the incident poses an imminent risk of death or serious physical injury, the developer would have to report to law enforcement within 24 hours.

    For compliance teams, those deadlines are the practical signal. If the bill moves, frontier developers would need escalation criteria and evidence records before an incident happens.

    The Independent Verification Layer

    The heaviest obligations fall on very large frontier developers.

    By the later of one year after the Under Secretary first licenses an independent verification organization with capacity to accept an engagement or 90 days after a developer first qualifies as very large, the developer would have to retain a licensed IVO to perform ongoing assessments.

    Those assessments would cover the adequacy of the developer's frontier AI framework, governance practices, risk monitoring, and mitigation of detected risks. They would apply not only to released models, but also to catastrophic risks from internal use of frontier models.

    The IVO would need access to unredacted materials, records, personnel, systems, and other information reasonably necessary for the assessment. The developer could impose reasonable security and confidentiality protocols, but material limits on access would have to be described in the assessment report.

    The IVO report would have to address scope, limitations, the adequacy of the developer's framework and governance, identified failures or weaknesses, recommended corrective actions, and certifications about accuracy, qualifications, conflicts of interest, and compliance with regulations.

    That is a significant compliance design. It would create a regulated market for AI verification organizations and make the independence of that market a policy issue in its own right. The bill recognizes that by requiring annual Government Accountability Office reports on the IVO market, including barriers to entry and threats to independence from the AI industry.

    The Preemption Clause Is Narrower, But Still Important

    The earlier discussion draft drew attention because it tried to divide federal and state authority over AI. H.R. 9925 keeps that fight, but narrows the covered field.

    Section 9 preempts state and local laws that impose new substantive obligations on artificial intelligence developers with respect to a defined "Covered Subject Area." For this section, the bill uses a broader definition of "artificial intelligence developer": an entity that builds, designs, codes, produces, trains, or owns an AI model for internal or third-party use, excluding entities that are solely deployers.

    That means Section 9 is not limited to the bill's narrower "frontier developer" definition, even though the covered subject areas are tied to frontier AI risk transparency, frontier AI third-party auditing and independent verification, and frontier AI incident reporting.

    That is not the same as preempting all state AI law.

    The bill expressly preserves generally applicable laws that do not target AI developers. It also preserves state authority to regulate the use or deployment of AI systems by deployers or users, including through consumer protection, civil-rights, contract, criminal, or privacy laws, so long as those laws do not impose substantive obligations on developers with respect to model development, training, evaluation, or release.

    It also preserves state laws specifically relating to protection of minors from harms arising from AI systems, including sexually explicit content, self-harm content, exploitation, age verification, parental controls, and similar matters. And it preserves state procurement and use rules for state governments.

    That narrowing is the legal story. The sponsors appear to be moving from a broader preemption fight toward a more focused claim: if Congress creates a federal catastrophic-risk transparency, audit, verification, and incident-reporting regime for frontier developers, states should not create parallel developer-side obligations in the same lane.

    States would still have room to regulate many downstream AI uses. The hardest disputes would sit at the boundary. A state rule framed as product transparency, child safety, consumer protection, or procurement may be preserved. A rule that reaches developer-side frontier risk testing, reporting, audits, certifications, or release conditions may be challenged as preempted.

    Emergency Orders Are The Enforcement Backstop

    H.R. 9925 also gives the Secretary of Commerce emergency-order authority.

    The Secretary could suspend or restrict a frontier developer's development, deployment, or internal use of a frontier model upon finding that the activity presents an imminent catastrophic risk. The bill sets procedures for written findings, technical assessments where methods have been published, consultation with the Under Secretary, provisional and final orders, judicial review, and penalties.

    Violating an emergency order could trigger civil penalties of up to $10 million per violation. Willful violations could carry criminal penalties of up to $1 million per violation, imprisonment for up to 10 years, or both.

    Those provisions are narrow, but they show the bill is not only a reporting proposal. It would give the federal government a direct intervention tool for imminent catastrophic risk.

    What Companies Should Watch

    Most companies would not become frontier developers under H.R. 9925. But the bill still matters outside the frontier lab because it sketches the federal-state boundary Congress may try to draw.

    Frontier developers should watch the thresholds, the definition of catastrophic risk, the content of the public framework, the 72-hour and 24-hour incident clocks, the registration/disclosure duty, and the IVO assessment process.

    Companies that deploy third-party AI systems should watch a different issue: what the bill leaves to states. H.R. 9925 preserves state regulation of deployers and users, including consumer protection, civil rights, privacy, contract, criminal law, child safety, procurement, and state-government use. That means a federal frontier bill would not erase downstream state compliance work.

    Audit and assurance providers should watch the IVO licensing rules. The bill would require independence, conflict-of-interest controls, technical competence, access to developer records and systems, and signed certifications. That is closer to regulated assurance than ordinary consulting.

    State-policy teams should watch the boundary language. The next fight will not be "federal law or state law." It will be whether a particular state rule targets developer-side frontier risk governance or downstream use.

    Bottom Line

    The FRONTIER Act is the introduced-bill version of a narrower federal AI bargain.

    It would place public frameworks, third-party audits, incident reporting, independent verification, registration, and emergency-order authority around the largest frontier developers. In return, it would limit state and local developer-side obligations in the covered catastrophic-risk transparency, audit, verification, and incident-reporting lanes.

    That is why H.R. 9925 is worth tracking even if it is far from enactment. It is one of the clearest current attempts to answer the question that keeps coming back in U.S. AI law: which layer belongs to Washington, and which layer remains with the states?
    Sources

  • D.C. Court Says AI Citation Ignorance Is No Longer Credible

    D.C. Court Says AI Citation Ignorance Is No Longer Credible

    D.C. Court Says AI Citation Ignorance Is No Longer Credible

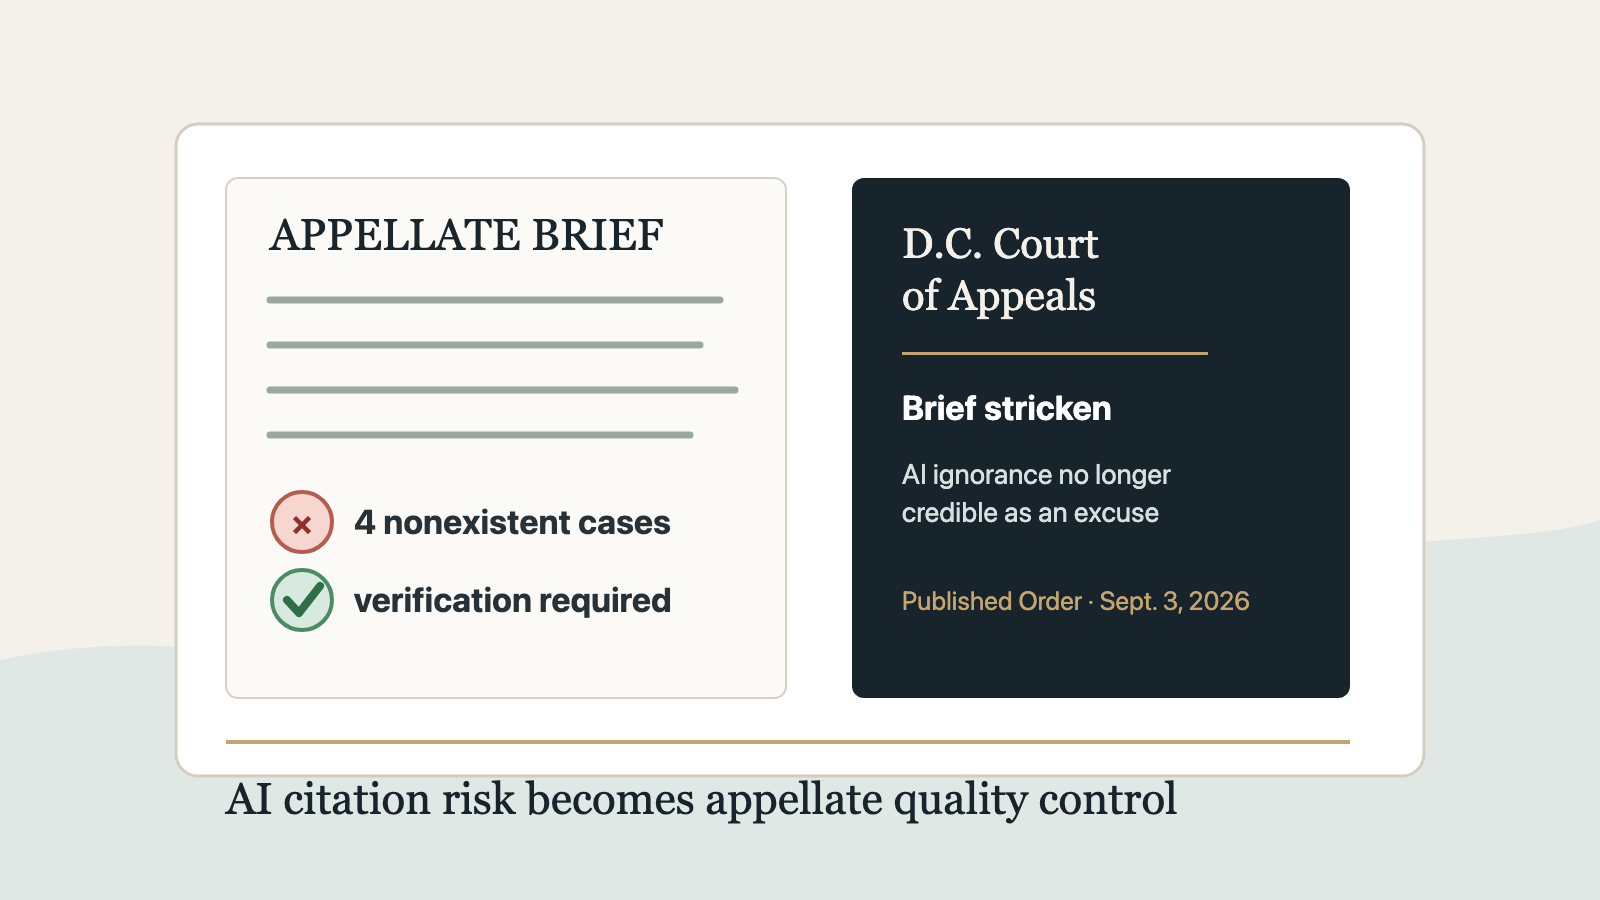
    The D.C. Court of Appeals has now said the quiet part plainly: lawyers can no longer credibly claim they did not know generative AI can invent legal authority.

    In Douglas v. Deutsche Bank National Trust Co., the court struck Deutsche Bank's appellee brief after discovering four nonexistent cases. The order says one of Deutsche Bank's lawyers used Google's generative AI search tool to assist in finding authority and did not verify the cited cases before the brief was filed.

    That would be enough for a short sanctions note.

    But the published order is more useful than that. It treats the fake citations as a supervision, competence, and appellate-rule problem. It also exposes a harder institutional question: what should an appellate court do when its existing rules let it strike a defective brief and refer the matter for discipline, but may not clearly authorize more targeted sanctions against the lawyers responsible?

    That makes Douglas worth reading beyond the usual warning not to paste AI output into a brief.

    What Happened

    The appeal started as a foreclosure case. Deutsche Bank had won judgment on the pleadings in D.C. Superior Court, and Barry Douglas appealed without counsel.

    After the appeal was submitted without argument, the D.C. Court of Appeals reviewed Deutsche Bank's brief and found multiple case citations it could not locate or confirm. On June 22, the court ordered Deutsche Bank to show cause why the brief should not be struck for citing nonexistent cases that were possibly the product of AI hallucinations.

    The next day, attorney Loishirl W. Hall responded in her own capacity. According to the order, she confirmed that four cited authorities did not exist and acknowledged that they were not legitimate legal authority. She explained that she had used Google's generative AI search tool to help locate case authority and had not verified the existence or accuracy of the citations before filing.

    The firm, McCabe, Weisberg & Conway, filed a separate response. The order says the firm represented that it prohibits employees from using AI in drafting legal correspondence or documents and trains employees that citations must be verified regardless of source. But the court noted that the firm did not attach the policy and did not detail what it had done to supervise or review Hall's work.

    The court's result was direct: Deutsche Bank's brief was stricken.

    It also referred the matter to the Office of Disciplinary Counsel for whatever investigation that office deems appropriate.

    The Court's Real Message

    The order is not anti-AI. It says the court's intent is not to discourage lawyers from using AI and acknowledges that lawyers may now need at least an understanding of AI at their own peril.

    The line the court draws is different.

    AI use does not change the lawyer's duty to verify legal authority. The order says the use of AI is now so pervasive in legal practice that lawyers can no longer credibly claim ignorance of its pitfalls, including hallucinated legal authority. It cites ABA Formal Opinion 512, D.C. and other professional-responsibility guidance, and a growing body of court decisions involving fabricated AI citations.

    That framing matters because it moves the issue out of novelty territory.

    A lawyer who files a brief with fake cases is not just making a technology mistake. The conduct potentially implicates duties of competence and candor. The tool may explain how the error entered the draft. It does not excuse the filing.

    The order also rejects a common mitigation argument: that some real authority existed elsewhere in the brief. A hallucinated citation, the court says, is worse than no citation. It wastes court resources, misdirects the court, deprives the client of credible advocacy, and undermines the adversarial process.

    The Firm-Supervision Point

    One of the most important parts of the order is its treatment of the law firm response.

    The firm tried to separate itself from the attorney who used the AI search tool. The court was not satisfied with that posture. It emphasized that every firm attorney whose name appeared on the brief bore some responsibility, and it faulted the absence of detail about how the firm supervised or reviewed the work.

    That is the operational lesson for law firms.

    A policy against AI drafting is not enough if the firm cannot show how the policy is communicated, enforced, and built into filing review. Nor is annual training enough if no one can explain who checked the authorities before the brief went out.

    The concurrence is especially useful on this point. Senior Judge Glickman did not say every lawyer listed on a complex brief must personally check every citation. He recognized that citation verification can be a group effort. But he also pointed toward concrete controls: training and retraining lawyers, adopting clear AI-use policies, requiring lawyers to confirm compliance, and using trained paralegals or other review processes to check citations and case descriptions before filing.

    That is a more realistic governance model than either banning AI in theory or requiring every senior lawyer to redo every cite check personally.

    The Sanctions Gap

    The unusual part of Douglas is not just the fake citations. It is the court's discussion of remedy.

    The panel struck the brief under D.C. Appellate Rule 28 and referred the matter to disciplinary counsel. But it also referred the sanctions-authority question to the court's Rules Committee for analysis and possible clarification.

    Judge Glickman's concurrence explains why.

    Federal courts have used several tools in AI citation cases, including Rule 11, appellate disciplinary rules, inherent authority, fee shifting, monetary sanctions, bar referrals, and suspension. The D.C. Court of Appeals does not have exactly the same rule structure. The concurrence says D.C. Appellate Rule 38 is aimed at frivolous appeals, petitions, or motions, not ordinary briefs containing some fake citations. D.C. Appellate Rule 46 addresses admission to the bar, not attorney discipline for conduct unbecoming a member of the bar. Inherent-authority sanctions require bad faith, and the existing record did not establish that Hall or the firm acted intentionally, knowingly, recklessly, or with bad faith rather than negligently or incompetently.

    That left the court with what the concurrence called a comparatively weak response: striking the brief, which can penalize the client for counsel's misconduct, plus public admonishment and disciplinary referral.

    That institutional problem is important. AI citation failures are becoming common enough that appellate courts may need remedial tools calibrated to lawyer conduct rather than only party consequences.

    Why This Is Different From The Usual Hallucination Story

    There have already been many AI citation cases. Clearon has covered several of them.

    Douglas adds three useful points.

    First, it is a published order from D.C.'s highest local court. That gives the decision weight in a jurisdiction with its own appellate rules and professional-responsibility system.

    Second, the court expressly says ignorance of generative AI citation risk is no longer credible. That is a clean marker for law firms that still treat AI training as optional background rather than core competence.

    Third, the concurrence shifts the discussion from punishment after failure to governance before filing. The point is not merely "check your citations." It is build a review process that can catch both fabricated authorities and subtler AI-generated inaccuracies.

    That last point matters because fake case names are not the hardest problem. They are often the easiest to find. The concurrence warns that AI inaccuracies may be more dangerous because they can cite real authorities for propositions those authorities do not support, confuse party arguments with holdings, or mishandle the hierarchy of authority.

    For legal teams, that means a citation-validation process should not stop at existence checks. Someone still has to read the source and confirm that the quoted language, holding, proposition, jurisdiction, and procedural posture are right.

    What Legal Teams Should Do Now

    The practical controls are not exotic.

    Law firms and legal departments should require every filing workflow to answer five questions before submission:

    • Who used AI, if anyone, and for what task?
    • Who verified that every cited authority exists?
    • Who checked that each authority supports the proposition for which it is cited?
    • Who reviewed quotations, parentheticals, procedural descriptions, and record references?
    • Who owns escalation if a court or opposing party flags a possible hallucination or unsupported citation?

    Those questions should be answered in the workflow, not after a show-cause order.

    AI policies also need to distinguish between search, drafting, summarization, cite checking, and final advocacy. The risks are different. A lawyer using an AI search feature to find authority still must verify the source. A lawyer using AI to draft arguments raises a deeper problem because the lawyer may outsource the judgment that advocacy requires.

    That is why the safest firm policy is not a slogan about whether AI is allowed. It is a documented review path for each use case, backed by supervision, training, file-level certification, and a plan for candor if something goes wrong.

    Bottom Line

    Douglas is not a ruling that lawyers may never use AI.

    It is a warning that AI use has become ordinary enough that courts now expect ordinary competence around it.

    The D.C. Court of Appeals struck Deutsche Bank's brief because fake citations reached the appellate record. It referred the matter for possible discipline. And it flagged that its own rules may need a better sanctions mechanism for AI-fabricated citation cases.

    For law firms, the takeaway is simple: AI citation risk is no longer a training footnote. It is part of appellate quality control, supervision, professional responsibility, and client protection.

    Sources and Related Clearon Coverage

  • Seattle Times and Newsday Add Trademark Dilution to the OpenAI Publisher Fight

    Seattle Times and Newsday Add Trademark Dilution to the OpenAI Publisher Fight

    Seattle Times and Newsday Add Trademark Dilution to the OpenAI Publisher Fight

    The newest newspaper suit against OpenAI and Microsoft is not just another training-data complaint.

    The Seattle Times Company and Newsday LLC filed a seven-count complaint in the Southern District of New York on September 4, 2026. The case accuses OpenAI entities and Microsoft of using the publishers' journalism without permission in generative AI systems, including ChatGPT, Copilot, and Bing Chat.

    That part fits the broader publisher-litigation pattern.

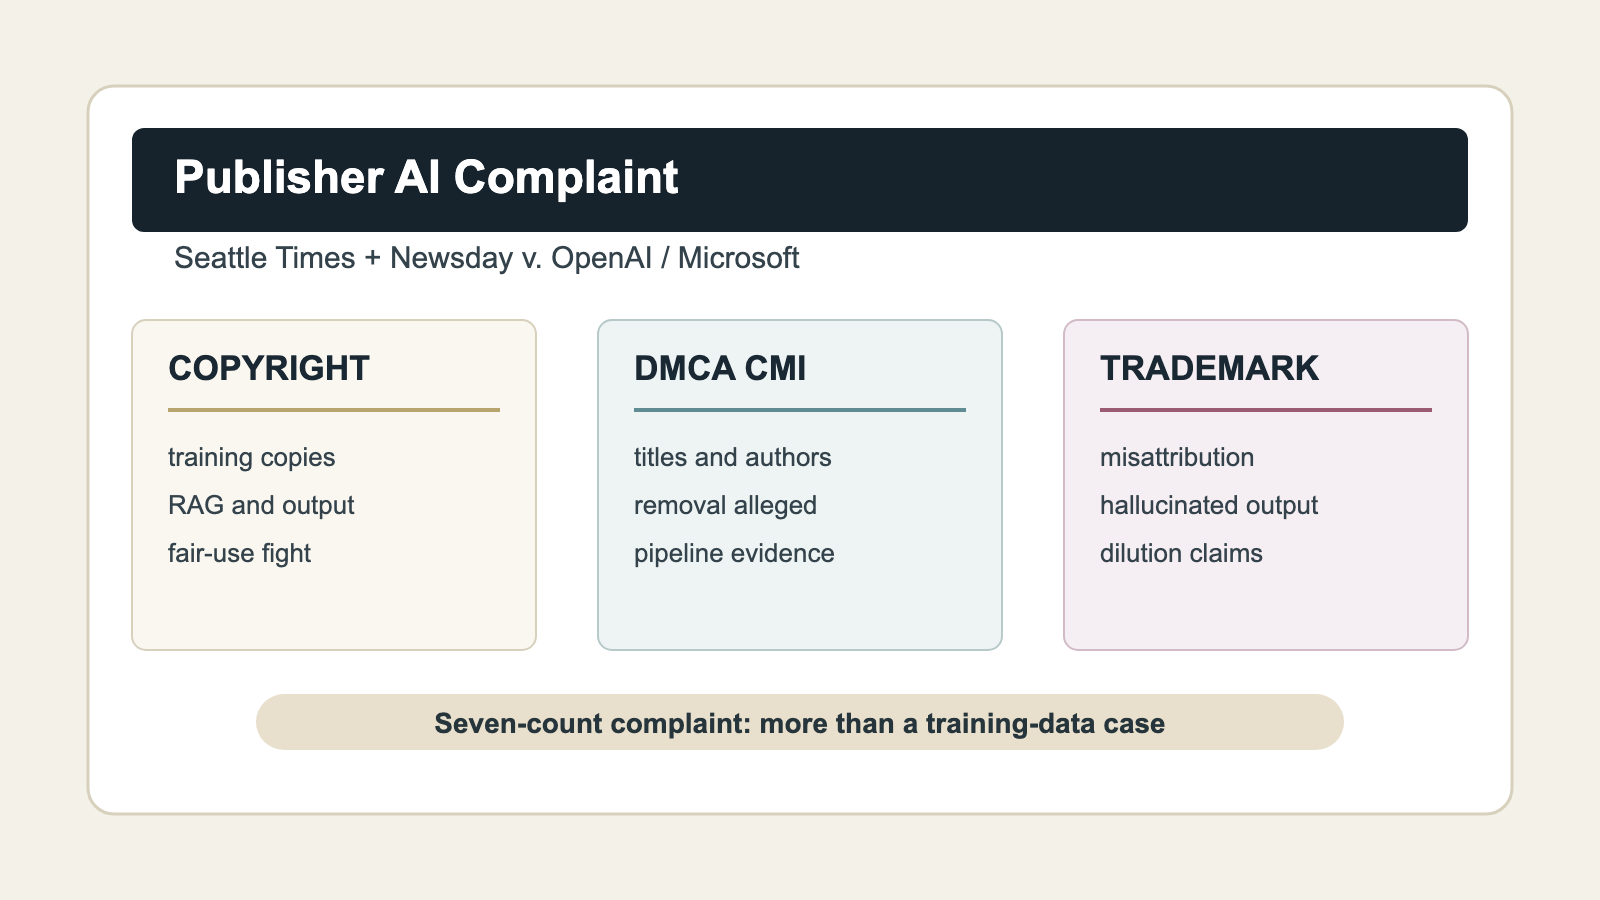
    The more interesting feature is the claim mix. The complaint pleads copyright infringement, vicarious copyright infringement, two DMCA copyright-management-information counts, and three trademark-dilution counts. In other words, the case is not framed only around whether model training is fair use. It also tries to make allegedly hallucinated or misattributed AI output a brand-injury problem.

    For companies building or deploying AI answer products, that is the part worth watching.

    What The Complaint Alleges

    The complaint says OpenAI and Microsoft copied large quantities of Seattle Times and Newsday journalism without permission or compensation. The publishers allege the defendants obtained articles by scraping their websites, bypassing paywalls, using datasets derived from WebText, WebText2, Common Crawl, and Microsoft's Bing search index, and then using that material to train, fine-tune, ground, and operate large language models.

    Those are allegations, not findings. OpenAI and Microsoft have not lost this case. No court has ruled that the complaint's factual claims are true.

    But the pleading is concrete enough to matter. It identifies The Seattle Times and Newsday as regional publishers with long-running copyright-registration programs, registered marks, paywalled websites, and active claims that AI systems can reproduce or closely paraphrase their journalism.

    The complaint also alleges output examples. It says ChatGPT reproduced an 88-word passage from The Seattle Times' Pulitzer-winning Boeing 737 MAX coverage after being prompted with the headline and URL. It also includes Newsday examples where model output allegedly tracked or reproduced article text.

    That is the copyright side of the case. The complaint's broader move is to connect those alleged outputs to two other theories: DMCA removal or distribution of copyright management information and dilution of the newspapers' marks.

    The Seven Counts

    The complaint pleads seven counts.

    Count I is direct copyright infringement under 17 U.S.C. section 501. The publishers allege that copies of their works were reproduced, stored, processed, used in training datasets, used for training, fine-tuning, and grounding, and disseminated through generative output containing copies or derivatives.

    Count II pleads vicarious copyright infringement against Microsoft and several OpenAI-related entities. The theory is that Microsoft and parent or affiliated OpenAI entities allegedly had the right and ability to control the infrastructure and conduct that produced the copying, while also profiting from it.

    Counts III and IV are DMCA claims under 17 U.S.C. section 1202(b). Count III alleges removal of copyright management information such as author names, titles, copyright notices, and terms-of-use information. Count IV alleges distribution of works or output knowing that copyright management information had been removed.

    Counts V, VI, and VII are trademark dilution. Count V is a federal Lanham Act dilution claim. Count VI is a Washington dilution claim for The Seattle Times. Count VII is a New York dilution claim for Newsday.

    That structure matters because it pushes the case beyond the now-familiar training-copying fight.

    Why The Trademark Counts Are The Signal

    Most AI publisher cases are described as copyright cases, and many of them are. This complaint is broader.

    The trademark-dilution counts rest on a different harm theory. The publishers allege that OpenAI and Microsoft products reproduce, output, and associate THE SEATTLE TIMES and NEWSDAY marks with AI-generated material that the publishers did not create, review, or publish. The complaint characterizes this as both blurring and tarnishment.

    That is a useful distinction for AI companies.

    Copyright law asks whether protected expression was copied, whether a use is infringing, whether fair use applies, and what remedies follow. Trademark dilution asks whether a famous or distinctive mark is being impaired or tarnished by association with someone else's product or output.

    The complaint's theory is that hallucinated or misattributed AI answers can do more than copy text. They can attach a publisher's name to inaccurate, fabricated, or substandard content and thereby weaken the source-identifying value of the mark.

    That theory will have hurdles. Trademark dilution is not a shortcut around copyright doctrine, and the plaintiffs still have to prove the elements of each claim. But the pleading is a reminder that output governance is not only about avoiding verbatim reproduction. It is also about attribution, brand association, source labeling, and whether users may believe a reputable publisher stands behind text it never reviewed.

    The DMCA Counts Also Matter

    The DMCA counts are quieter but potentially important.

    The publishers allege that their articles carried copyright management information, including copyright notices, author and title information, and terms-of-use information. They then allege that OpenAI and Microsoft removed that information while building datasets, training and operating models, and generating output containing copies or derivatives.

    The second DMCA count alleges distribution of works or generated output with that information removed.

    Those claims can matter even where the core copyright issue is contested. A defendant might argue about fair use for training, while still facing separate questions about whether copyright-management information was stripped or omitted in a way section 1202 forbids.

    That does not mean the DMCA claims will succeed. Courts have not treated every metadata or attribution omission as a section 1202 violation. The point is narrower: the complaint asks the court to look at the data pipeline and output pipeline, not just the final model-training question.

    For AI governance teams, that makes provenance and attribution controls more than a content-policy nicety. They can become litigation facts.

    The Requested Remedy Is Aggressive

    The prayer for relief asks for damages, profits, injunctions, and attorney fees. It also asks the court to order impoundment or destruction, under 17 U.S.C. section 503, of copies of the publishers' works and all LLMs and training datasets incorporating those works or derivatives.

    That remedy request will draw attention, but it should be read carefully.

    A complaint can ask for broad relief at the start of a case. That does not mean the court will grant it. It does not mean a court has found that any model must be destroyed. And it does not mean the defendants lack defenses.

    Still, the request shows how plaintiffs are framing leverage. They are not asking only for a license fee after the fact. They are asking the court to treat the alleged copying as embedded in datasets, model systems, and commercial products.

    That framing is why these cases matter beyond one pair of newspapers.

    How This Fits With The Existing OpenAI Copyright Fight

    The timing is notable. The Seattle Times and Newsday complaint was filed the same day summary-judgment motions were due in the consolidated OpenAI copyright litigation before Judge Sidney H. Stein.

    Clearon has already covered that public-access calendar. The merits briefing in the consolidated case is expected to become visible in stages, with opening summary-judgment briefs and Rule 56.1 statements due for public refiling on September 17 to the extent no party or third party seeks sealing.

    That means this new complaint lands while the broader OpenAI copyright fight is moving into a decisive merits phase.

    The new case is separate at filing. The complaint's docket is No. 1:26-cv-07644. But it was filed in the same district, against OpenAI and Microsoft, and it overlaps with the same broad questions about publisher content, training data, retrieval, output substitution, and fair use.

    The practical point is that companies should not treat the OpenAI litigation map as one monolithic case. Different plaintiffs are testing different combinations of claims. This one adds a strong masthead and attribution angle.

    What Not To Overstate

    There are four easy mistakes to avoid.

    First, this is a complaint, not a ruling. The allegations are unproven.

    Second, the trademark counts do not automatically solve the copyright case. They add a separate theory tied to brand dilution, hallucinated attribution, and association with AI-generated output.

    Third, the remedy request for destruction of models and datasets is a demand, not an order. It is important because of what it signals, but it is not an operative court command.

    Fourth, the case does not answer the fair-use question pending in the broader OpenAI litigation. The defendants can still argue that training-stage copying is lawful, that output examples are not legally sufficient, that DMCA elements are not met, or that trademark dilution is not available on these facts.

    The safer reading is that the case expands the pressure points.

    What To Watch Next

    The first thing to watch is whether the case is related, coordinated, or otherwise drawn into the orbit of the existing OpenAI copyright proceedings in the Southern District of New York.

    The second is how OpenAI and Microsoft respond to the trademark-dilution counts. If they move to dismiss, the court may have to decide how far publisher-brand theories can go when the alleged harm comes from AI output rather than traditional source confusion.

    The third is whether the DMCA counts survive early motion practice. Section 1202 claims often turn on knowledge, causation, and whether removed information plausibly enabled or concealed infringement.

    The fourth is how the complaint's output examples hold up. The more specific and reproducible the examples are, the more pressure they may put on controls around memorization, retrieval, attribution, and paywalled content.

    For AI companies, this is the operational lesson: copyright-risk controls and brand-risk controls cannot be separated cleanly. Training data, retrieval stores, output filters, attribution rules, and refusal behavior all create the factual record future plaintiffs will use.

    Bottom Line

    The Seattle Times and Newsday case is not just another publisher complaint against OpenAI and Microsoft.

    It is a seven-count pleading that combines copyright, vicarious liability, DMCA CMI, and trademark-dilution theories. The copyright claims will get the headline, but the trademark counts may be the more useful governance signal.

    If a model generates text that users associate with a real publisher, the risk is no longer only whether protected expression was copied. It may also be whether the output misuses the publisher's name, weakens its brand, or attaches that mark to content the publisher did not make.

    That is why this case belongs on the AI litigation watchlist. It shows how the publisher fight is evolving from training-data law into a broader dispute over output, attribution, brand integrity, and the economics of answer engines.

    Sources and Related Clearon Coverage

  • Minnesota’s Nudification Law Survives xAI’s Preliminary-Injunction Bid

    Minnesota’s Nudification Law Survives xAI’s Preliminary-Injunction Bid

    Minnesota's Nudification Law Survives xAI's Preliminary-Injunction Bid

    Minnesota's AI nudification law remains in force after xAI lost its request for a preliminary injunction.

    That is the immediate result of a September 4 order from Judge Donovan W. Frank in the District of Minnesota. The court denied xAI's bid to block enforcement of Minnesota Statutes section 325E.91 while the case proceeds. xAI filed a notice of appeal to the Eighth Circuit the same day.

    The ruling matters because it is a live federal test of a state law aimed directly at covered nudification tools. But it should not be overstated. The court did not finally decide whether Minnesota's law is constitutional. It denied interim relief because xAI waited too long to seek emergency relief and did not make a sufficient showing of irreparable harm. The court also found that the balance of harms and public interest independently favored Minnesota.

    For AI companies, the practical message is narrower and more immediate: constitutional objections may remain available, but they may not keep a state AI safety law offline during litigation.

    What Changed Since The First Clearon Article

    Clearon previously covered Minnesota's Chapter 72 after the court denied xAI's temporary restraining order before the law's August 1 effective date.

    The new development is different. The court has now ruled on the preliminary-injunction request after briefing and argument. It again left the law in place, but this time in a longer memorandum opinion that addresses the injunction factors and the state's evidentiary showing.

    The docket also moved quickly after the ruling. On September 4, xAI filed a notice of appeal from the order denying a preliminary injunction.

    So the case is no longer just an emergency timing fight. It is now an active appellate test over whether Minnesota's tool-level approach can remain enforceable while the constitutional challenge continues.

    What Minnesota's Law Does

    Minnesota's Chapter 72 created section 325E.91, titled "Prohibition on Nudification Technology."

    The statute prohibits a person who owns or controls a website, application, software, program, or other service from allowing a user to access, download, or use the service to nudify an image or video. It also prohibits nudifying an image or video on behalf of a user and bars advertising or promoting a service that performs those actions.

    The law defines "nudify" as altering or generating an image or video to depict an intimate part not shown in the original unaltered image or video of an identifiable individual, where the result is realistic enough that a reasonable person would believe the intimate part belongs to that individual.

    There is an exemption when the service requires the user's technical skill to nudify an image or video. The statute also says it does not alter or amend Section 230 protections and must be construed consistently with federal law.

    The enforcement risk is substantial. The Minnesota Attorney General may enforce the law and seek civil penalties of up to $500,000 for each unlawful access, download, or use. A depicted individual may also bring a civil action for damages, punitive damages, injunctive relief, attorney fees, costs, and other equitable relief.

    The law took effect August 1, 2026.

    Why The Court Denied Interim Relief

    The court's preliminary-injunction ruling rests on two main grounds: delay and irreparable harm, plus the balance of harms and public interest.

    The delay point is direct. H.F. 1606 was signed on May 7. xAI filed its lawsuit and emergency motion near the end of July, roughly three months later and only days before the law took effect. Judge Frank wrote that xAI is a sophisticated and well-resourced litigant and that, if it genuinely feared irreparable harm, it would have acted more quickly.

    That timing problem mattered both at the temporary-restraining-order stage and at the preliminary-injunction stage.

    The court also rejected xAI's irreparable-harm showing. xAI pointed to the risk of large civil penalties, commercial injury, engineering work to implement Minnesota-specific controls, increased moderation, potential user loss, and alleged First Amendment injury.

    The court found those showings insufficient for interim relief. It treated the civil penalties as monetary in nature. It noted that xAI had already disabled its nudification tool in Minnesota, making penalties unlikely on the record before the court. It also described xAI's evidence of engineering cost, moderation burden, and user loss as vague, conclusory, or speculative.

    On the First Amendment point, the court did not say First Amendment harm can never be irreparable. It said that even in First Amendment cases, a movant must make a clear showing of likely irreparable harm, and delay can independently support denial of a preliminary injunction.

    The Merits Are Still Open

    The court did not resolve xAI's First Amendment challenge.

    That distinction is important. The order says the parties "sharply contest" the strength of xAI's First Amendment claim. xAI argues it is likely to succeed. Minnesota disputes xAI's standing to assert its users' First Amendment rights, disputes xAI's own asserted First Amendment interest, and argues the statute is valid under any level of scrutiny.

    Judge Frank called the constitutional issues complex, especially in the context of new technology and public risk. The court said those issues deserve full consideration and may be addressed in the future through the state's motion to dismiss or later permanent-injunction proceedings.

    So this is not a final ruling that Minnesota's statute survives First Amendment review. It is a ruling that xAI did not justify blocking the law now.

    That posture should shape how companies read the decision. The order is strongest as a lesson about emergency relief, evidentiary showings, and litigation timing. It is not yet a definitive answer on how far states may go in regulating generative image tools.

    The Public-Interest Record Helped Minnesota

    The court also found that the balance of harms and public interest tipped "steeply" in Minnesota's favor.

    The order points to the legislative record around harms from AI nudification technology. It describes testimony about missed work, fear, family harm, and the emotional burden of realistic sexualized images and videos. It also cites evidence about widespread use of nudification apps, synthetic sexual images of adults and children, school-related harms, and reports involving AI-generated child sexual abuse material.

    That record mattered because Minnesota framed the law as a response to a specific product-safety and victim-protection problem. The court accepted, for purposes of the preliminary-injunction balance, that the state has an interest in curbing the generation and proliferation of those images.

    xAI's harm showing did not outweigh that public-interest evidence at the interim stage.

    For future challenges to AI laws, that is a useful signal. Courts may look closely at whether the state built a factual record explaining the harm and whether the challenger can identify concrete, imminent harm from enforcement. Abstract concern about overbreadth may not be enough to suspend a statute while the merits are still pending.

    What The Appeal Means

    xAI's same-day notice of appeal keeps the fight alive.

    The appeal does not automatically mean Minnesota's law is invalid, and it does not by itself suspend enforcement. Unless a court grants stay relief or reverses the district court's preliminary-injunction ruling, section 325E.91 remains in effect while the litigation continues.

    The appeal also means the Eighth Circuit may soon have to address how emergency-relief principles apply to state AI laws that regulate expressive tools, user misuse, product controls, and synthetic sexual imagery.

    That is a narrower appellate question than the ultimate merits question. An appellate court reviewing a preliminary-injunction denial can focus on delay, irreparable harm, balance of equities, public interest, and likelihood of success without finally deciding every constitutional issue.

    Even so, the appeal will be watched closely because the underlying statute is unusual. Minnesota did not merely create a takedown system after abusive content is posted. It restricted covered access to nudification functionality itself.

    What AI Companies Should Do Now

    Companies offering image generation, image editing, avatar tools, video generation, or transformation features should treat this as a live compliance development.

    The first question is not whether Minnesota will ultimately win. The first question is whether the company can explain, today, whether its product lets users generate realistic altered depictions of intimate parts of identifiable people and what controls prevent that result.

    Product, legal, and trust-and-safety teams should be able to answer:

    • whether the system can create the category of output Minnesota defines as "nudified";
    • whether controls operate before generation, before export, before sharing, or only after abuse reports;
    • whether geographic controls have been implemented for Minnesota users;
    • whether logs can show what controls were active at the relevant time;
    • whether policy enforcement is enough under a statute aimed at service access rather than only user misconduct;
    • whether any relied-on "technical skill" argument is actually supported by product design; and
    • how the company would respond if another state copied Minnesota's access-level model.

    This is especially important because the district court considered xAI's already-implemented Minnesota controls when weighing harm. A company that waits until enforcement is imminent may have a harder time arguing that compliance work, moderation burden, or lost users justify emergency court relief.

    What Not To Overread

    There are three limits to keep in view.

    First, the order does not decide whether Minnesota's law is constitutional.

    Second, the order does not say every state law aimed at AI image tools will survive. It is tied to this statute, this record, xAI's timing, and xAI's evidence of harm.

    Third, the order does not erase federal-law questions. Minnesota's statute expressly says it does not alter Section 230 protections and must be construed consistently with federal law. How that clause works in practice may matter later.

    The safer reading is practical: Minnesota's law stays active for now, and challengers to similar AI laws will need a stronger emergency-relief record if they want to stop enforcement before the merits are decided.

    Bottom Line

    Minnesota has won the first full preliminary-injunction round in the xAI challenge to its nudification law.

    That does not settle the First Amendment merits. But it does leave Minnesota's tool-level nudification statute in effect while xAI appeals.

    For AI companies, the compliance takeaway is immediate. If a state law regulates access to a covered image-generation or editing function, waiting until the eve of enforcement to challenge it can weaken the emergency-relief case. And if a company has already built state-specific controls, it should preserve the evidence showing what changed, when it changed, and why.

    The next phase will likely unfold in the Eighth Circuit. Until then, Minnesota's law remains a live example of how states may try to regulate AI-enabled synthetic intimate imagery upstream, at the product-access layer.

    Sources and Related Clearon Coverage

  • OpenAI’s Copyright Summary-Judgment Fight Now Has a Public-Access Calendar

    OpenAI’s Copyright Summary-Judgment Fight Now Has a Public-Access Calendar

    OpenAI's Copyright Summary-Judgment Fight Now Has a Public-Access Calendar

    The next major filings in the consolidated OpenAI copyright litigation will not become fully visible all at once.

    That is the point of a September 3 stipulated sealing order entered by Judge Sidney H. Stein in the Southern District of New York. The order does not decide the merits of the copyright claims. It does not finally determine which material will remain sealed. And it should not be read as a finding that OpenAI, Microsoft, publishers, authors, or other parties are entitled to keep the summary-judgment record from public view.

    It does something narrower but still important: it sets a two-track calendar. Daubert briefing and summary-judgment exhibits can move through provisional sealing and later omnibus sealing motions. Summary-judgment briefs and Rule 56.1 statements follow a separate public-refiling process with earlier dates.

    For companies and publishers watching the case, the dates now matter almost as much as the arguments.

    What The Order Actually Does

    The order is a stipulated omnibus sealing order for summary-judgment and Daubert briefing in In re OpenAI, Inc. Copyright Infringement Litigation, No. 1:25-md-3143-SHS-OTW. It applies to all cases in the consolidated proceeding.

    The parties told the court that the coming briefing is expected to refer to or attach material designated as Protected Discovery Material under the protective order. They asked to handle many sealing issues through later omnibus motions after briefing, rather than through separate sealing motions at the moment every brief or exhibit is filed.

    Judge Stein approved that structure.

    The practical result is a two-track public-access schedule. Exhibits, expert reports, declarations, and Daubert materials may be provisionally sealed if they contain or refer to protected discovery material. Summary-judgment briefs and Rule 56.1 statements are treated separately, with earlier public-refiling dates and party-by-party sealing procedures.

    That distinction matters because the briefs are where the parties' legal theories should become visible first. The evidentiary record may take longer.

    The Key Summary-Judgment Dates

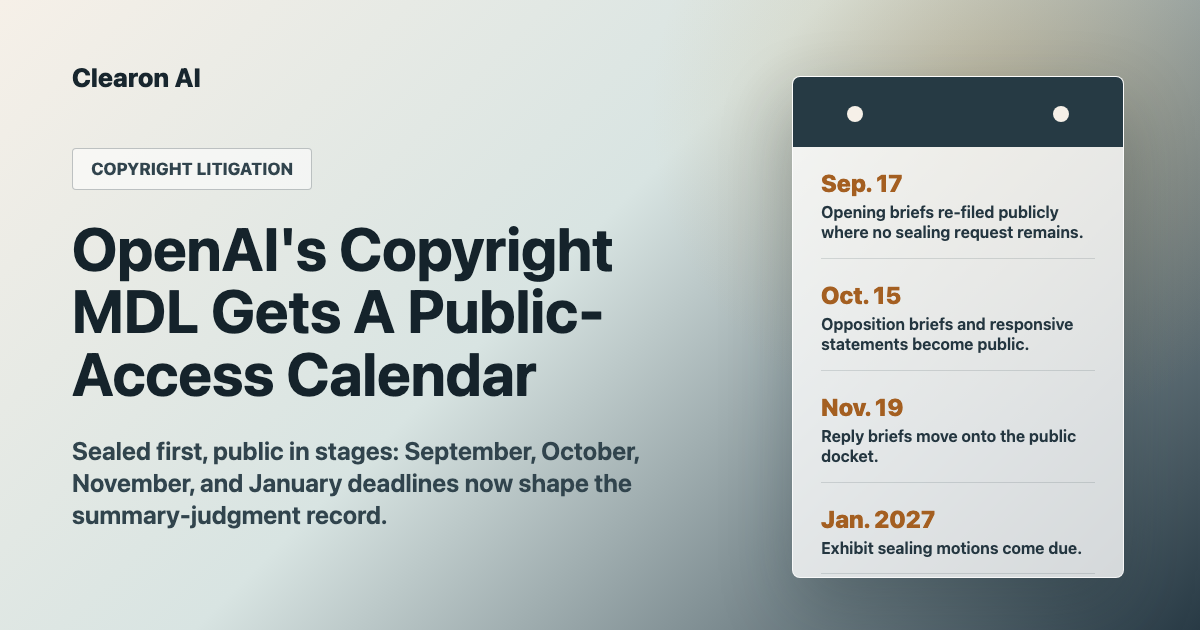
    The court has already set the summary-judgment schedule: motions by September 4, 2026, oppositions by October 9, 2026, and replies by November 6, 2026.

    The sealing order adds the public-access timing around those filings.

    For opening summary-judgment briefs and Rule 56.1 statements, a moving party must file any motion to seal its own protected material by September 4. Other parties and third parties have until September 14 to support requests to maintain under seal portions of another party's brief or Rule 56.1 statement. By September 17, the parties must publicly re-file their summary-judgment briefs and Rule 56.1 statements, leaving unredacted the portions that no party or third party has sought to seal.

    The same pattern repeats for oppositions. Opposition briefs and responsive Rule 56.1 statements are due October 9. Supporting statements for another party's proposed sealing are due October 14. Public refiling is due October 15 at 5:00 p.m. ET.

    For reply briefs, sealing motions are due November 6. Supporting statements for another party's proposed sealing are due November 16. Public refiling is due November 19.

    Those dates are now the public-access map for the merits phase of the case.

    The Exhibits Move On A Slower Calendar

    The order gives exhibits and expert materials a different timeline.

    For Daubert briefing and summary-judgment exhibits, including expert reports and declarations, the parties may provisionally seal materials that contain or refer to Protected Discovery Material. The parties and affected third parties are relieved from the usual contemporaneous sealing-motion and short justification requirements for those provisionally sealed materials.

    But the relief is temporary.

    Anyone who wants provisionally sealed material to remain sealed must file an omnibus sealing motion by January 13, 2027. Responses are due January 20. Any provisionally sealed material that no party or third party moves to seal by January 13 must be publicly filed by January 27.

    That is important for two reasons.

    First, the January schedule means the public may see the legal briefs before it sees the full evidentiary fight. Second, it means the current order is not a final secrecy ruling. It is a staging order. It defers the sealing fight for many exhibits, but it also creates a deadline for that fight.

    Why This Matters Beyond Procedure

    OpenAI's copyright cases have already become one of the central legal battlegrounds over generative AI training, publisher substitution, retrieval systems, outputs, and licensing leverage.

    The summary-judgment phase is where those arguments may become more concrete.

    The court may be asked to decide, or at least frame, questions about training-stage fair use, market substitution, acquisition practices, output behavior, protected expression, and the weight of expert evidence. Those are not abstract issues for AI companies or rightsholders. They go directly to how AI developers build datasets, evaluate licensing exposure, structure retrieval and output controls, and explain risk to boards, customers, investors, and regulators.

    That is why the sealing calendar deserves attention. Until the public filings appear, outside observers should be careful about any claim that one side's summary-judgment arguments have already won, collapsed, or shifted the law. The briefs may be filed under seal first. The public versions will arrive later, subject to redactions tied to pending sealing requests.

    The safer takeaway is procedural: the merits fight is moving into summary judgment, and the public record is scheduled to emerge in stages, subject to later sealing decisions.

    What Not To Overstate

    There are three easy mistakes to avoid.

    First, this is not a ruling on fair use. It does not decide whether OpenAI's training uses are lawful, whether particular outputs infringe, whether acquisition conduct matters separately, or whether publishers and authors can prove market harm.

    Second, this is not a permanent sealing decision. The order permits provisional sealing and sets deadlines for later sealing motions. It also says nothing prevents a party from challenging another party's or third party's request to maintain material under seal.

    Third, the order does not mean the public will have no meaningful access to the arguments. The opposite is closer to the point. It identifies specific dates when public refiling must occur for the summary-judgment briefs and Rule 56.1 statements, with unredacted material where no sealing request has been made.

    In other words: the order creates a staged process for handling protected discovery material in a sprawling litigation record.

    What To Watch Next

    The first date to watch is September 17, when public versions of the opening summary-judgment briefs and Rule 56.1 statements are due. That is likely to be the first meaningful public window into the parties' merits arguments at this stage, subject to requested redactions.

    The second date is October 15 at 5:00 p.m. ET, when public opposition briefs and responsive Rule 56.1 statements are due.

    The third is November 19, when public reply briefs are due.

    The fourth is January 13, 2027, when any party or third party seeking to keep provisionally sealed exhibits and expert materials under seal must file an omnibus motion. January 27 is the follow-on public-filing deadline for provisionally sealed materials no one moved to seal.

    Those dates should guide how companies read the next wave of coverage. Early reports may be based on sealed docket entries, partial public material, party statements, or secondhand descriptions. The more reliable analysis will come after the public versions are filed and the court's sealing process narrows what remains subject to a sealing request.

    Bottom Line

    The September 3 order is not the copyright ruling everyone is waiting for.

    It is the calendar that tells us when that fight becomes visible.

    Opening summary-judgment arguments must be publicly re-filed by September 17 to the extent no party or third party has sought sealing. Opposition and reply briefs follow in October and November. Exhibits and expert materials may remain provisionally sealed longer, but the order sets January deadlines for formal sealing motions and public filing where no sealing request is made.

    For Clearon readers, that means the next phase of the OpenAI copyright litigation should be tracked by date and document type, not just headline. The legal arguments, factual record, and expert evidence will not surface together. They are scheduled to emerge in layers, subject to later sealing decisions, and each layer may matter for AI training, publisher licensing, output controls, and copyright-risk planning.

    Sources and Related Clearon Coverage

  • California’s AI Employment Bills Reach Enrolled Status With Human Review and Displacement Notice Rules

    California’s AI Employment Bills Reach Enrolled Status With Human Review and Displacement Notice Rules

    California now has two AI employment bills at enrolled status.

    That matters because the pair does not try to regulate workplace AI as one abstract category. It targets two concrete points where automation changes employment power: discipline or termination decisions, and workforce reductions caused by AI or other automated technology.

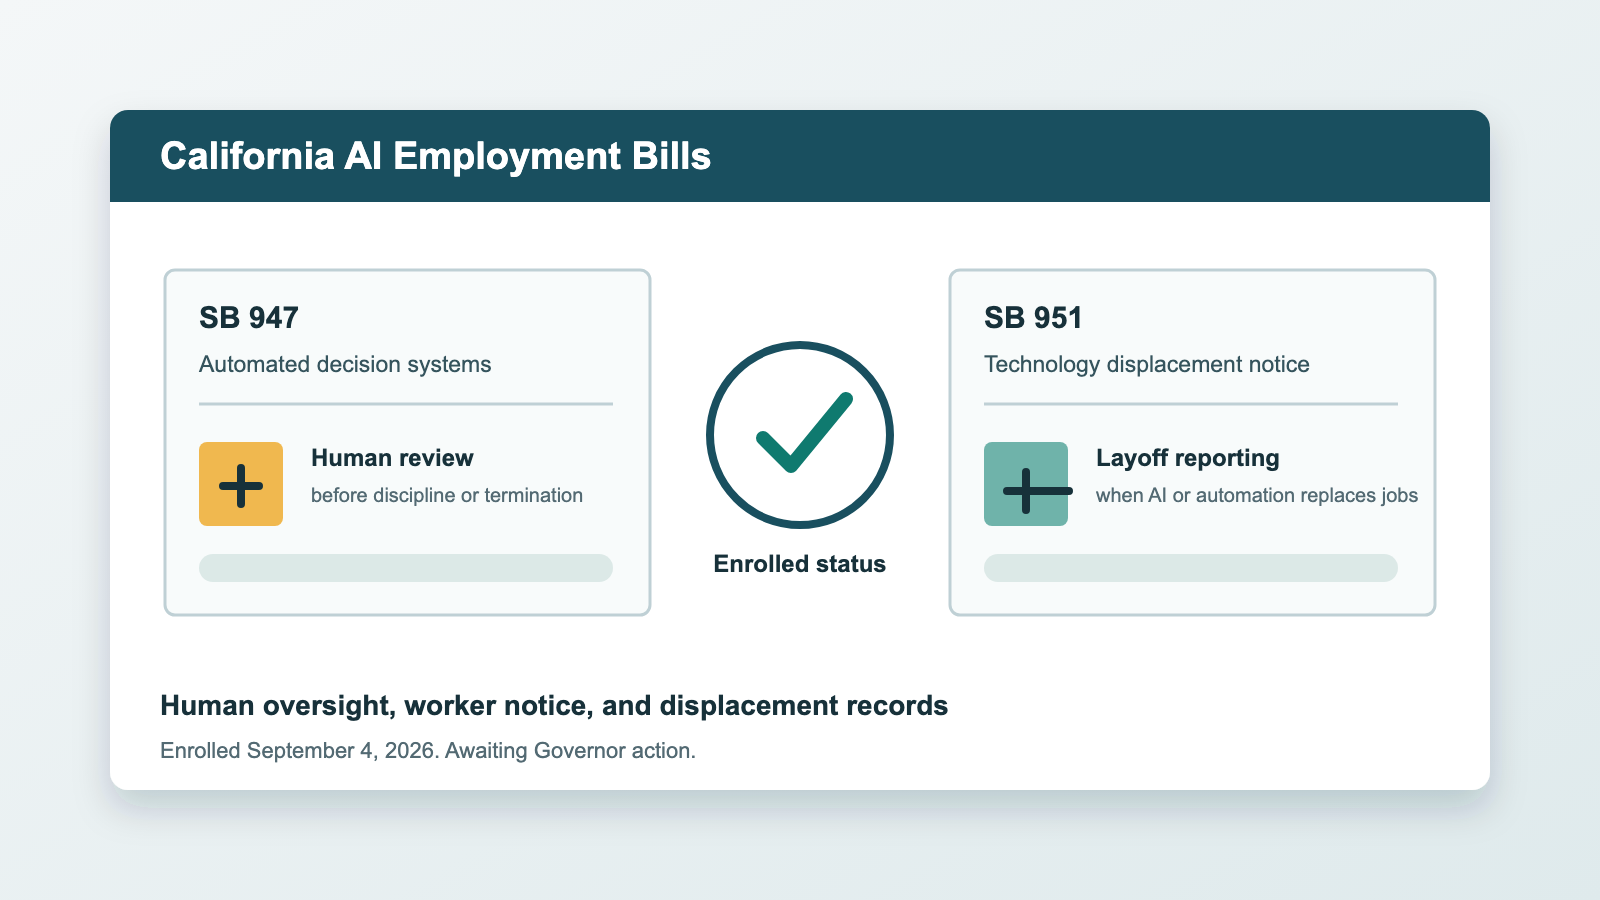
    SB 947 would bar employers from relying solely on automated decision systems to discipline or fire workers and would require human review when an employer primarily relies on automated decision system output. SB 951 would add AI-driven or automation-driven displacement information to California's mass-layoff notice framework when a covered Cal-WARN notice is already required.

    Both bills are still awaiting executive action. They are not enacted law yet. But the official California records show both measures enrolled on September 4, 2026, after final Senate concurrence votes on August 31. That makes this a live compliance-planning moment, not another introduced-bill story.

    For companies using workforce AI, the direction is clear enough already. California is moving from "should employers use AI carefully?" to "who reviews the automated output, what must the worker be told, and what public records will exist when automation displaces jobs?"

    What Changed This Week

    The official California bill records show SB 947 and SB 951 both reached enrolled status on September 4, 2026.

    SB 947, titled "Employment: automated decision systems," passed after Assembly amendments were concurred in by the Senate on August 31 by a 28-10 vote. The official Legislative Counsel's Digest says the bill would add a new Labor Code part beginning July 1, 2027.

    SB 951, titled "Employment: technological displacement: notice," also reached enrolled status on September 4 after Senate concurrence in Assembly amendments on August 31, by a 29-10 vote.

    Those statuses matter because the legislative question has narrowed. The bills are no longer merely concepts being debated in committee. They are passed measures awaiting executive action.

    That does not make them binding yet. It does make them serious enough that companies should begin mapping whether their workforce systems would fall within the rules if the bills are signed.

    SB 947 Is About AI in Discipline and Termination

    SB 947 is the more direct "robo boss" bill.

    The official digest says the bill would, beginning July 1, 2027, prohibit an employer from using an automated decision system to perform certain functions and limit the purposes for and way in which such a system may be used. It would also create employee rights around the data used by the system when the employer primarily uses an automated decision system to make a disciplinary or termination decision.

    The bill is more than a ban on a fully automated firing button. It is also a documentation and notice bill.

    When an employer primarily uses an automated decision system to make a disciplinary or termination decision, the bill would allow the affected employee to request a description of the employee's own data primarily used by the system. It would also require a written post-use notice when an employer primarily relied on an automated decision system to make the decision.

    The author's office frames the bill more plainly. Senator Jerry McNerney's announcement says SB 947 would bar employers from relying solely on automated decision systems to fire or discipline workers, require human oversight and verification when such systems assist those decisions, and require employers to inform workers if an automated decision system was used.

    The enforcement structure also matters. The official digest says the Labor Commissioner could enforce the bill and a public prosecutor could bring a civil enforcement action. The author's announcement says the bill does not provide a private right of action.

    For employers, that combination points to a regulatory file rather than just a lawsuit file. If the bill is signed, companies will need to show how the human review worked, what notice was given, what data description can be produced, and why the automated system was not treated as the final unreviewed decision maker.

    SB 951 Is About AI-Driven Job Displacement

    SB 951 addresses a different problem: not the individual disciplinary decision, but the larger workforce event.

    The official status page describes SB 951 as a bill on "Employment: technological displacement: notice." The bill text would amend California's mass-layoff notice framework so that, when an employer is already required to issue notice for a mass layoff, relocation, or termination, and that event is caused in whole or in substantial part by an AI system or other automated technology replacing or automating employment positions, the notice must include additional information.

    That information would include:

    • the number, classification or occupation, and work location of layoffs substantially due to replacement or automation by AI or other automated technology;
    • the job functions performed by the replaced workers that will be automated;
    • the specific category or type of AI system or other automating technology that substantially resulted in technological displacement; and
    • a statement at the top of the notice saying, "This notice is for a technology displacement."

    The bill would also require California's Employment Development Department, as part of regular Cal-WARN Act data reporting, to publish a summary of notices received under the new technological-displacement subdivision and post quarterly statewide summaries of reported technology displacements.

    That is a major practical point. SB 951 would add a public reporting trail about AI-related and automation-related displacement.

    For companies, that means the decision to attribute a layoff to AI or automation may become visible outside the company. For policymakers, researchers, unions, journalists, and competitors, the same notices could become a data source about where automation is actually replacing jobs.

    The Two Bills Should Be Read Together

    SB 947 and SB 951 are stronger together than either bill is alone.

    SB 947 focuses on decision quality and worker process when an automated decision system is used in discipline or termination. SB 951 focuses on transparency when technology changes the structure of the workforce.

    One is about the affected worker asking: was an automated system used against me, and what data did it rely on?

    The other is about the affected workforce, government, and public asking: are jobs being eliminated because AI or automation is replacing them, and where is that happening?

    That is the real story. California is moving beyond product-level workplace AI regulation and into the evidence trail around workplace AI.

    Employers will not be able to treat these questions as purely internal design choices if the bills are signed. The practical burden will sit in HR, legal, compliance, procurement, data governance, labor relations, and workforce planning.

    This Fits a Broader State Pattern

    California is not moving in isolation.

    Colorado's 2026 automated decision-making technology law, which replaces the state's earlier high-risk AI framework, also turns on notice, explanations, data correction, and meaningful human review. Illinois already regulates certain employment uses of artificial intelligence through amendments to the Illinois Human Rights Act. New York City has had its automated employment decision tool law in force for several years.

    The California bills would add a different kind of pressure.

    SB 947 would push into discipline and termination, beyond the hiring focus of many employment-AI laws. SB 951 would push into displacement reporting through Cal-WARN notices. Together, they would make employment AI governance a continuing operational requirement rather than a one-time vendor review.

    That matters because many organizations still treat AI employment risk as a hiring-screening issue. The newer pattern is broader. It covers who is evaluated, who is disciplined, who is terminated, who is replaced, and what records prove the company did not let automated systems quietly make the real decision.

    What Companies Should Do Before Signature

    Companies do not need to wait for final enactment to start the useful work.

    The first step is inventory. Employers should identify systems that rank, score, recommend, flag, classify, monitor, or otherwise influence discipline, performance management, termination, layoffs, redeployment, or workforce planning.

    The second step is role mapping. A tool that merely stores employee records is different from a tool that recommends termination, flags productivity concerns, scores performance, identifies positions for elimination, or produces a workforce-reduction plan.

    The third step is human-review design. If a system can affect discipline or termination, the company should be able to say who reviews the output, what information the reviewer sees, what discretion the reviewer has, and how the company records the human judgment.

    The fourth step is notice and data-description readiness. If a worker can ask for a meaningful, objective description of the employee's own data that the system primarily used, the company needs to know whether that description can be produced without exposing unrelated confidential or third-party information.

    The fifth step is displacement classification. If AI or automated technology contributes to layoffs or job eliminations, the company should decide how it will determine whether the technology caused the event "in whole or in substantial part." That phrase is likely to do a lot of work if SB 951 becomes law.

    What Not To Overstate

    There are three cautions.

    First, neither bill is enacted yet. The Governor can still sign, veto, or otherwise affect the final posture. The right status today is enrolled and awaiting executive action.

    Second, SB 947 should not be described as banning all AI use in employment decisions. The official materials point to limits, human oversight, worker notice, and data-description rights around covered uses, especially discipline and termination.

    Third, SB 951 is not a general anti-automation law. It is a notice and reporting bill tied to covered Cal-WARN mass-layoff and related events caused in whole or in substantial part by AI systems or other automated technology.

    Those limits make the bills more useful, not less. They show where the compliance work will actually sit.

    Bottom Line

    California's latest AI employment package is about control and records.

    SB 947 asks whether a human really reviewed the automated decision system output that helped discipline or fire a worker, and whether the worker gets notice and a meaningful description of the employee data primarily used around that use. SB 951 asks whether AI or automation materially contributed to displacement in a covered Cal-WARN event and whether that fact will be reported through the state's layoff-notice system.

    If both bills are signed, California will add another important layer to workplace AI governance: whether the company can show who relied on the tool, who reviewed its output, what the worker was told, and what the public record says when technology replaces jobs.

    That is a much harder problem than updating an AI policy. It is a workflow problem. Companies that use automated systems in employment decisions should treat it that way now.

    Sources and Related Clearon Coverage

  • Anthropic Wins A Permanent Injunction On The 3252 Track, But The FASCSA Fight Is Still Live

    Anthropic Wins A Permanent Injunction On The 3252 Track, But The FASCSA Fight Is Still Live

    Anthropic just turned its March preliminary-injunction win into a full merits victory in the Northern District of California.

    Judge Rita Lin permanently enjoined the participating government defendants from enforcing the challenged measures in Anthropic's Northern District of California case and vacated the specific designation and directive actions identified in the order. But the ruling resolves the 10 U.S.C. Section 3252 track, not the separate FASCSA track.

    Commentary often treats the Anthropic supply-chain-risk dispute as a single case. It is not. Anthropic has been fighting two different supply-chain-risk designations under two different statutes in two different courts. This ruling is a sweeping loss for the government on the California path. It is not, by itself, the end of the Washington path.

    What Judge Lin Just Did

    Judge Lin's August 27 opinion and final-relief order turn the preliminary-injunction win into a merits victory for Anthropic.

    First, the court held that the government's actions amounted to unlawful retaliation against Anthropic for protected speech. The final-relief order expressly declares that the challenged actions violate the First Amendment because they are "unlawful retaliation against Anthropic for constitutionally protected expressive activities." The opinion adds the broader warning: "The empty invocation of national security is not a blank check to punish and retaliate against government critics."

    Second, the court held that Anthropic was denied the process the Constitution required before being publicly branded and cut off in this way. That due-process theme had already appeared in the March preliminary-injunction ruling, and the final-relief order now carries it through expressly.

    Third, and most important for procurement lawyers, Judge Lin concluded that Anthropic does not meet the statutory definition of a supply chain risk on the record before the court. The opinion says that "[a]n IT vendor does not become a potential adversary of the United States whenever it asks probing questions or stubbornly insists on particular contracting terms, even if doing so causes DoW to doubt its trustworthiness." That is not just a procedural criticism. It goes to the substance of the government's theory under Section 3252.

    The government's position was never simply that it did not want to buy Claude. It was free to stop buying Claude. The much more aggressive move was using national-security-flavored supply-chain machinery to treat Anthropic as if it were the kind of sabotage or subversion threat the statute was built to address. Judge Lin rejected that move in direct terms.

    Why The 3252 Point Matters

    Section 3252 is not a generic "we do not trust this vendor" statute.

    Clearon's earlier Anthropic article walked through the preliminary-injunction ruling, where Judge Lin had already signaled deep skepticism that Anthropic's insistence on two usage red lines could turn it into a statutory supply-chain threat. The merits ruling confirms that conclusion. The opinion explains that Section 3252 was built to address "sabotage or subversion" by "foreign intelligence, terrorists, or other hostile elements," not a domestic vendor's public disagreement with the government's preferred AI-use terms.

    If a frontier-model vendor can be labeled a supply-chain risk whenever it publicly criticizes the government's preferred uses or refuses one set of contract terms, then "supply chain risk" stops meaning sabotage or subversion and starts meaning policy defiance. Judge Lin rejected that stretch directly.

    For AI companies, that is a meaningful line. It suggests that refusing to permit certain uses, even in a sensitive government setting, does not by itself permit the government to move from ordinary procurement discretion to a reputationally destructive national-security designation.

    This Does Not Resolve The FASCSA Case

    That does not mean Anthropic is fully out of danger.

    The California ruling concerns the Section 3252 path and the related Presidential and Hegseth directives challenged in the Northern District of California. The separate D.C. Circuit case concerns a different designation under 41 U.S.C. Section 4713, part of the Federal Acquisition Supply Chain Security Act, or FASCSA.

    Those two tracks overlap in business effect, but they are not interchangeable as law.

    Judge Lin's ruling does not automatically erase the FASCSA designation. The D.C. Circuit case is still pending. CourtListener's D.C. Circuit materials show that the court denied Anthropic's emergency stay request in April, heard oral argument on May 19, 2026, later consolidated No. 26-1162 with No. 26-1049 after Anthropic filed a protective petition following the Secretary's June 3 reaffirmation, and then received Anthropic's August 28 Rule 28(j) letter invoking Judge Lin's ruling along with the government's September 3 response. As of this check, there is still no merits disposition reflected in the materials I could verify during this run.

    The Ninth Circuit posture matters too. Judge Lin's opinion notes that the government's appeal from the March preliminary injunction was filed in the Ninth Circuit but then stayed at the parties' mutual request pending a ruling from the D.C. Circuit in the related case. So the California and Washington tracks are now intertwined not just strategically, but procedurally.

    If you are advising a company that sells into or around the defense market, the takeaway is not "Anthropic won everywhere." It is "Anthropic won decisively on one statutory path, while the other path remains live."

    Why The Two Cases Still Matter Together

    Even though the statutes differ, the proceedings remain connected in practice.

    The operational question is broader than either caption: how much freedom does the government have to punish or isolate an AI vendor that refuses certain military or surveillance uses?

    The California decision pushes hard in one direction. It says the government cannot take a contract dispute, wrap it in national-security rhetoric, and convert it into retaliation for protected speech under a statute that does not fit the facts.

    The D.C. Circuit case leaves more uncertainty in place. The stay denial did not resolve the merits, but it did allow the FASCSA designation to remain operative while the petition proceeds. Judge Lin's ruling may still matter there as persuasive authority, and Anthropic is already pressing it that way, but the government is disputing any claim that the California decision automatically carries issue-preclusive force into the Section 4713 proceeding because the statutes, actions, and processes differ. That means the practical consequences inside the defense ecosystem do not disappear just because California ruled for Anthropic.

    That split matters for AI vendors that want defense business without giving the government unlimited control over product use. They now have better authority against an overbroad Section 3252 theory, but they still do not have a final appellate answer on the FASCSA route.

    It also matters for government contractors, integrators, investors, and boards. They still need to ask which statute is doing the work, which forum controls, and what the live restrictions actually reach. Sloppy summaries could cause companies either to overcomply or to assume a designation vanished when it did not.

    What Happens Next For The Government

    The most obvious next step is to seek Ninth Circuit review of Judge Lin's merits ruling, along with a request for a stay pending appeal. Judge Lin already denied the government's request for a seven-day administrative stay, so any broader effort to narrow or pause the California relief now has to proceed through the ordinary appellate-stay path.

    It may also try to argue for a more limited reading of the injunction or for partial relief tied to specific agencies or directives. The final-relief order leaves room for lawful procurement choices: it says the order does not require DoW to use Anthropic and does not prevent the government from transitioning to other AI providers so long as those actions comply with applicable statutes, regulations, and constitutional limits. But the ruling still amounts to a broad rejection of the theory that national security language can substitute for statutory fit and constitutional limits.

    Meanwhile, the government can continue litigating the D.C. Circuit case. In business terms, that may now be the more important active front, because it preserves the possibility that one supply-chain-risk designation could survive even after the California path failed.

    That does not mean the D.C. Circuit must come out differently on the merits. It only means the government still has a live forum in which to defend the FASCSA designation under a different statute, a different review path, and a different procedural posture.

    What Companies Should Watch Now

    Three follow-up questions matter most:

    1. Does the government seek an immediate stay pending appeal in the Ninth Circuit, and if so, does it get one?
    2. Does the government continue to lean on the D.C. Circuit case as its remaining live path for keeping pressure on Anthropic?
    3. How do agencies and contractors interpret the gap between the two rulings in day-to-day procurement decisions while the D.C. case remains unresolved?

    Bottom Line

    Anthropic just won a major merits ruling, and the easiest thing to blur is also the most important: this is the Section 3252 decision, not the FASCSA decision.

    Judge Lin held that Anthropic does not meet the statutory definition of a supply chain risk, that the government's actions retaliated against protected speech, and that the company was denied due process. That is a serious defeat for the government's California strategy and an important signal to other AI vendors that procurement pressure does not automatically become lawful once officials invoke national security.

    One more precision point matters. Anthropic did not win literally everything. Judge Lin rejected Anthropic's ultra vires claim, and the final-relief order also gives the government judgment as to certain non-participating defendants and certain Section 558 claims against specific agencies. But those partial defense wins do not alter the ruling's principal effect.

    The business story is still larger than one courtroom. The D.C. Circuit case remains live, the FASCSA designation still matters, and any serious assessment of Anthropic's position with government customers has to keep both tracks in view at the same time.

    Sources and Related Clearon Coverage

  • From a Stricken Filing to an $8,000 Fine: How Courts Calibrate Citation Failures

    From a Stricken Filing to an $8,000 Fine: How Courts Calibrate Citation Failures

    Three late-August federal orders are useful to read together because they show something easy to miss in the current discussion around AI-tainted filings.

    The issue is not just whether bad citations appeared in a filing.

    It is how courts sort out responsibility, procedure, candor, and remedy after that happens.

    The orders in Booker v. The Kroger Co., Adams v. Matrix Providers Inc., and In re Turgeon do not land in the same place. One involves admitted AI consultation and a direct sanctions order. One leaves AI causation unresolved while criticizing counsel's judgment and rule compliance. One involves a pro se debtor, no AI finding, and a stricken filing rather than a separate sanctions ruling. A fourth recent opinion, Snisko v. Cascade Funding Mortgage Trust HB4, adds another variation: a merits affirmance and a same-opinion show-cause order directed at counsel over allegedly fabricated quotations and misrepresentations. Read together, they show that even when AI is part of the background, the consequence still turns on human conduct and procedural posture.

    Booker: The Court Reached A Direct Rule 11 Sanctions Order

    Booker is the clearest of the three.

    In an August 28 Opinion and Order of Sanctions, Judge Steven D. Grimberg sanctioned plaintiff's counsel for using "fake or hallucinated case authorities" and for misrepresenting real authorities. The order also says counsel lied to the court about AI use.

    That candor point mattered.

    The court quoted its own standing order: lawyers may use whatever AI tools they like, but only human beings will be held responsible for the outcome. The order says counsel first denied using AI at the hearing, then later acknowledged that he had "consulted" AI tools. The court found that counsel had repeatedly lied to the court and used an "entirely disingenuous" explanation to minimize responsibility.

    The sanction was concrete and public. The court imposed $1,000 for each of four highlighted fake, false, or misleading authorities, then doubled that amount because of the lies to the court, for a total sanction of $8,000. It also ordered counsel to file documentation verifying the ethics and technology CLE training he said he had completed.

    The practical lesson is that citation failures can become materially more costly after the court concludes that counsel responded with evasion instead of candor, including by falsely denying AI use.

    Adams: The Court Criticized The Briefing, But The Remedy Was Narrower

    The August 27 order in Adams took a different path.

    Judge Charlotte N. Sweeney described serious problems in plaintiff's briefing, including a phantom citation to a nonexistent case, numerous inaccurate descriptions of case holdings, and repeated failures to support assertions with accurate record citations. The court also addressed counsel's explanation that Ricks v. Starbucks was included inadvertently during a family emergency while unnamed outside help and a paralegal assisted with finalizing the briefs.

    But the order stopped short of turning the whole episode into a sweeping AI sanctions opinion.

    The court expressly said it was unclear whether the briefing failures resulted from AI use or from "poor and unexacting legal judgment." Either way, the court found the conduct highly concerning. It also cited the Tenth Circuit's statement in Amarsingh v. Frontier Airlines that there is nothing inherently problematic about using GenAI in legal practice, while careless use can waste judicial resources and damage credibility.

    The court admonished Pearson over the citation failures. Its $1,000 monetary sanction, however, was framed around the courthouse-photography violation and repeated failure to follow local rules and practice standards, although the concluding sanction paragraph also cited Rule 11(c)(1). The order should not be read as assigning a $1,000 sanction specifically to the phantom citation.

    That is a useful distinction. A filing may contain AI-shaped defects without producing the kind of direct hallucination order that Booker delivered. Courts may instead fold the problem into a broader assessment of judgment, local-rule compliance, and lawyer conduct.

    Turgeon: The Court Struck The Filing And Focused On Case Management

    Turgeon is different again.

    The New Hampshire district court affirmed the bankruptcy court's dismissal of the debtor's Chapter 13 case. In recounting the record, the order explains that the bankruptcy judge questioned the debtor about "false, hallucinated case citations" in an objection to the trustee's motion to dismiss, found the citations inaccurate and misleading, and struck the objection.

    The opinion also notes that the debtor was given a chance to cure by filing an amended objection and did not do so.

    What matters here is what the court did not do. This was not a separate Rule 11 sanctions order. The district court did not treat the citation defects as a basis for dismissal. It held that the bankruptcy court could strike the objection under § 105(a), emphasized the two-week opportunity to amend, and rejected the due-process challenge after Turgeon failed to cure. The Chapter 13 dismissal rested on separate plan-filing and delay grounds.

    That makes Turgeon a reminder that citation problems do not always become standalone sanctions opinions. Sometimes they appear as part of a court's effort to manage the docket and police misleading filings without converting the dispute into a separate sanctions proceeding.

    Snisko: The Merits Can End And The Citation Fight Can Still Begin

    Snisko contributes a narrower but useful procedural point.

    In the same August 19 opinion that affirmed the bankruptcy court's abstention ruling, Judge Manish S. Shah separately ordered appellant's counsel to show cause why he should not be sanctioned for fabricated legal citations and other misrepresentations. The opinion said the brief was "replete with false quotations and erroneous statements of law," identified apparent quotations that do not appear in cited cases including In re Aguirre and In re Boughton, and said counsel "doubled down" in the reply after the defects had been flagged.

    The order does not make an express AI finding. That is part of why it matters. It shows that a court does not need to resolve how the errors were produced before opening a sanctions track. It also shows that citation risk can survive the merits, or in this case be embedded in the same opinion that resolves them.

    The Pattern Is Human Accountability, Not Tool Liability

    Taken together, the three orders tell a more useful story than a generic warning not to trust AI.

    They show that courts are still applying familiar legal ideas:

    • responsibility attaches to the signed filing;
    • candor after an error can materially affect sanction severity;
    • procedural posture can shape whether the outcome is a Rule 11 sanction, a local-rule sanction, a stricken filing, a same-opinion show-cause order, or some combination; and
    • the court does not need a grand theory of AI causation before acting.

    That is why the recent AI filing cases should not be read as a separate body of exotic law. They are mostly ordinary supervision, certification, and litigation-conduct rules applied to a new source of error at scale.

    What Law Firms Should Change

    The control problem is not just whether a tool generated a fake case name.

    It is whether the workflow catches:

    • nonexistent authorities;
    • real authorities used for false propositions;
    • quotations that do not appear in the source;
    • inaccurate record references;
    • misleading procedural narratives; and
    • bad post-error responses that make the situation worse.

    The second control point is escalation. Once a court or opposing party flags a possible hallucination or fake authority, the matter should leave ordinary drafting flow and move into a higher-review path led by a supervising lawyer. That follow-up needs independent source verification, a clean explanation of what happened, and absolute candor with the court.

    Booker shows what happens when that second step fails. Snisko shows that simply repeating the challenged position after notice can deepen the problem even before a sanctions amount is set. Booker also shows that a court may reserve whether further sanctions are warranted while requiring proof of the remedial training counsel says he has completed.

    Bottom Line

    The late-August orders do not create a single AI doctrine under Rule 11.

    They do show a stable principle.

    Courts still care most about the human choices around the filing: who signed it, who checked it, how the lawyer responded when the defects surfaced, and whether the court's rules were taken seriously. AI may explain how the error entered the draft. It does not replace the lawyer who owns the result.

    Sources and Related Clearon Coverage

  • DOJ Urges Court To Treat LLM Training as Fair Use in OpenAI Copyright Case

    DOJ Urges Court To Treat LLM Training as Fair Use in OpenAI Copyright Case

    On September 1, 2026, the United States filed a Statement of Interest in the consolidated OpenAI copyright litigation in the Southern District of New York, urging the court to reject arguments that training LLMs on copyrighted texts violates copyright law.

    That is a formal executive-branch litigation position, not a ruling, and it leaves acquisition and output questions aside.

    It is also more aggressive than a casual policy remark and narrower than the bluntest headlines make it sound.

    The government's filing does not say every use of copyrighted material by an AI company is lawful. It separates the pipeline into acquisition, training, and output, then says the United States is focused on whether the use of copyrighted works at the training stage constitutes fair use.

    That distinction is doing real work.

    What The Government Actually Asked The Court To Do

    The filing is a Statement of Interest under 28 U.S.C. § 517, not a merits ruling and not a government complaint against anyone. It is the executive branch telling Judge Sidney Stein how it thinks federal copyright law should be applied in this litigation.

    Its central ask is hard to miss. The brief says the United States has a strong interest in the court rejecting any argument that training LLMs on copyrighted texts violates copyright law.

    The government then frames LLM development as a staged process:

    • acquisition of data;
    • model training; and
    • model outputs.

    The brief says each stage may present distinct copyright questions. But the United States limits its own position to the training stage, defined as copying works in order to feed data into the model as learning material.

    That means the filing is best understood as an effort to establish a strong presumption for training-stage fair use while leaving acquisition and output practices for separate analysis.

    Why This Is More Than A Repackaged Talking Point

    The administration had already stated in its March 2026 National Policy Framework for Artificial Intelligence that training an LLM on copyrighted material, "in and of itself," does not violate copyright law. A July 2026 DOJ journal article also addressed the doctrine, but it expressly disclaimed that the authors' views necessarily reflected DOJ policy.

    This filing is different.

    It is a formal Department of Justice submission in pending federal litigation. It was submitted under a signature block listing Associate Attorney General Stanley Woodward Jr. and Civil Division Assistant Attorney General Brett Shumate, and signed by Senior Counsel Michael Weisbuch. That does not make it controlling law, but it does make it a real statement of the executive branch's litigation position in this case.

    So the legal significance is not that the issue is now settled. It is that a federal court now has before it an express government argument that OpenAI's training use is fair use and that courts should reject a rule generally making LLM training impermissible without licensing.

    The Fair-Use Theory The Government Is Pushing

    The brief leans heavily on the idea that copyright law must distinguish among uses rather than flatten every copy into the same category.

    That is why it emphasizes a use-by-use analysis and relies on cases like Authors Guild v. Google and Google v. Oracle America. The basic argument is familiar but now stated at full executive-branch volume: copying during training is transformative because it uses works as learning material to develop a model that recognizes patterns and relationships rather than to distribute the original works as a substitute library.

    The filing's language gets especially strong in its fourth-factor discussion. It says OpenAI's model training using New York Times articles is fair use and argues that the training copy does not serve as a substitute for the original or shrink protected market opportunities in the relevant copyright sense.

    That is a more aggressive proposition than merely saying the law is unsettled.

    The brief also frames a contrary rule as harmful to innovation, scientific progress, and U.S. competitiveness. It argues that broad copyright liability for training would hamper AI development under a misunderstanding of fair use doctrine.

    The Filing's Sharpest Move Is Its Attack On Kadrey

    The most consequential doctrinal section may be the government's critique of Kadrey v. Meta Platforms.

    The filing says the Kadrey court, "without the benefit of briefing," adopted an "indirect substitution" theory of "market dilution" based on the possibility that LLMs might create books competing with human-authored books. The government argues that this approach is untethered from the core copyright inquiry because it conflates training copies, which are not publicly accessible, with outputs, which may be accessible but will often lack substantial similarity.

    That matters because the fourth fair-use factor has become one of the main battlegrounds in AI copyright cases.

    If courts accept a broad market-dilution theory, many AI developers could face a much harder path on fair use even when their models are not outputting close substitutes for specific source works. If courts instead require a tighter connection between the challenged use and legally cognizable substitution, training-stage defendants get much more room.

    So the filing is not just defending OpenAI's posture in one case. It is trying to narrow one of the strongest emerging theories plaintiffs have used against AI training.

    The Government's Policy Case Is Broader Than Doctrine

    The filing also makes an overt policy argument about structure and competition.

    It says an erroneous ruling against fair use would hamper competition in the LLM market because only the largest technology companies might have the capital to pay universal licensing fees. It also says such fees would disproportionately benefit legacy media outlets because of the sheer volume of their written publications.

    Then the filing makes the point in blunter terms: it is not in the public interest for the largest technology companies to have an oligopoly on LLM training due to licensing entry barriers that function primarily as subsidies for old mainstream media companies.

    That argument will be attractive to many AI companies and many policymakers who worry about incumbency barriers.

    It is also not the whole story.

    In a footnote, the government says it takes no position on whether a licensing regime would actually be financially or logistically feasible. So the filing is clearly hostile to broad mandatory licensing as a legal consequence of the case, but it stops short of claiming to have solved the practical licensing debate.

    What The Filing Does Not Resolve

    This is where readers should slow down.

    The government did not ask the court to bless pirated acquisition or infringing outputs. The filing expressly separates those questions from the training-stage issue it wants resolved.

    That means several high-stakes questions remain open even if the court finds the filing persuasive:

    • how the copyrighted works were obtained;
    • whether retained libraries or other collection-stage conduct raises separate infringement problems;
    • whether RAG or output behavior can create substitution or substantial-similarity issues;
    • whether training on some categories of works presents different market-harm facts from others; and
    • whether courts will accept or reject broader theories of lost licensing markets.

    Those limits matter even more because the U.S. Copyright Office's May 2025 prepublication Part 3 report takes a more qualified approach.

    The Office says various uses of copyrighted works in AI training are likely to be transformative. But it immediately adds that the result depends on what works were used, from what source, for what purpose, and with what controls on the outputs. It also warns that making commercial use of vast troves of copyrighted works to produce expressive content that competes with them in existing markets, especially through illegal access, can go beyond established fair-use boundaries.

    That report predates this filing. DOJ addresses it directly in footnote 17, arguing that similar market-dilution reasoning deserves no deference and overlooks the required use-by-use analysis.

    That is not a direct rejection of DOJ's position. But it is a reminder that the government has advanced one strong reading of fair use, not the only plausible one, and the filing itself says the fair-use inquiry still turns on the specific facts and uses at issue in each case.

    Why This Matters Beyond OpenAI

    This filing lands in the middle of a larger litigation map that includes authors, publishers, answer-engine disputes, training-data fights, and increasingly explicit market-substitution theories.

    That broader setting matters because the filing is trying to influence not just one factual record but the legal frame that future courts may use.

    If Judge Stein embraces the government's approach, the training-stage fair-use defense gets a much firmer doctrinal platform in one of the most important AI copyright proceedings in the country. If he does not, the executive branch will still have shown the argument it wants courts to take seriously: separate training from acquisition and outputs, reject generalized market-dilution theories, and treat transformative training use as consistent with copyright's constitutional purpose.

    Either way, the filing gives courts and litigants a cleaner version of the pro-training position than they had before.

    Bottom Line

    DOJ did not tell a court that everything about AI companies' use of copyrighted material is lawful.

    It did something narrower and more important.

    It told the Southern District of New York that OpenAI's training use is fair use and that training LLMs on copyrighted texts should not, in general, be treated as copyright infringement. At the same time, it left acquisition and output questions for separate analysis and did not claim every training use in every case will necessarily come out the same way.

    The fight now is over whether courts will accept that carveout, and how sharply they will separate training from the acquisition and output questions DOJ left unresolved.

    Sources and Related Clearon Coverage

  • What IPWatchdog’s Video-Game AI Warning Reveals About State AI Laws

    What IPWatchdog’s Video-Game AI Warning Reveals About State AI Laws

    Gene Quinn's new IPWatchdog Unleashed article recounts his conversation with Bijou Mgbojikwe, senior policy counsel at the Entertainment Software Association, about a central scoping problem: laws aimed at harmful deepfakes can sweep together licensed digital replicas, fictional game content, and other materially different uses. Their discussion deserves direct attention, and Clearon's tracker shows why.

    Full credit to IPWatchdog, Gene Quinn, and Bijou Mgbojikwe. The article is worth reading in full, and the related podcast and YouTube versions are worth watching or listening to as well.

    The core point is simple and important. Lawmakers often talk about deepfakes, digital replicas, AI disclosures, and harmful deception as though they were one problem with one obvious fix. They are not.

    That matters because Clearon's tracker already shows several different regulatory models moving at once. Some are relatively narrow and tied to a concrete harm. Others use broader synthetic-media or deception concepts that become much harder to apply cleanly once they reach expressive content, fictional environments, or ordinary digital creativity.

    The IPWatchdog Point Deserves Serious Attention

    Gene Quinn's writeup of his conversation with Bijou Mgbojikwe frames the issue more carefully than much of the broader AI-regulation commentary does.

    The concern is not that lawmakers should ignore fraud, impersonation, child safety, or deceptive synthetic media. The concern is that a rule designed for one misuse case can spill outward if it defines the covered content too broadly or treats every realistic AI-generated output as though it presents the same risk.

    That is especially important for games and other expressive media. A law aimed at deceptive political media, nonconsensual sexual deepfakes, or misleading advertisements does not necessarily fit a fictional game world, a synthetic background character, a stylized voice clone used with rights clearance, or a digital replica embedded in a licensed creative work.

    Our Tracker Already Shows At Least Three Different Regulatory Models

    The current watchlist and published tracker notes show why this should not be treated as a single undifferentiated "AI content" category. The laws we track already fall into materially different buckets.

    1. Narrower disclosure rules tied to a specific context

    New York's synthetic-performer advertising law is the clearest example of a narrower approach.

    As tracked in Clearon's published coverage, New York now requires disclosure when advertisements include AI-generated performers. That is a targeted rule aimed at a concrete commercial context. It is more readily confined to an identifiable commercial context than a broad rule that treats any realistic synthetic character or voice as inherently suspect across every setting.

    This is the kind of example that supports the IPWatchdog point. A narrowly framed disclosure rule for advertising is very different from a generalized rule that could bleed into expressive media or product design.

    2. Broader anti-forgery and persona-protection measures

    Pennsylvania's Act 35 of 2025 and Ohio's pending HB 185 show a different lane.

    Pennsylvania's tracked law is a broader digital-forgery measure, not just an election-deepfake statute. Act 35 addresses digital forgery through an enacted criminal framework tied to statutory intent requirements. Ohio's HB 185, which remains pending, would separately revise persona-use law and prohibit certain unauthorized deepfake recordings. Both raise scoping questions, but they regulate different conduct through different legal mechanisms.

    That does not make them illegitimate. It does mean product teams, publishers, and counsel should ask harder scoping questions before assuming the rule cleanly maps to a game or creative-AI product:

    • Is the law keyed to deception, consent, and impersonation?
    • Does it distinguish commercial misuse from expressive use?
    • Does it turn on a real person's identity, or on synthetic realism more generally?
    • Does it leave room for licensed, parodic, or otherwise protected creative work?

    Those distinctions matter a great deal in games, where character design, voice synthesis, likeness licensing, machinima-style content, and user-generated creations can all sit near the line.

    3. Definition-heavy laws where carveouts and context do a lot of work

    The election-deepfake statutes we track are not video-game laws, but they are still useful cautionary examples.

    Clearon's comparison work already shows that California's AB 2655 and AB 2839 and New Mexico's HB 182 do not all solve the same problem in the same way. They use different combinations of prohibition language, disclosure mechanics, and satire/parody treatment.

    California's measures are enacted, but their current enforcement posture is materially constrained by federal-court rulings. New Mexico's enacted HB 182 is also the subject of pending constitutional litigation. They remain useful drafting examples, not interchangeable statements of currently enforceable law.

    That is the kind of drafting variation that can become decisive once a plaintiff argues that a law reaches protected expression more broadly than lawmakers intended. Even outside elections, the lesson carries over: if the operative definition is too blunt, the exceptions and carveouts end up doing enormous work, and courts may decide they do not do enough.

    For game publishers and digital-content companies, that is the real operational warning. The hardest laws are not always the ones with the harshest rhetoric. They are often the ones whose definitions, exceptions, and disclosure triggers do not map cleanly onto the actual product context.

    What Game and Creative-AI Companies Should Be Asking

    The practical question is not whether regulation is coming. It is what category of regulation a product is most likely to attract, and whether the legal theory behind that category actually matches the feature being built.

    Companies building or distributing AI-enabled creative tools, games, avatars, voice systems, or synthetic-character features should be able to answer:

    1. Is the main risk advertising deception, persona misuse, election content, consumer confusion, or some other category?
    2. Does the feature involve a real person's likeness, voice, or identifying traits?
    3. Is the output licensed, fictional, user-directed, editorial, or platform-distributed at scale?
    4. Would a required disclosure actually reduce a real risk, or would it simply create warning fatigue?
    5. If a law uses a broad synthetic-media definition, what part of the product would be exposed first?

    That is where the tracker becomes more useful than a generic AI-policy debate. The tracked laws show that states are already choosing different regulatory instincts depending on whether the perceived harm is fraud, identity appropriation, political deception, chatbot dependence, or unsafe decision-making.

    Read The IPWatchdog Piece And Watch The Episode

    This is one of those source pieces that deserves direct attention rather than only secondhand summary.

    If you care about how AI rules could land on games, digital replicas, creative tools, and software products built around expressive content, read Gene Quinn's article at IPWatchdog. Then watch or listen to the full IPWatchdog Unleashed conversation with Bijou Mgbojikwe through the podcast feed or the IPWatchdog YouTube channel.

    Quinn's article and Mgbojikwe's analysis ask the right scoping question: how do you target real harm without writing rules so broadly that they interfere with lawful creative work, protected speech, or normal product design?

    Bottom Line

    The regulatory pressure that IPWatchdog is describing is not theoretical. Clearon's tracker already shows it.

    Some laws are narrow and context-specific, like New York's advertising disclosure rule. Some are broader anti-forgery or persona-protection measures, like Pennsylvania's Act 35 and Ohio's pending HB 185. Others show how fast disclosure mechanics, prohibition language, and carveouts can become messy once lawmakers move from a headline harm to statutory text.

    For companies in games and expressive AI, the principal mistake is treating every rule that uses the word "deepfake," "replica," or "AI" as though it targets the same conduct. Product teams need to examine the covered harm, statutory elements, exceptions, and current enforcement posture.

    Sources and Related Clearon Coverage